Type a section name and press Enter. Use “help” for the list.
Cliste experiment
The learned video predictors did not beat VSA interpolation
Registered 11 Oct 2026 · Snapshot 12 Oct 2026
The question
Qualify a spatial VSA conversion, then compare moving experienced content with predicting new content between recorded video endpoints.
Why this experiment?
Missing-pixel prediction did not establish coherent construction. Video endpoints provide another concrete question: can a mechanism construct an intermediate scene while using the shared VSA interface?
How it works
Qualify the conversion between VSA and constructor features, fit transport and direct-synthesis models on training videos, and supply only the two endpoints at test time. Assess the withheld middle against the learned outputs and interpolation controls.
Follow this part of the investigation: Which mechanism should construct new visual content? →Implementation and comparison details
Use a fixed visual codec and whole-video source splits. Both learned candidates receive the same endpoint-derived fields and timing; every prediction is recomposed into full-dimensional VSA before rendering.
What happened
Both clean-conversion gates passed. Compared with VSA interpolation, error where endpoints differ was 8.2% higher for learned transport and 4.3% higher for synthesis; whole-image error was 2.7% and 2.4% higher. Neither constructor qualified. All 32 reviewed examples preserve recognizable scenes, but neither method shows a consistent visual advantage; moving contours often remain doubled or blurred.
Results and visual artifacts
Open a figure for its input, comparison, and result. Click an image to enlarge it.
The input preview remains available, followed by all 32 test sheets. The conversion row receives information from the true middle; every construction output uses only the endpoints. The label “diagnostic ceiling” denotes a privileged actual-encoder-field reference, not a guaranteed upper bound. All saved candidates are shown. The complete assistant review is nonblinded and does not treat reference mismatch alone as incoherence. This public record includes 2 of 33 saved figures: summary comparisons and fixed examples, including every figure referenced by the guide. Reported aggregates include every case; individual records and complete outputs remain in the research archive.
What the training examples contain
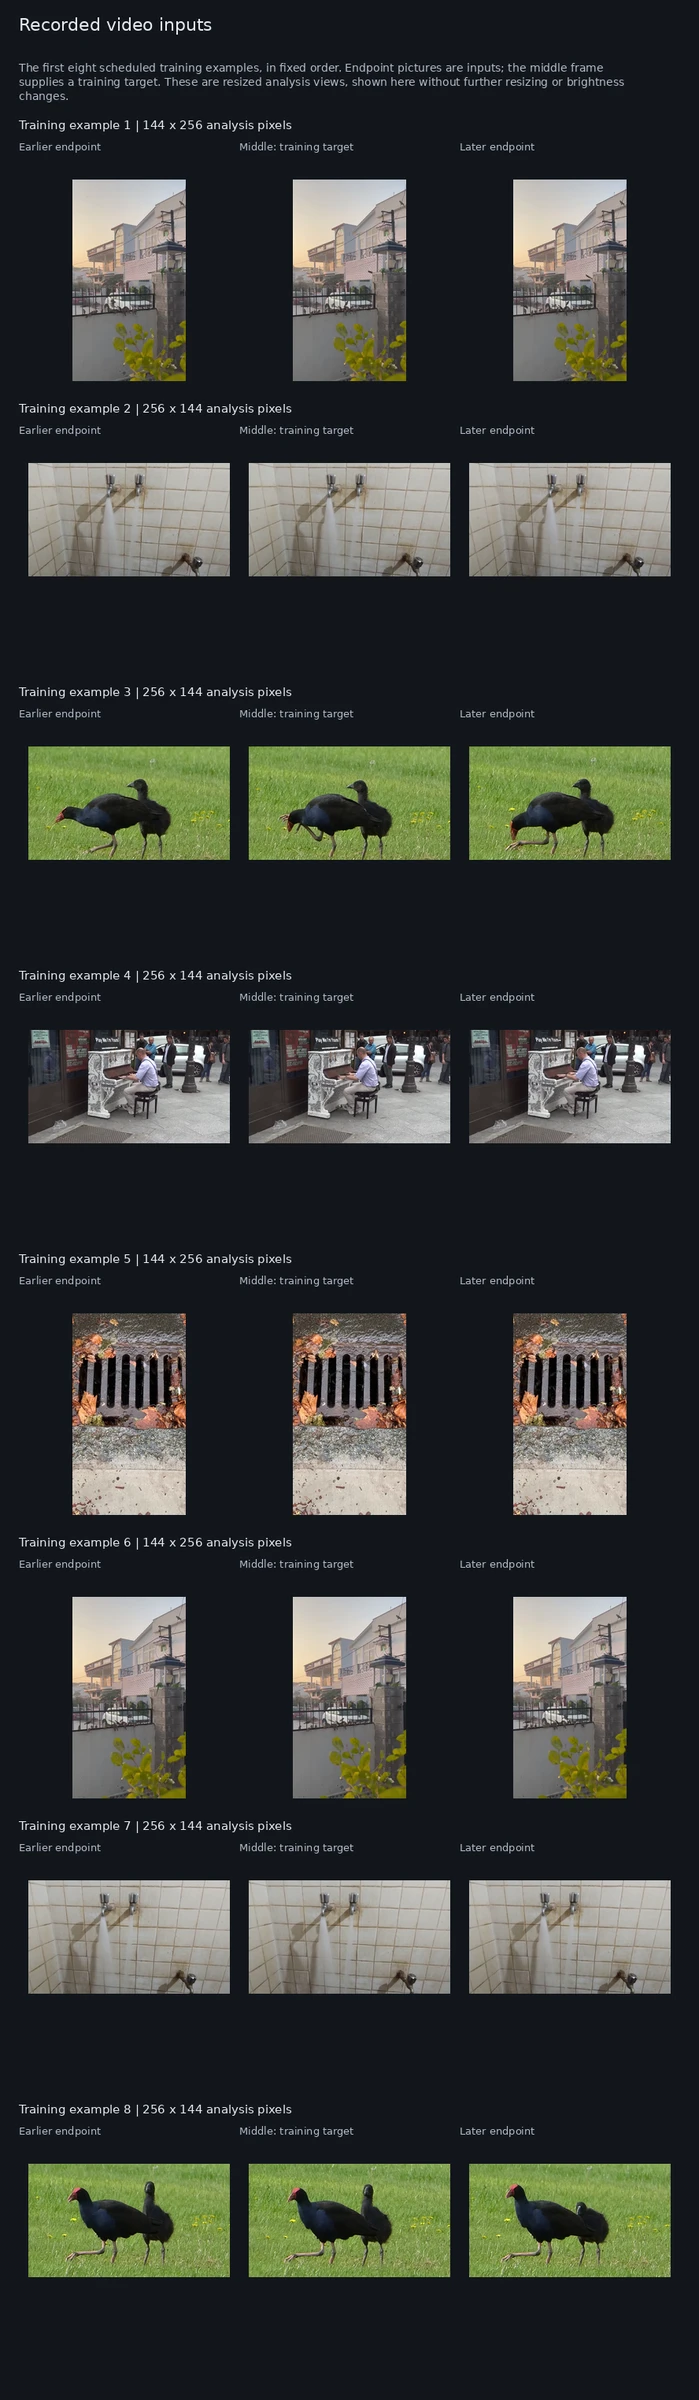
Display derivative: WebP quality 90; maximum edge 2400 px. Original scientific pixels remain in the source run; do not measure this preview.
Video example 1: every saved result
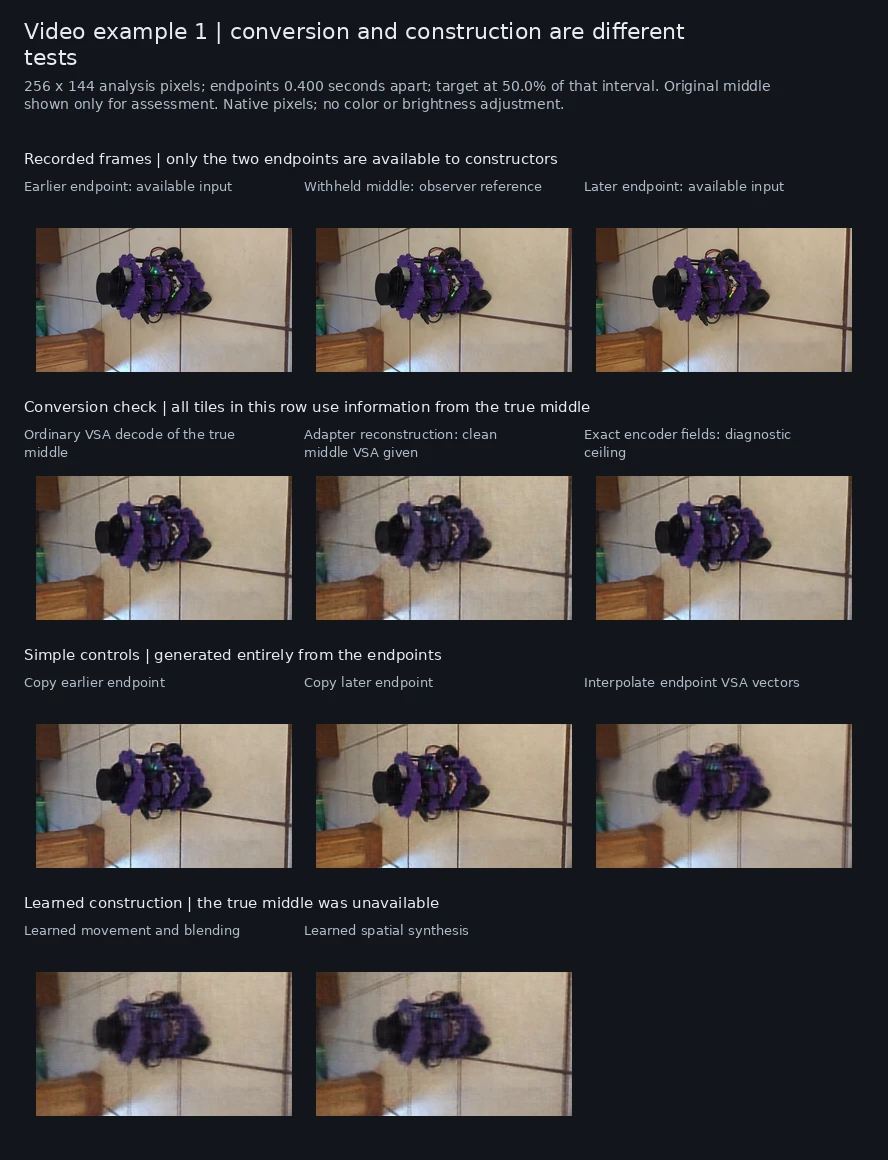
Display derivative: WebP quality 90; maximum edge 2400 px. Original scientific pixels remain in the source run; do not measure this preview.
Limits and next question
A small pilot using nine previously available videos, with two test source videos. Frames within a video are related observations. Analysis images are resized to at most 256 pixels on the long side. This is neither free-form imagination nor language grounding.
Next question. Separate the cost of VSA-to-feature conversion from temporal learning before nominating a construction architecture; the registered comparison lacks an untrained field-interpolation control through the same adapter.
Inspect the evidence
Download the methods and measurements for this experiment. Large training and saved-state files are not included.