run record~/research/cliste/runsAll Cliste runs

Type a section name and press Enter. Use “help” for the list.

Figures: softened for dark viewingDisplay only; image files are unchanged.
← All Cliste runs

Cliste experiment

Decoder refinement with a fixed encoder

Execution: completedScientific verdict: material improvement

The question

Improve perceptual readout by refining only the decoder of fixed refined-encoder VSA vectors, while measuring actual stored-memory readback separately.

Why this experiment?

A memory can only preserve what its sensory interface encodes. These studies separate encoder quality, decoder quality and compatibility with earlier stored vectors.

How it works

Change one component or input representation at a time and evaluate immediate reconstruction on separate images. Keep old-vector readback visible so gains on new inputs do not hide compatibility losses.

Follow this part of the investigation: Sharper perception can also change the language of memory →
Implementation and comparison details

Only the 12 decoder lift/painter parameter tensors learn. The refined encoder, position codes, all normalization running statistics, VSA operations and input resolution stay fixed. Both decoders receive identical vectors; actual old stored vectors are evaluated separately from re-encoded observations. Original, zero-rate and vector-dependence controls are retained.

What happened

Photo fidelity improved modestly: COCO MSE 6.19% lower (95% interval 6.05–6.34%), Flickr 5.83% lower; edge error also improved. Writing on white regressed 12.12%, with every example worse in every seed. Actual old-vector readback regressed 4.96–6.45% overall and 8.25–11.45% for Dune. All 39 integrity checks passed, but the candidate is unsuitable as an unconditional general-decoder replacement. Earlier lives retain their original models. Independent audit passed 360/360 checks; all 854 repository tests and required static/viewer checks passed.

Decoder-only refinement: material_improvement; primary MSE reduction 6.19%, 95% interval [6.05%, 6.34%]. Edge detail: improvement.

Measurements
Measurements — values preserved from this run
Recorded fieldValue
primary relative gain0.061930945876963905
primary ci95
[
  0.06048299136505278,
  0.06339958640301797
]
external relative gain0.05826819104086278
edge verdictimprovement
checks passed39
checks total39
training seeds3
display armseed-202
stored memory material regressionPass
Recorded checks
Recorded checks — values preserved from this run
Recorded fieldValue
registered files unchangedPass
optimization controlsPass
selected vector dependencePass
selected encoder outputs exactPass
previous lives and evidence unchangedPass
training cache equivalencePass
final cache equivalencePass
baseline fixed tensors exactPass
baseline all finitePass
baseline production reload equivalentPass
baseline test coco encoded vectors exactPass
baseline test flickr encoded vectors exactPass
baseline replay encoded vectors exactPass
baseline writing white encoded vectors exactPass
baseline writing photo encoded vectors exactPass
seed-101 fixed tensors exactPass
seed-101 all finitePass
seed-101 production reload equivalentPass
seed-101 test coco encoded vectors exactPass
seed-101 test flickr encoded vectors exactPass
seed-101 replay encoded vectors exactPass
seed-101 writing white encoded vectors exactPass
seed-101 writing photo encoded vectors exactPass
seed-202 fixed tensors exactPass
seed-202 all finitePass
seed-202 production reload equivalentPass
seed-202 test coco encoded vectors exactPass
seed-202 test flickr encoded vectors exactPass
seed-202 replay encoded vectors exactPass
seed-202 writing white encoded vectors exactPass
seed-202 writing photo encoded vectors exactPass
seed-303 fixed tensors exactPass
seed-303 all finitePass
seed-303 production reload equivalentPass
seed-303 test coco encoded vectors exactPass
seed-303 test flickr encoded vectors exactPass
seed-303 replay encoded vectors exactPass
seed-303 writing white encoded vectors exactPass
seed-303 writing photo encoded vectors exactPass

Results and visual artifacts

Open a figure for its input, comparison, and result. Click an image to enlarge it.

The encoder converts pixels into a VSA vector; the decoder turns that vector back into pixels. Only the decoder is trained in this experiment. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Development examples help select a model; final test examples assess that selected model. Training-control examples deliberately test whether fitting works. “Replay” re-encodes earlier images with the fixed current encoder; “stored replay” decodes the actual older memory vectors. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.

COCO test photographs: effect of decoder refinement
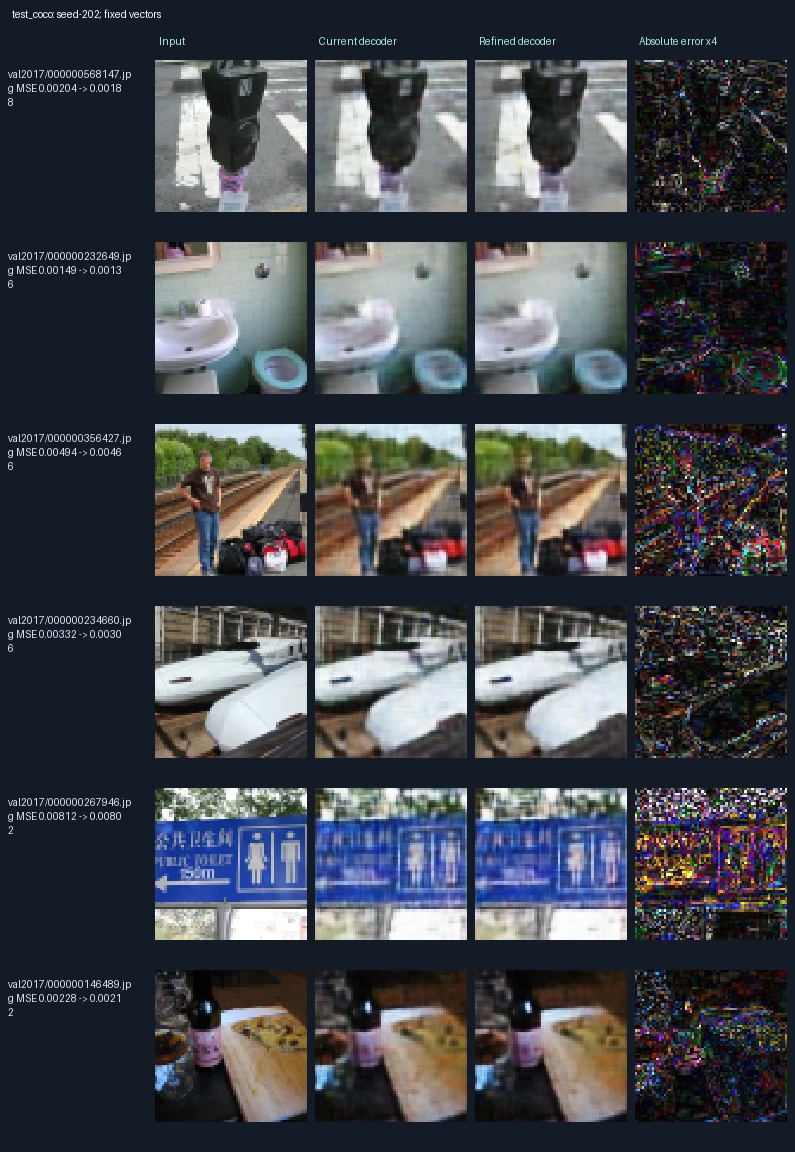
The first six test examples in predetermined order, not selected for reconstruction quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: largest gains on test photographs
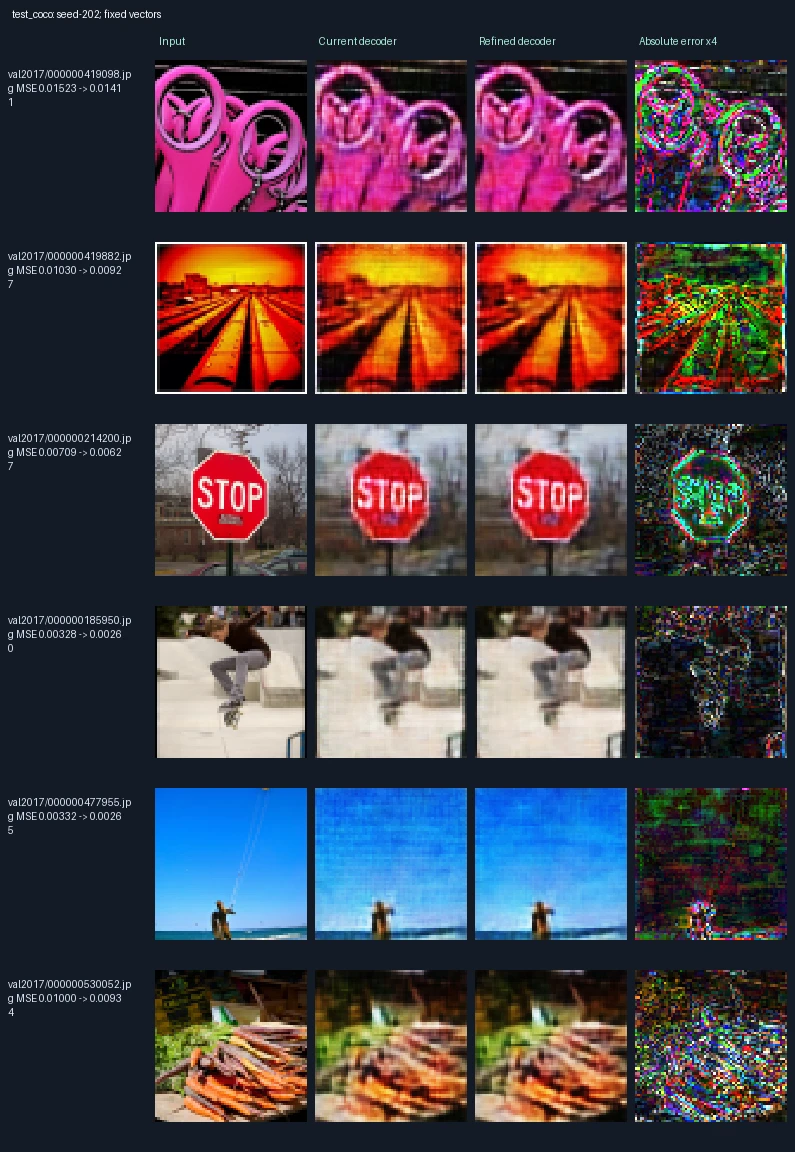
The six COCO test images with the largest decrease in MSE, selected after evaluation to expose the range of effects. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: smallest gains on test photographs
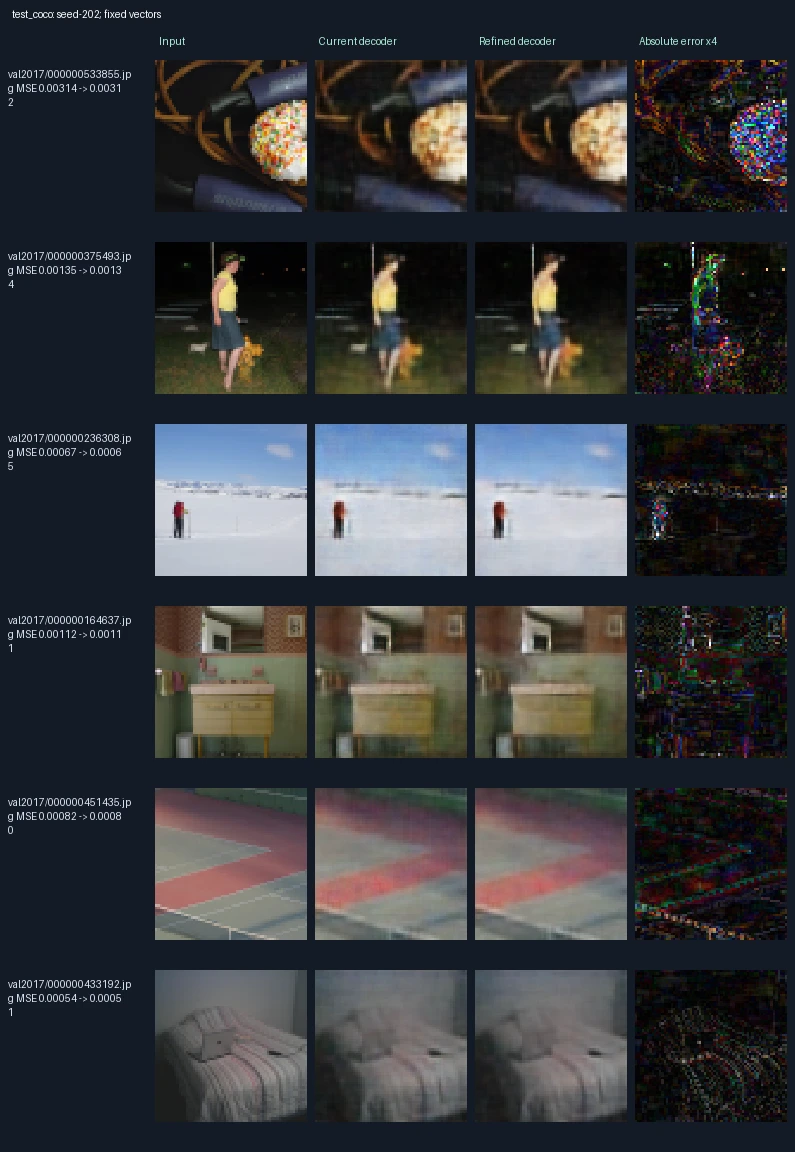
The six COCO test images with the smallest decrease in MSE, selected after evaluation to expose the range of effects. All six improved; the panel does not show regressions. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Flickr test photographs: effect of decoder refinement
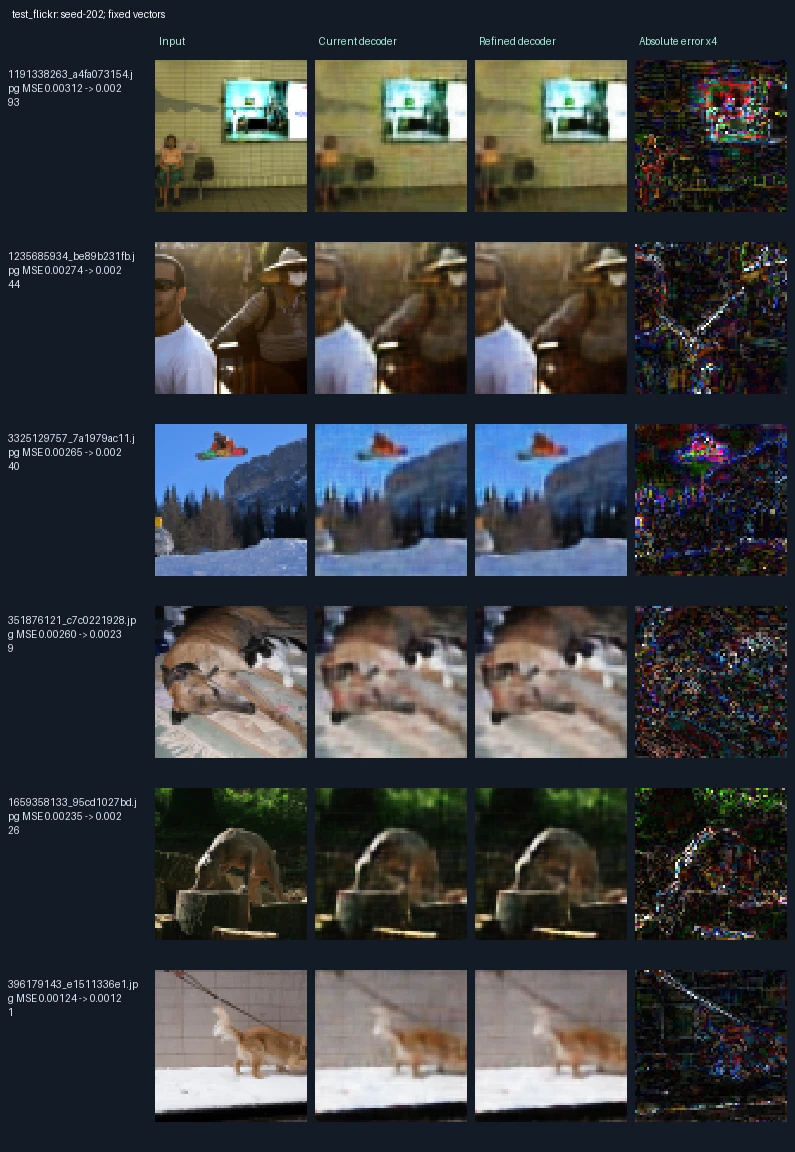
The first six test examples in predetermined order, not selected for reconstruction quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: encoding earlier photographs again 0–5
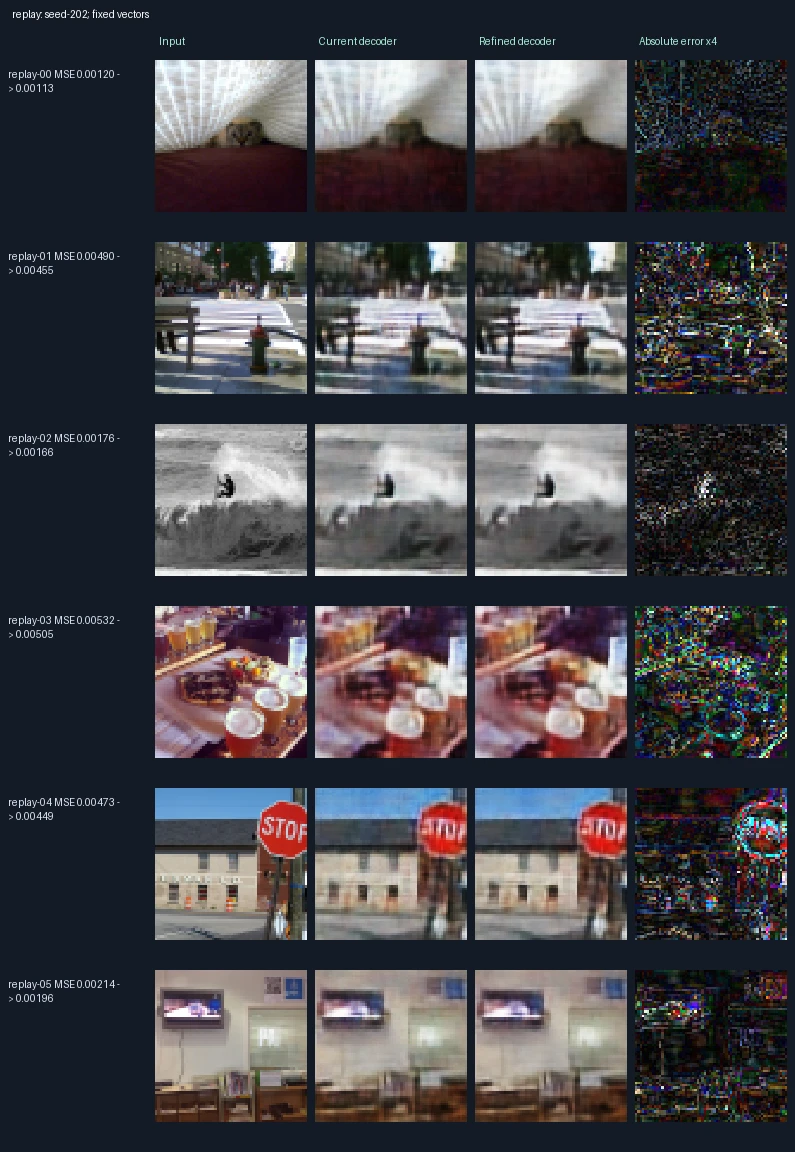
Earlier images are encoded again and immediately decoded. This tests reconstruction of familiar content; it does not show that untouched old memories remain compatible. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: encoding earlier photographs again 6–11
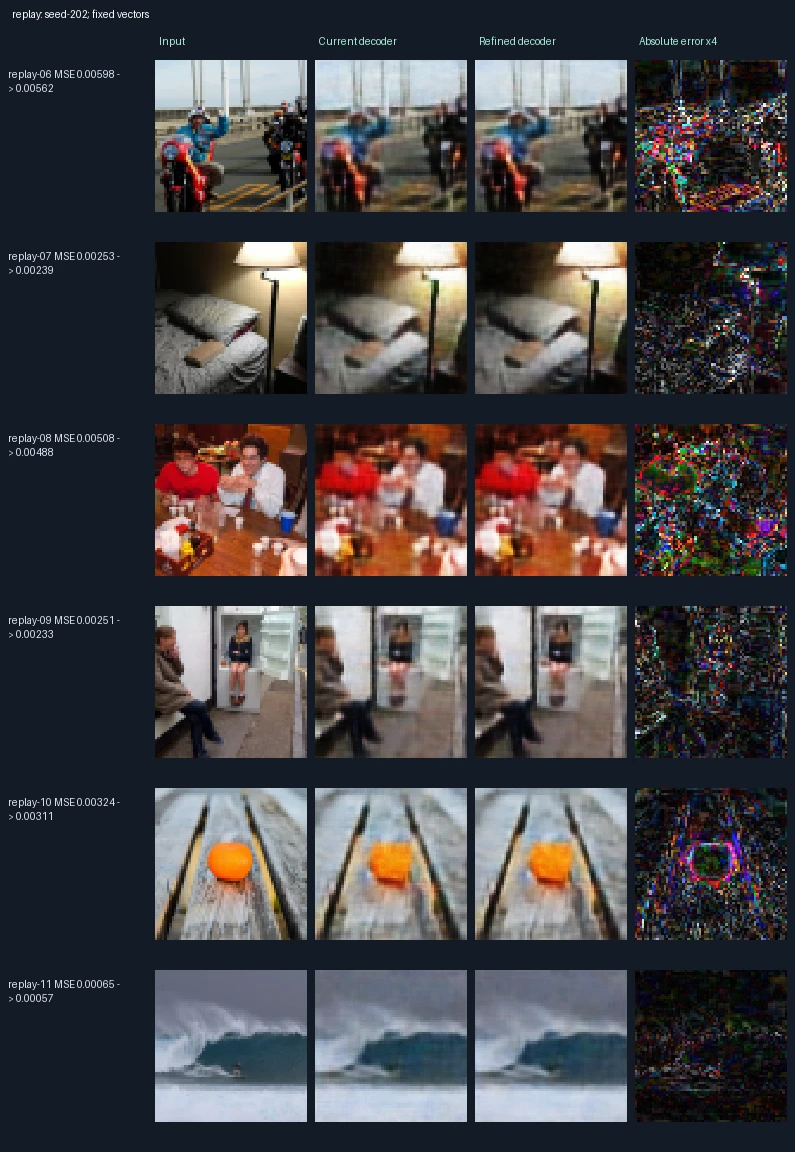
Earlier images are encoded again and immediately decoded. This tests reconstruction of familiar content; it does not show that untouched old memories remain compatible. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: encoding earlier photographs again 12–17
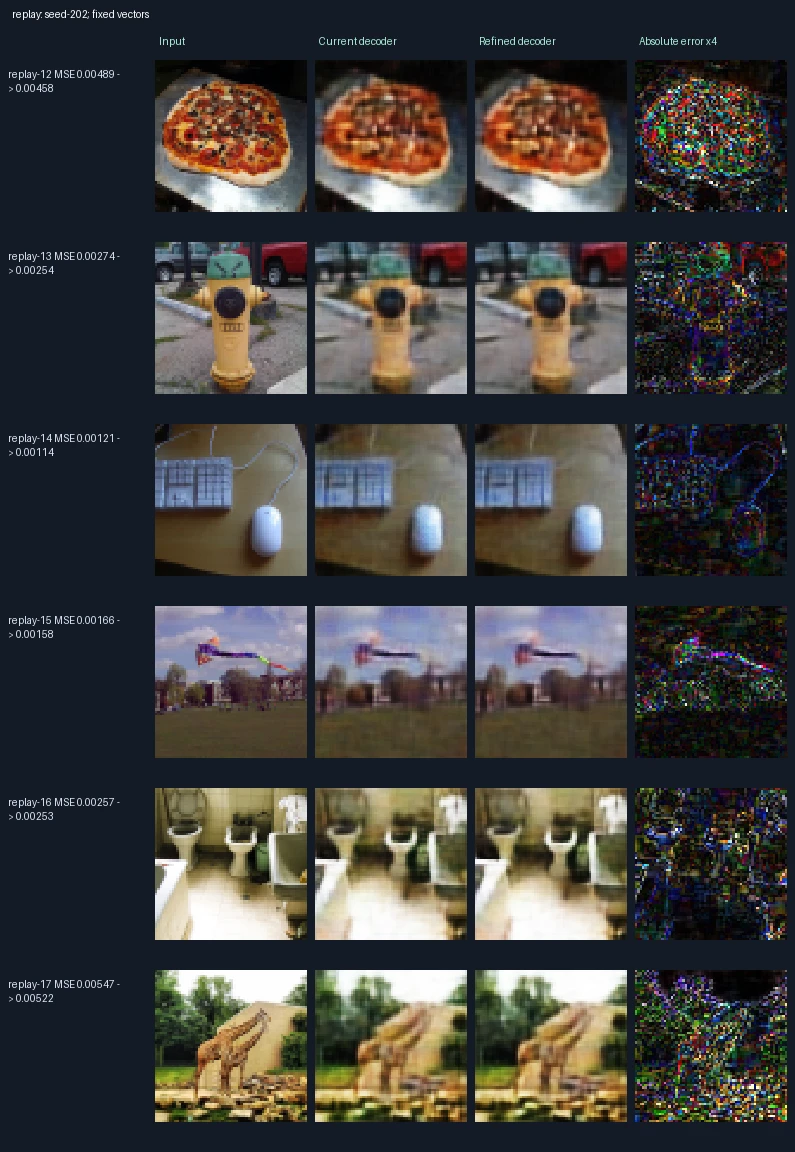
Earlier images are encoded again and immediately decoded. This tests reconstruction of familiar content; it does not show that untouched old memories remain compatible. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: encoding earlier photographs again 18–23
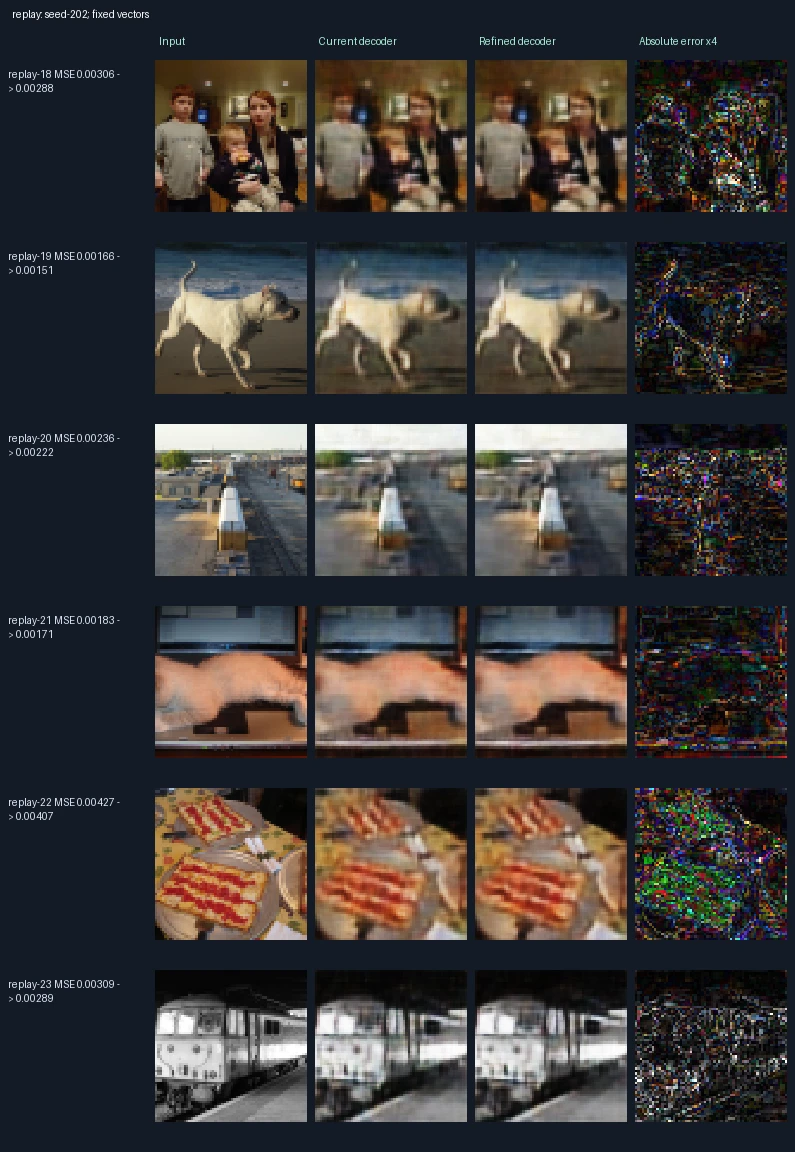
Earlier images are encoded again and immediately decoded. This tests reconstruction of familiar content; it does not show that untouched old memories remain compatible. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: encoding earlier Andor video frames again 24–29
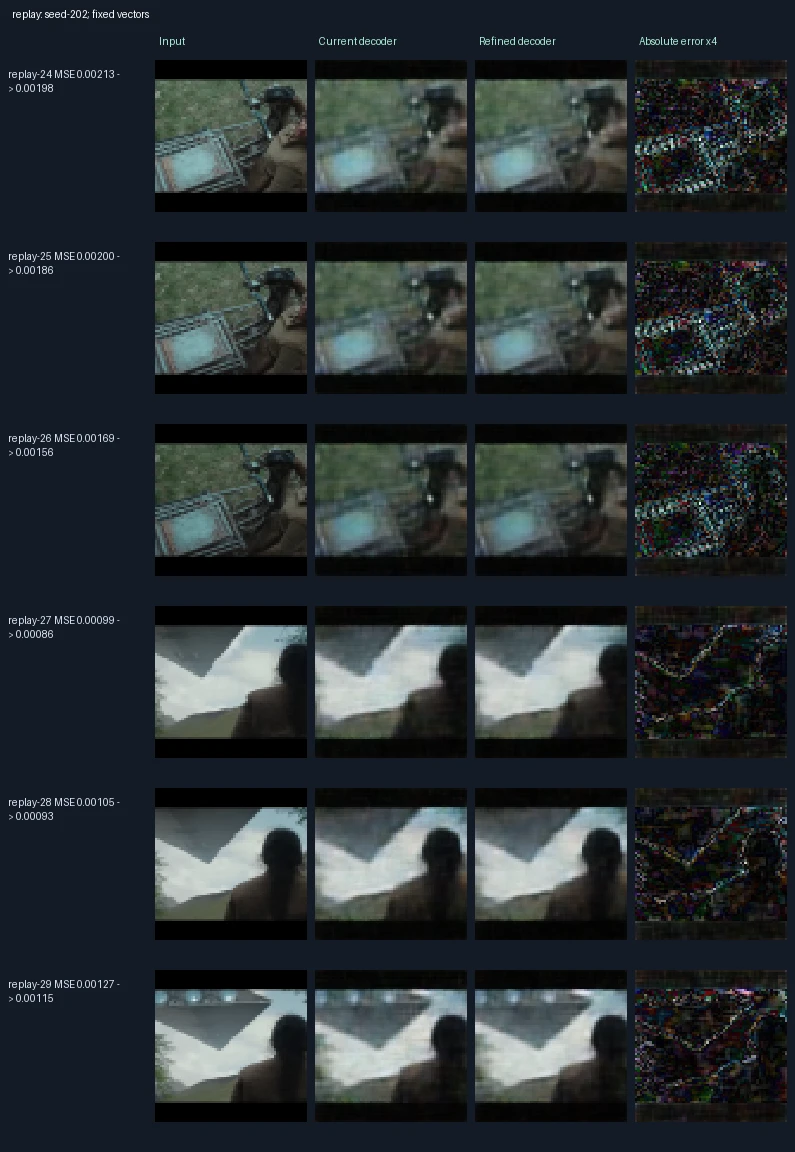
Earlier images are encoded again and immediately decoded. This tests reconstruction of familiar content; it does not show that untouched old memories remain compatible. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: encoding earlier Andor video frames again 30–35
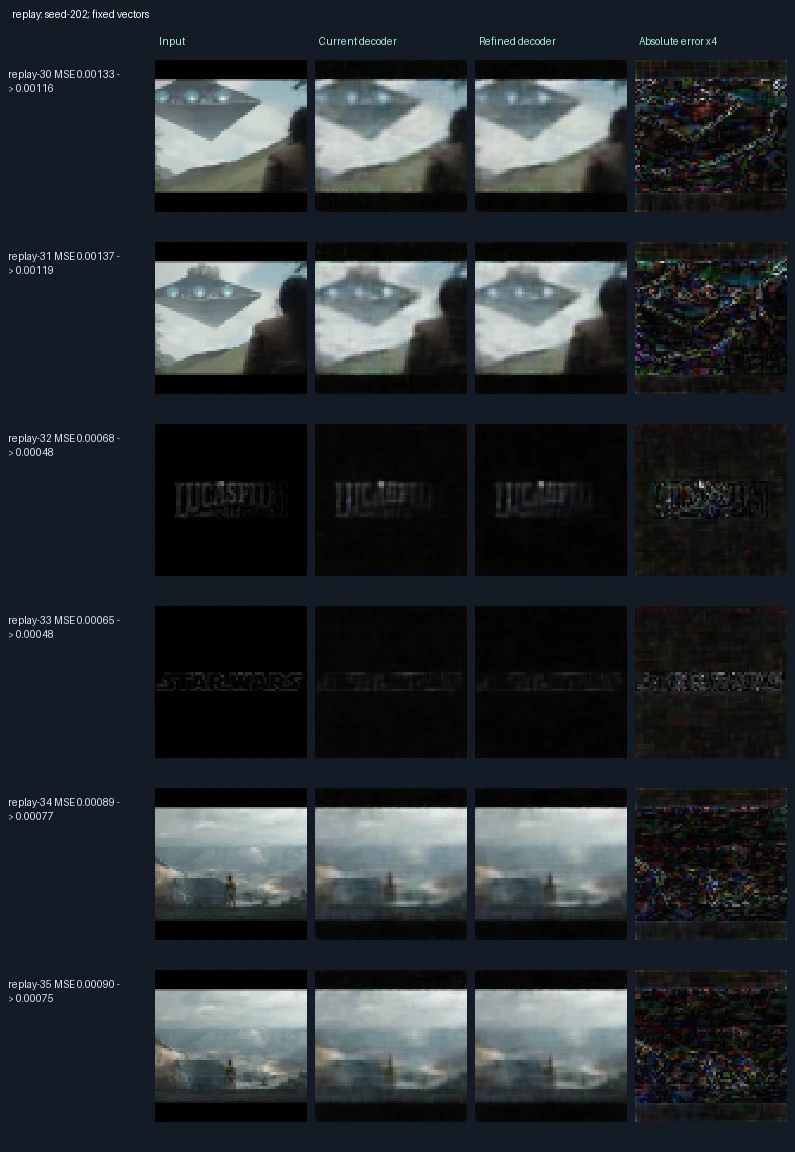
Earlier images are encoded again and immediately decoded. This tests reconstruction of familiar content; it does not show that untouched old memories remain compatible. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: encoding earlier Andor video frames again 36–41
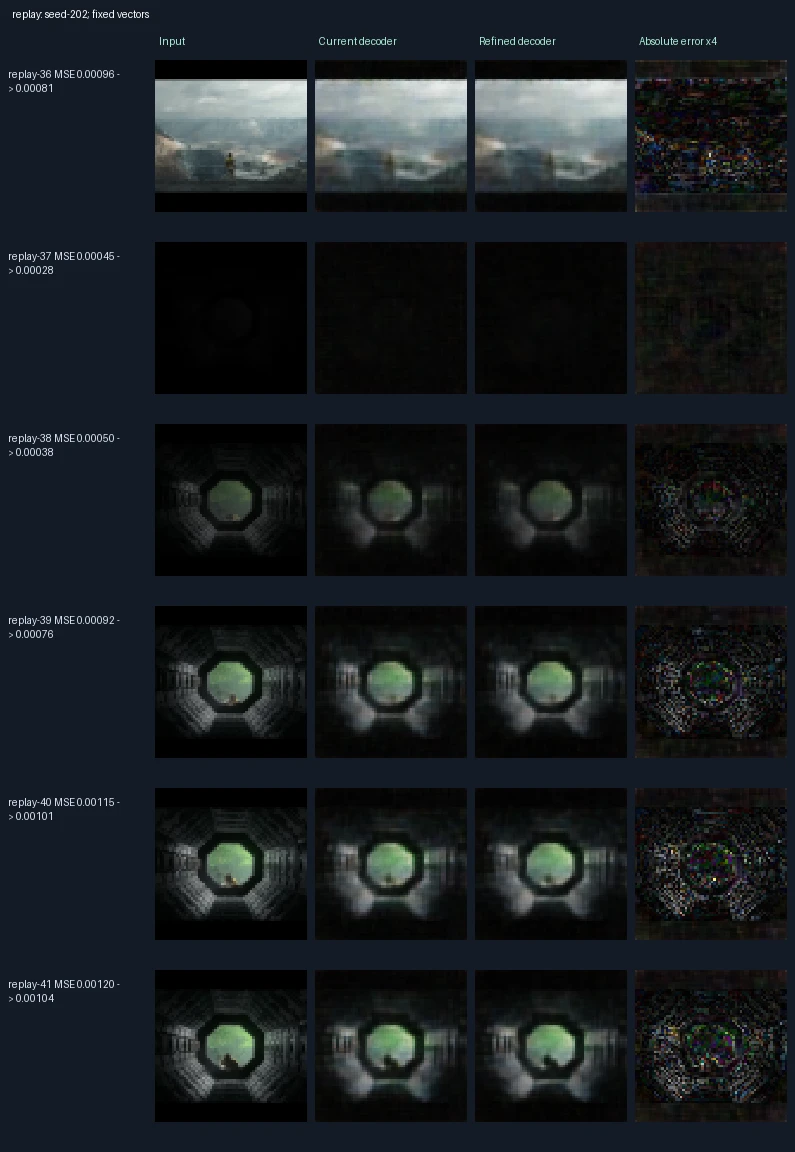
Earlier images are encoded again and immediately decoded. This tests reconstruction of familiar content; it does not show that untouched old memories remain compatible. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: encoding earlier Andor video frames again 42–47
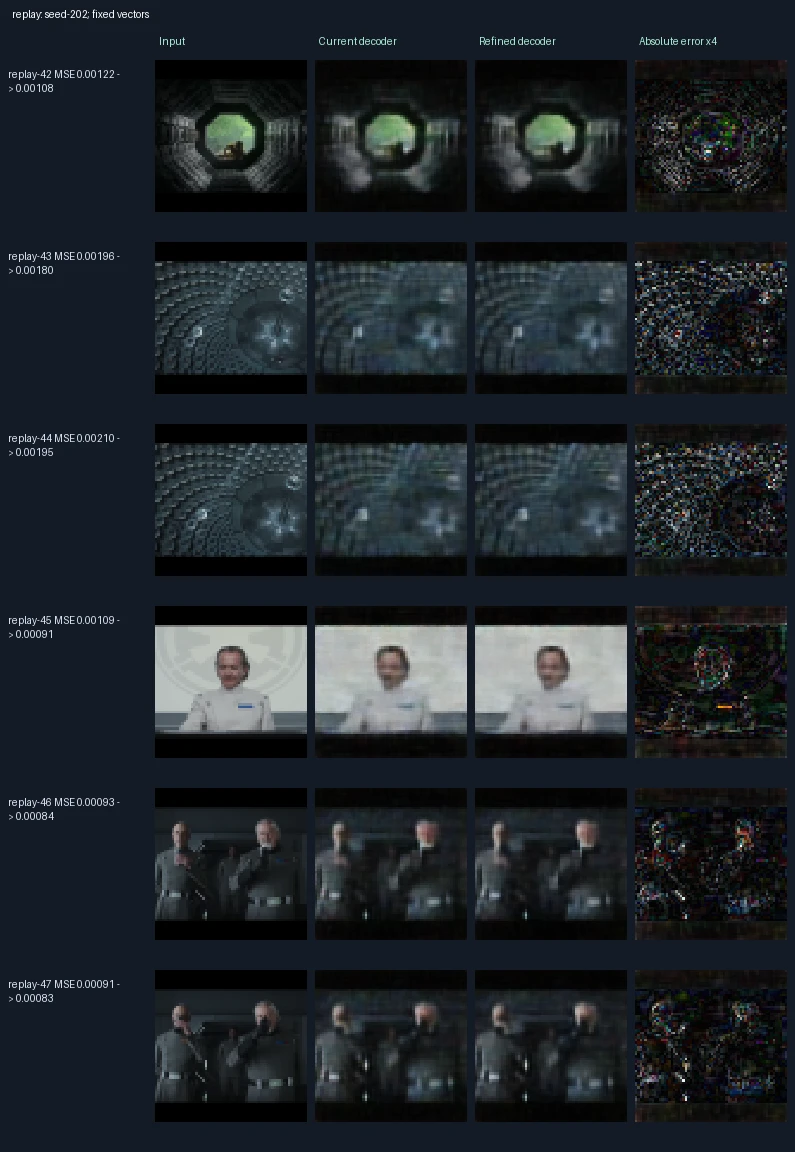
Earlier images are encoded again and immediately decoded. This tests reconstruction of familiar content; it does not show that untouched old memories remain compatible. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: encoding earlier Dune video frames again 48–53
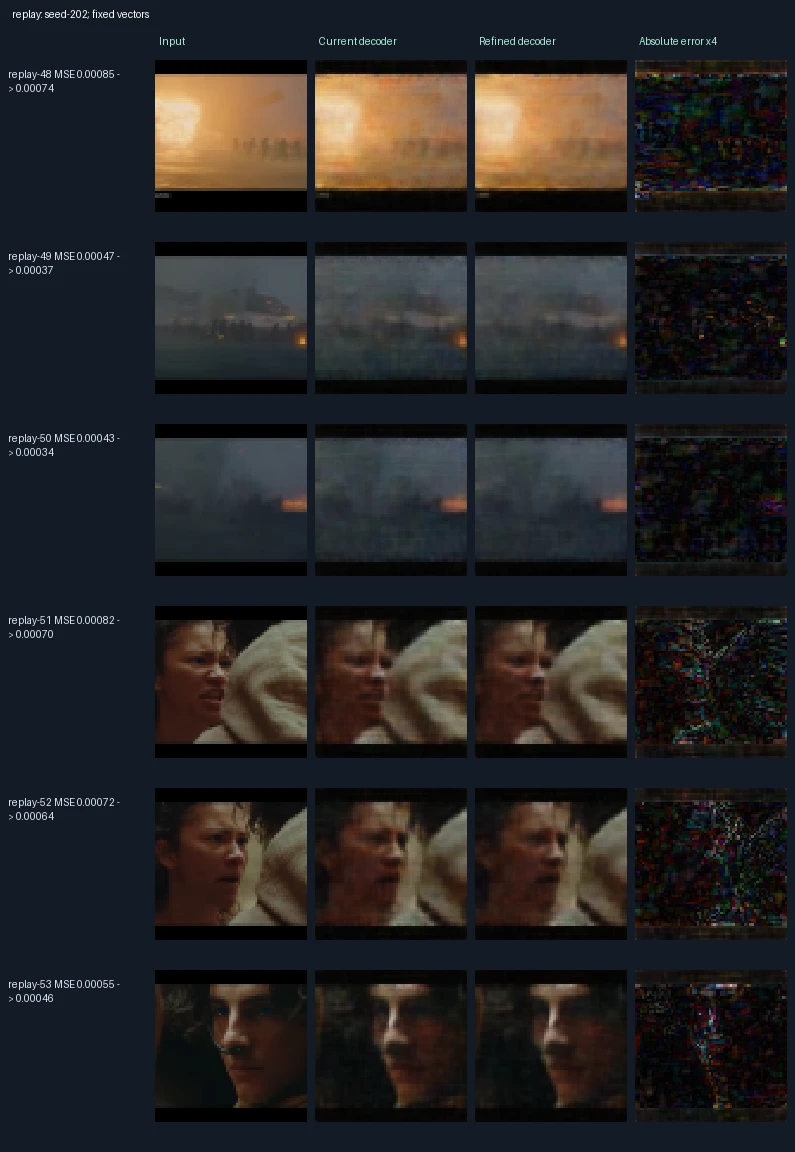
Earlier images are encoded again and immediately decoded. This tests reconstruction of familiar content; it does not show that untouched old memories remain compatible. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: encoding earlier Dune video frames again 54–59
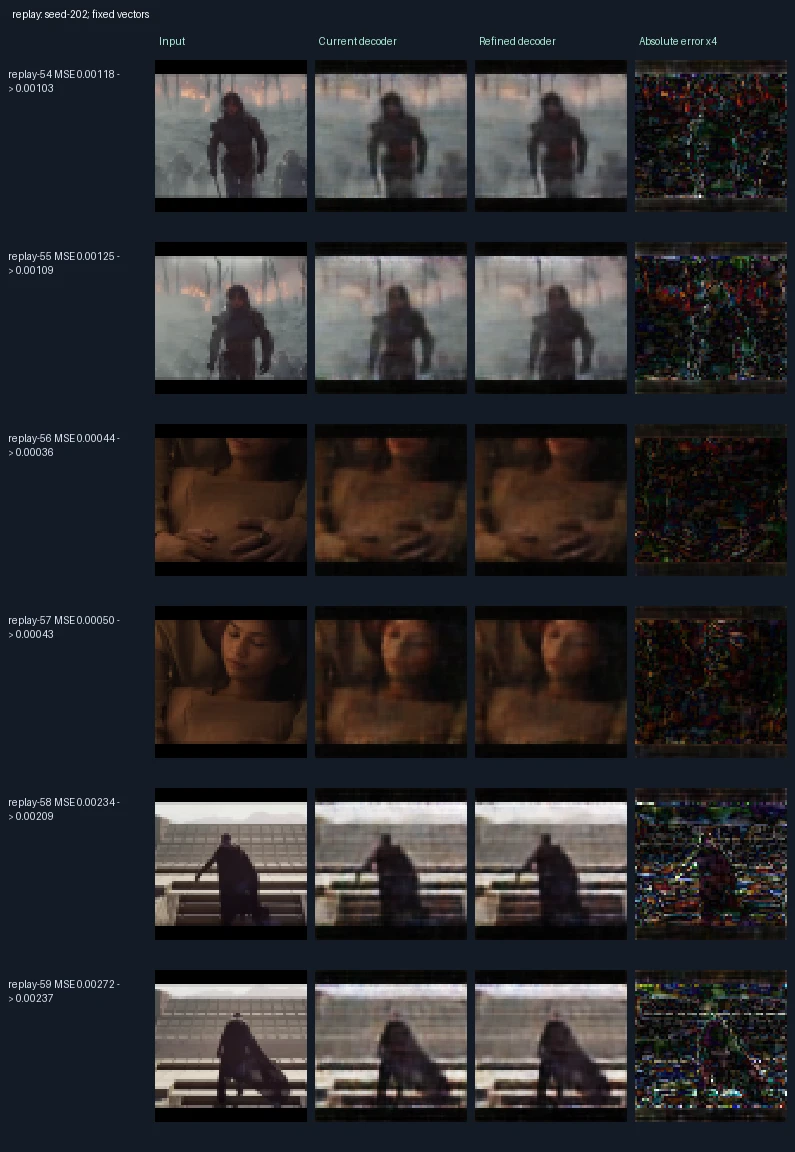
Earlier images are encoded again and immediately decoded. This tests reconstruction of familiar content; it does not show that untouched old memories remain compatible. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: encoding earlier Dune video frames again 60–65
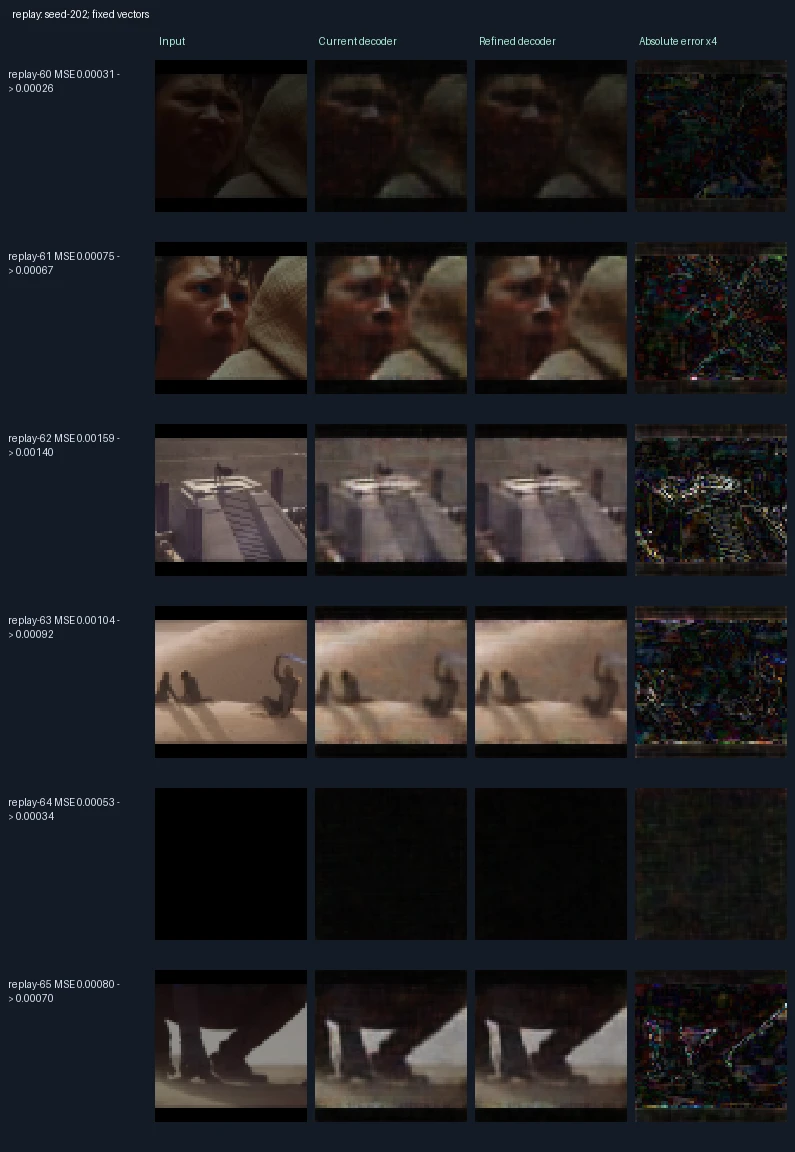
Earlier images are encoded again and immediately decoded. This tests reconstruction of familiar content; it does not show that untouched old memories remain compatible. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: encoding earlier Dune video frames again 66–71
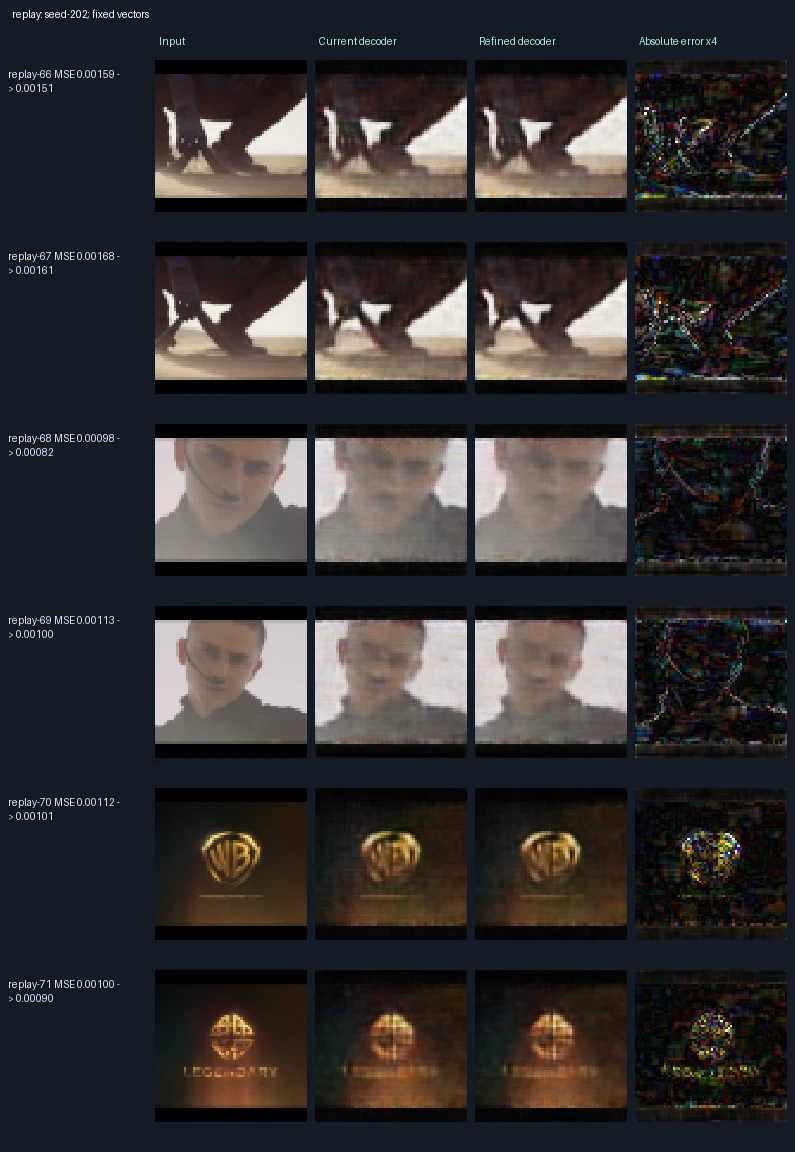
Earlier images are encoded again and immediately decoded. This tests reconstruction of familiar content; it does not show that untouched old memories remain compatible. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Rendered writing on white backgrounds: effect of decoder refinement
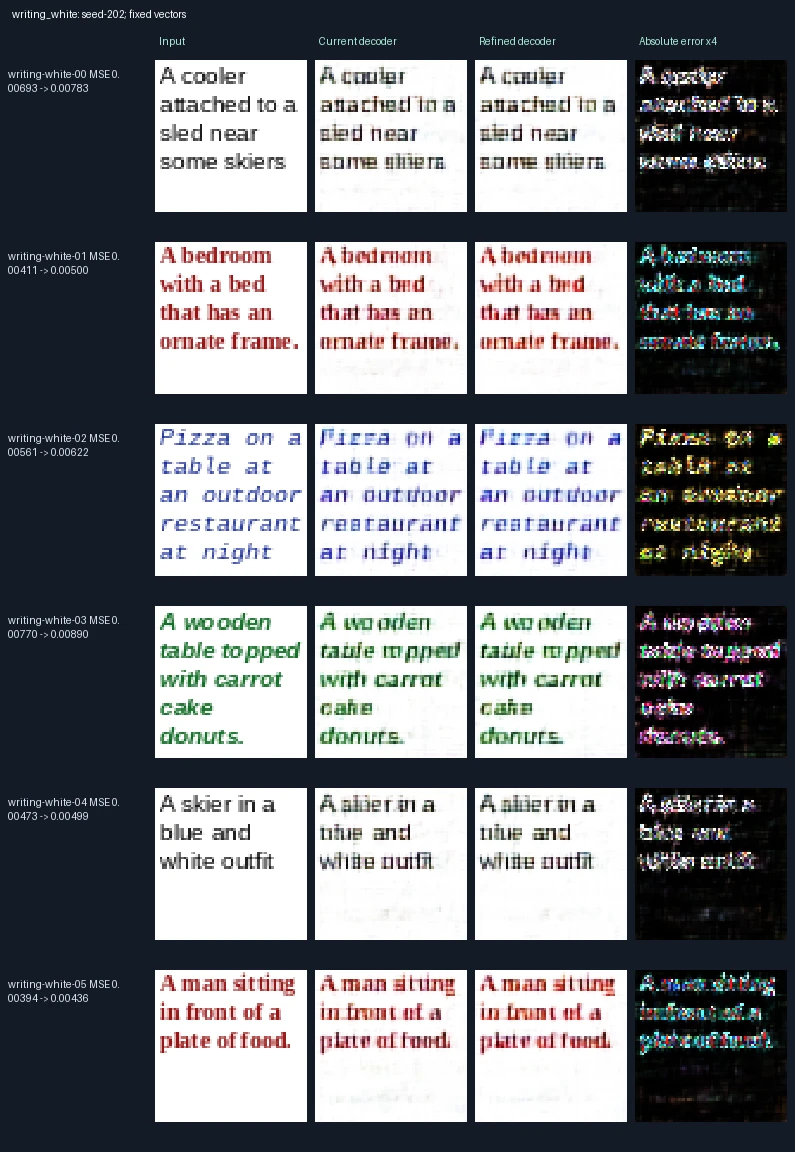
The first six test examples in predetermined order, not selected for reconstruction quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better. Writing is supplied as pixels, so this tests visual detail rather than reading comprehension.
Rendered writing on photographs: effect of decoder refinement
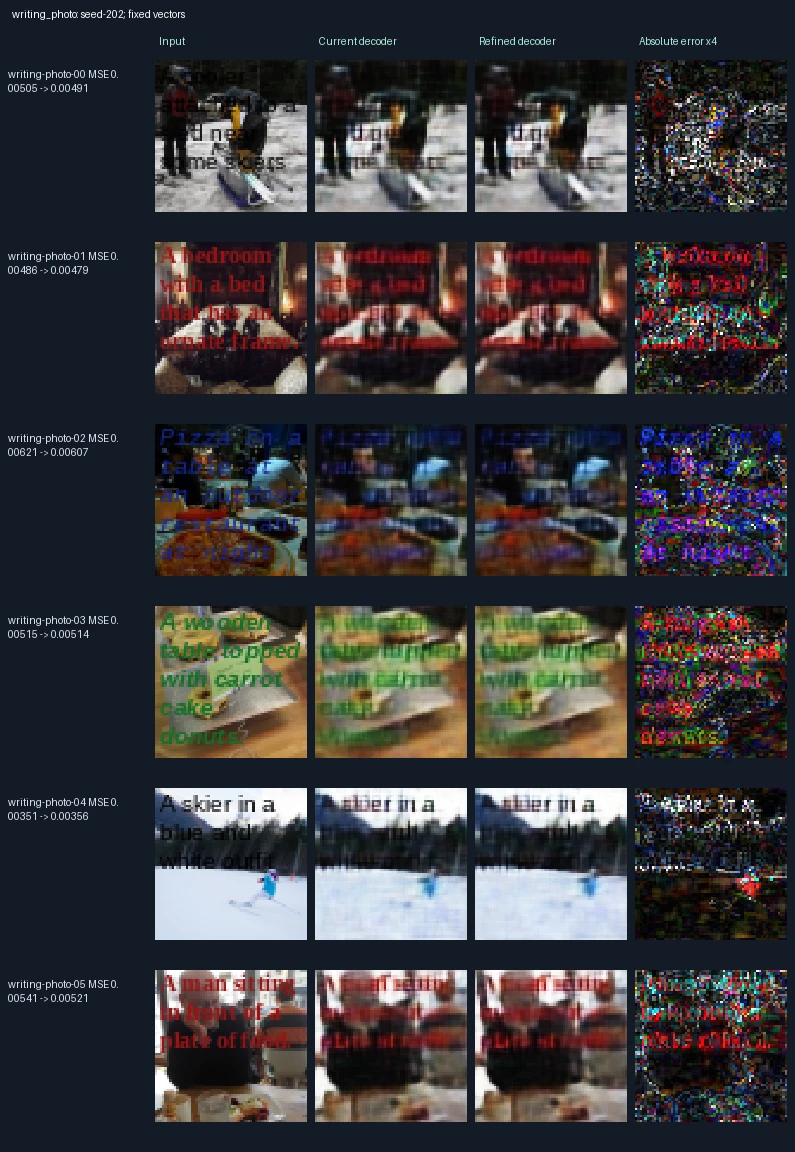
The first six test examples in predetermined order, not selected for reconstruction quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better. Writing is supplied as pixels, so this tests visual detail rather than reading comprehension.
Decoder refinement: reading stored photographs 0–5
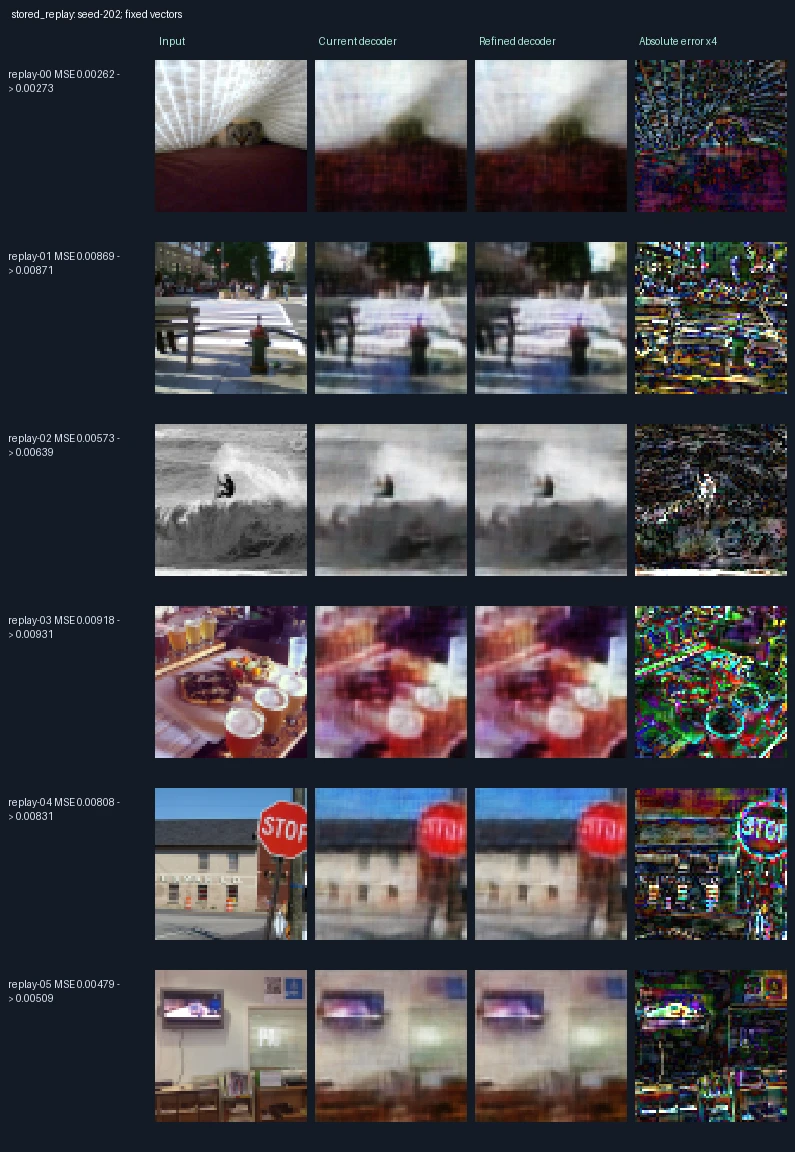
The actual old memory vectors are decoded without re-encoding their source images. This tests whether a changed decoder can still read earlier representations. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: reading stored photographs 6–11
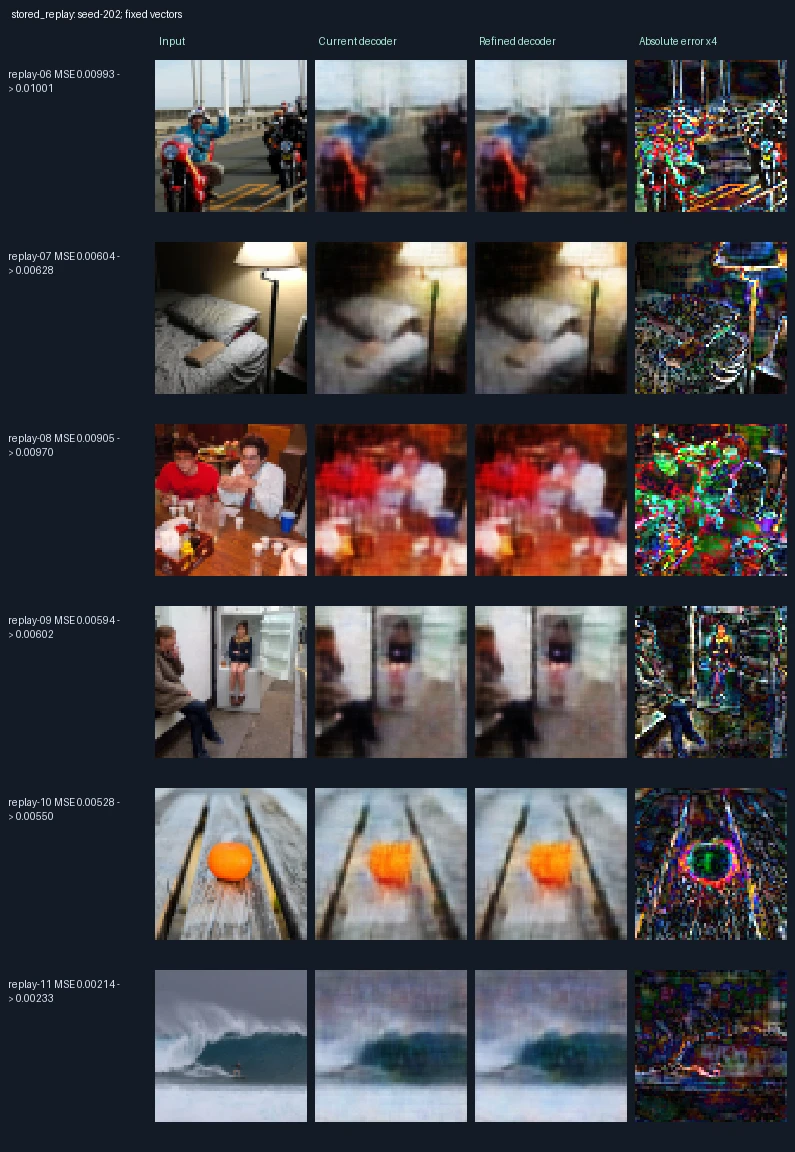
The actual old memory vectors are decoded without re-encoding their source images. This tests whether a changed decoder can still read earlier representations. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: reading stored photographs 12–17
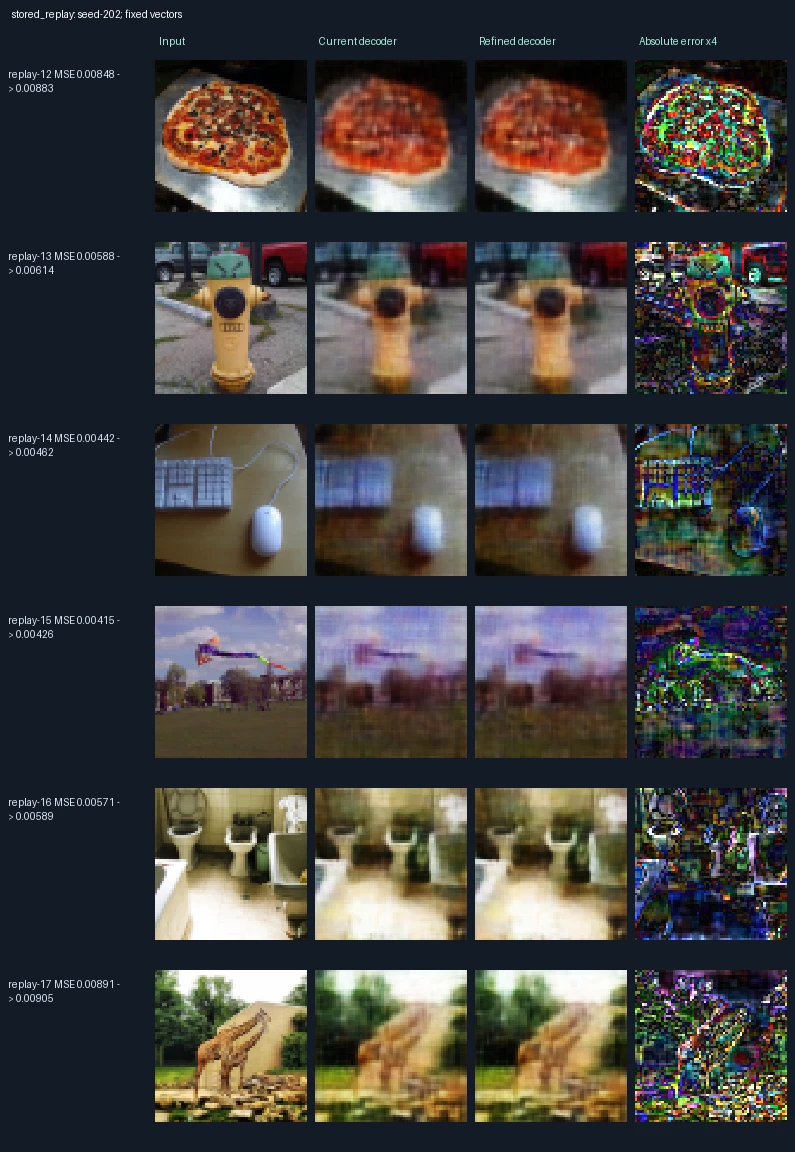
The actual old memory vectors are decoded without re-encoding their source images. This tests whether a changed decoder can still read earlier representations. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: reading stored photographs 18–23
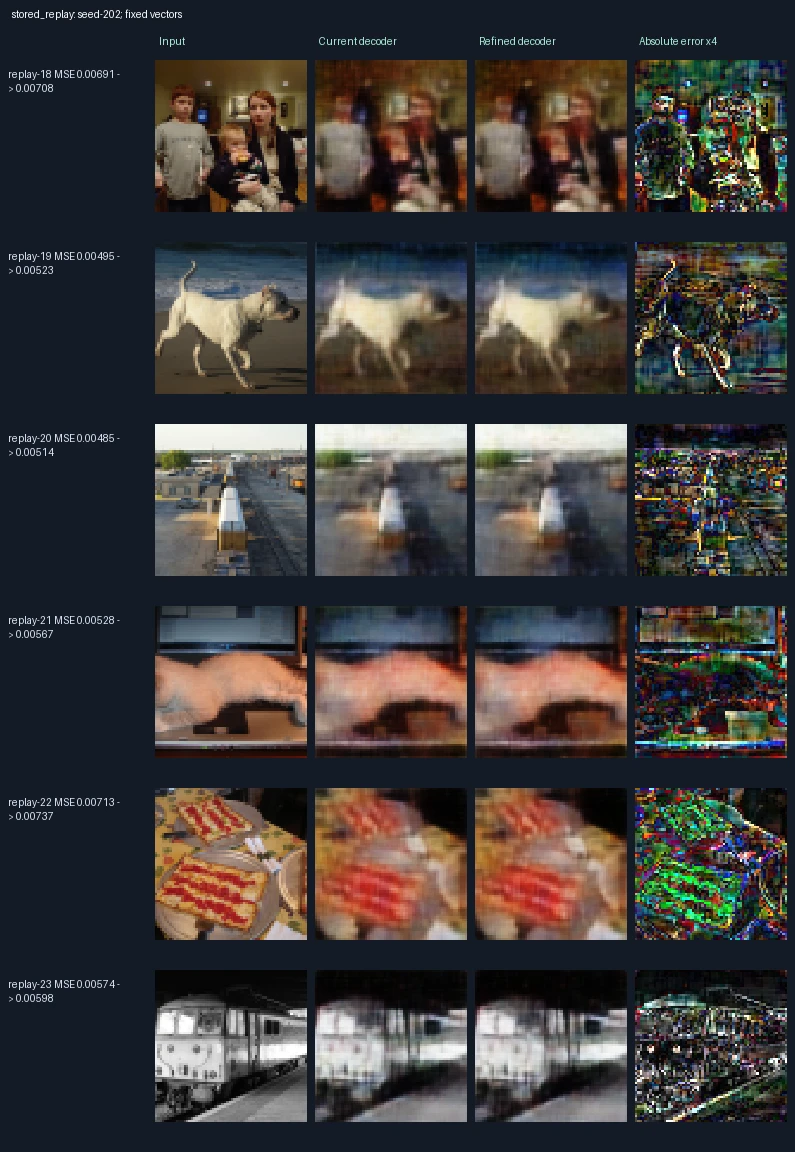
The actual old memory vectors are decoded without re-encoding their source images. This tests whether a changed decoder can still read earlier representations. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: reading stored Andor video frames 24–29
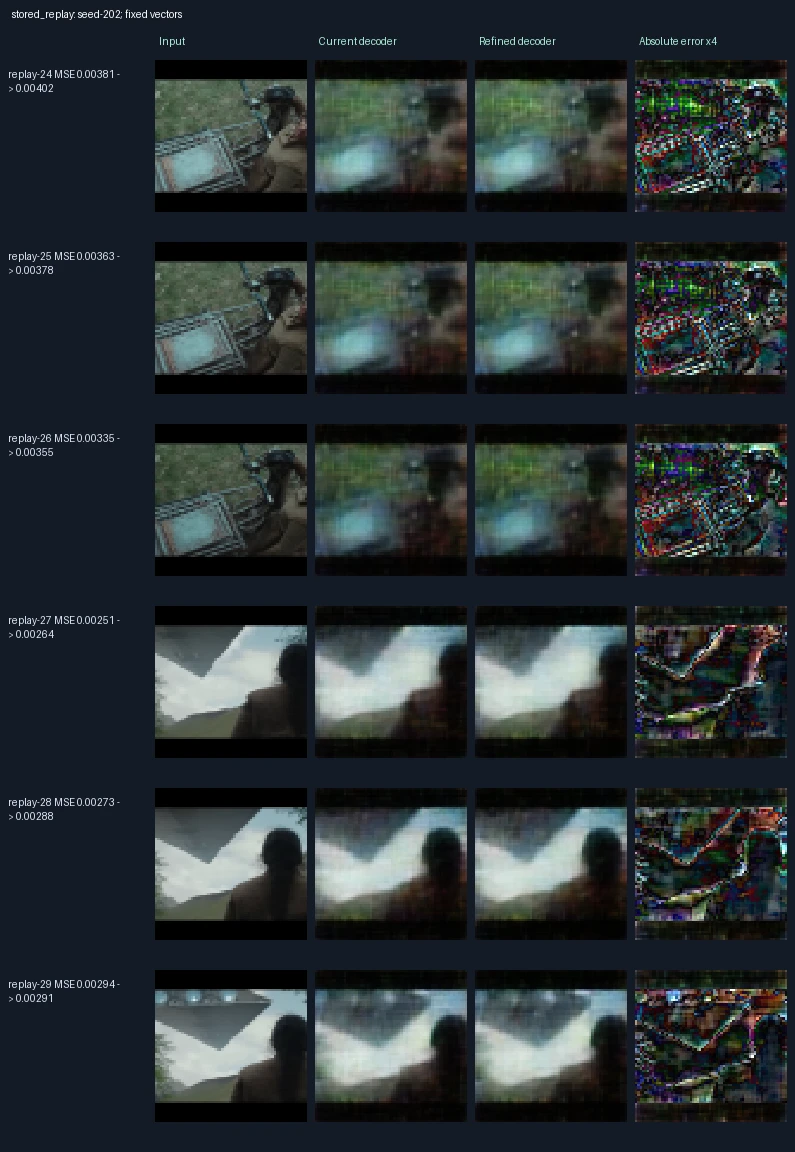
The actual old memory vectors are decoded without re-encoding their source images. This tests whether a changed decoder can still read earlier representations. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: reading stored Andor video frames 30–35
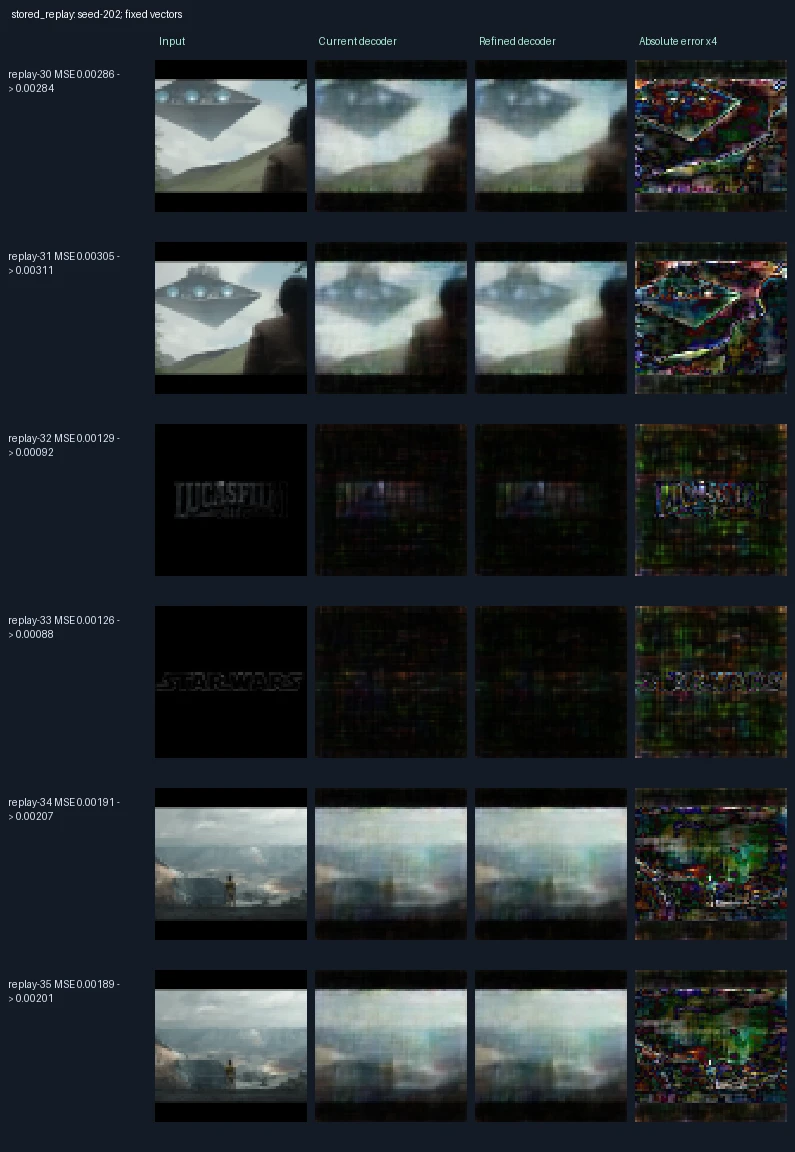
The actual old memory vectors are decoded without re-encoding their source images. This tests whether a changed decoder can still read earlier representations. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: reading stored Andor video frames 36–41
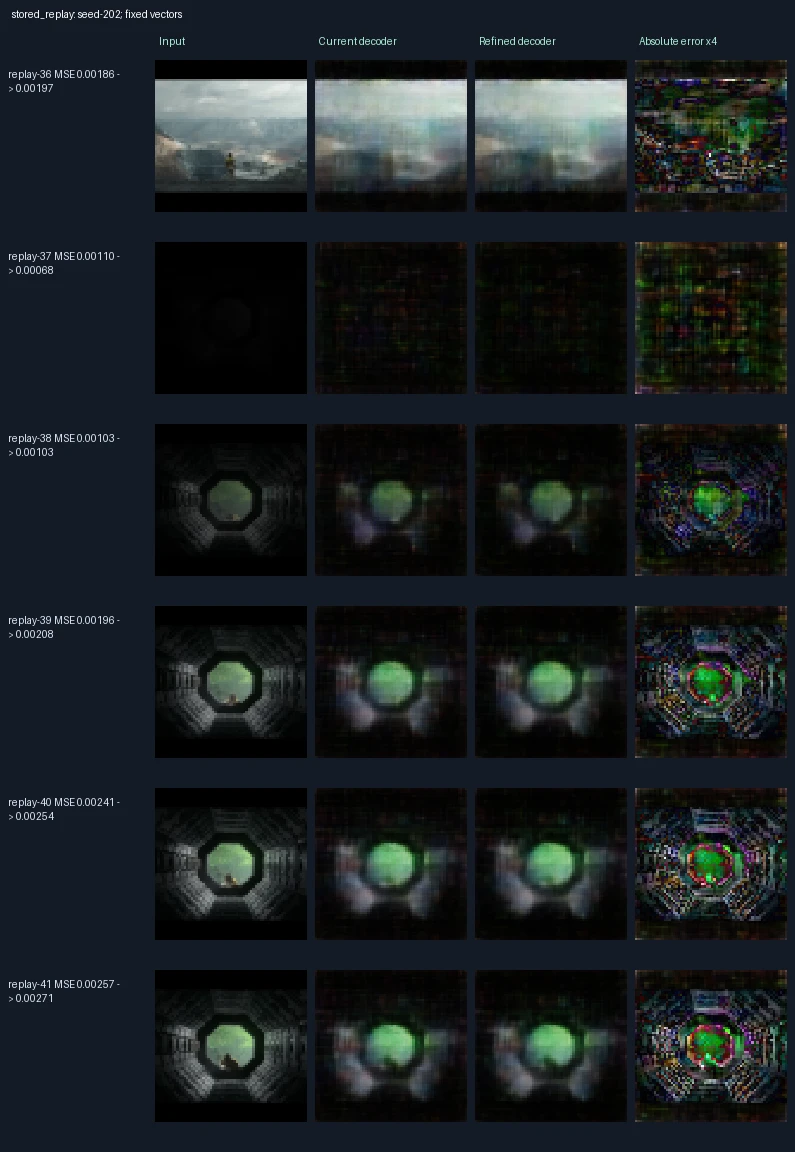
The actual old memory vectors are decoded without re-encoding their source images. This tests whether a changed decoder can still read earlier representations. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: reading stored Andor video frames 42–47
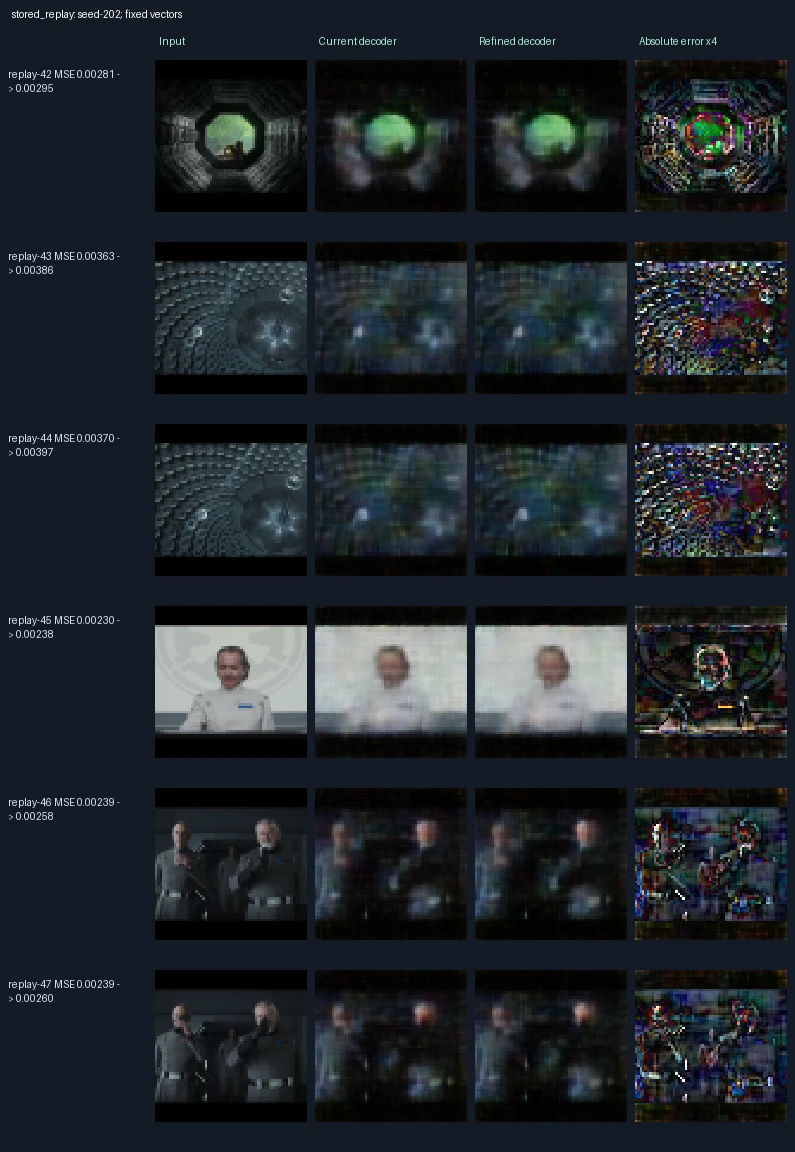
The actual old memory vectors are decoded without re-encoding their source images. This tests whether a changed decoder can still read earlier representations. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: reading stored Dune video frames 48–53
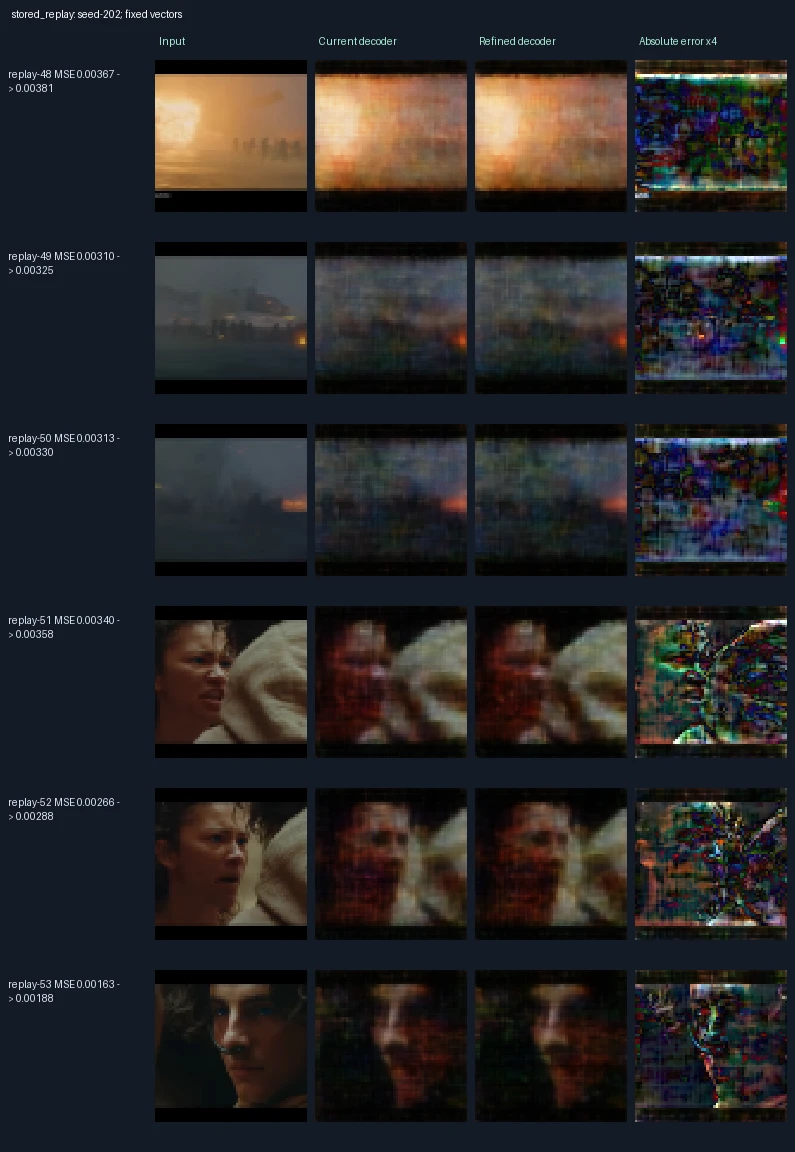
The actual old memory vectors are decoded without re-encoding their source images. This tests whether a changed decoder can still read earlier representations. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: reading stored Dune video frames 54–59
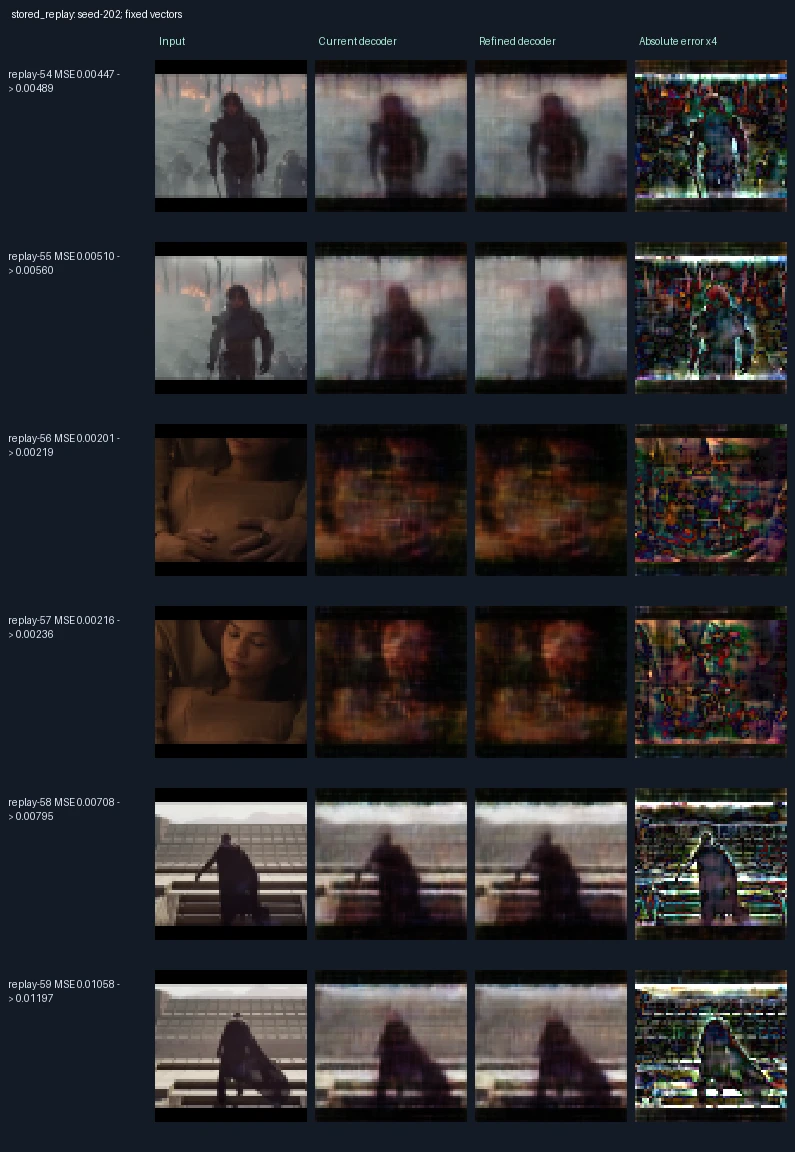
The actual old memory vectors are decoded without re-encoding their source images. This tests whether a changed decoder can still read earlier representations. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: reading stored Dune video frames 60–65
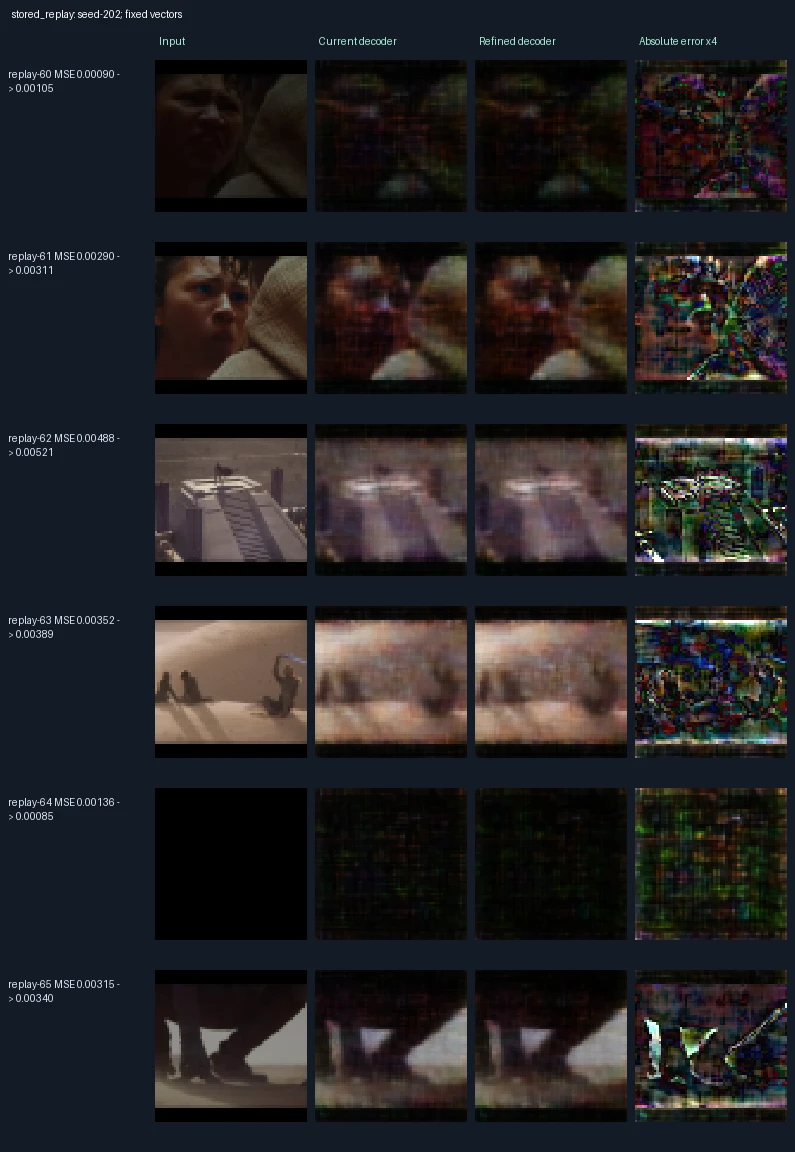
The actual old memory vectors are decoded without re-encoding their source images. This tests whether a changed decoder can still read earlier representations. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement: reading stored Dune video frames 66–71
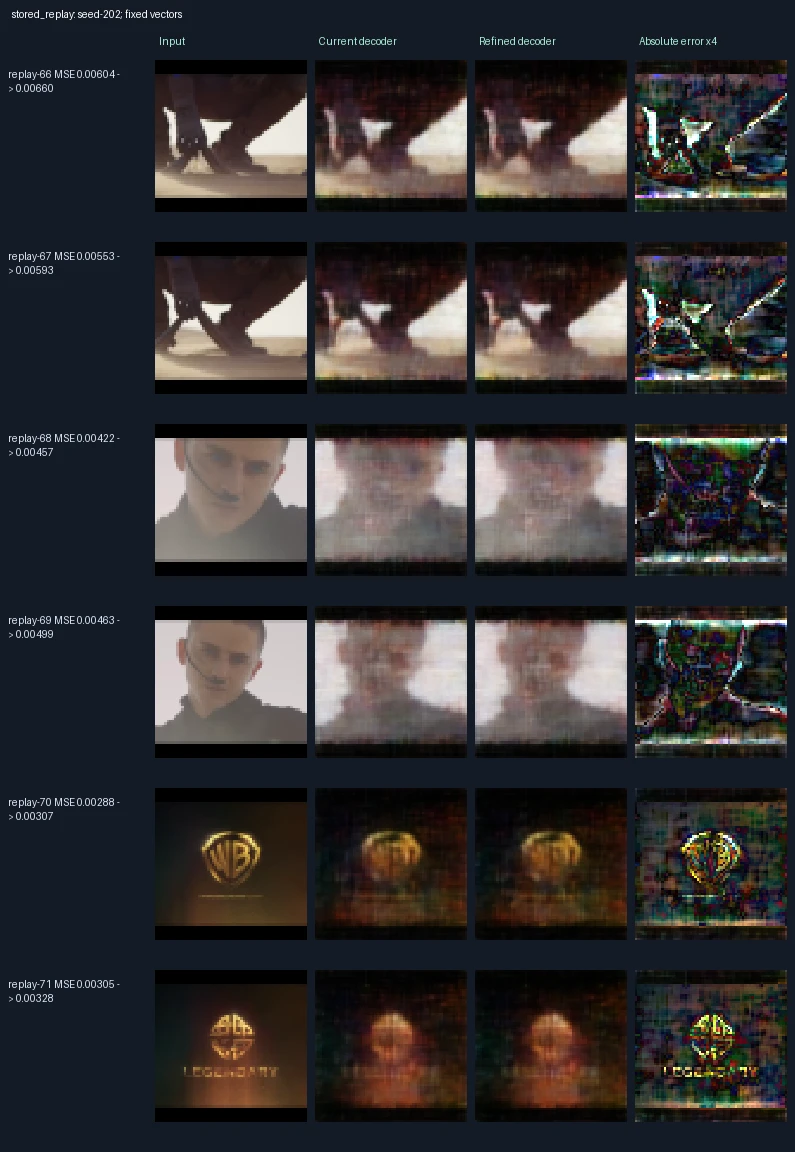
The actual old memory vectors are decoded without re-encoding their source images. This tests whether a changed decoder can still read earlier representations. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. MSE is mean squared RGB error on values scaled to 0–1; lower is better. Arrows in row labels compare the starting and refined models. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
How decoder training changes development-image error
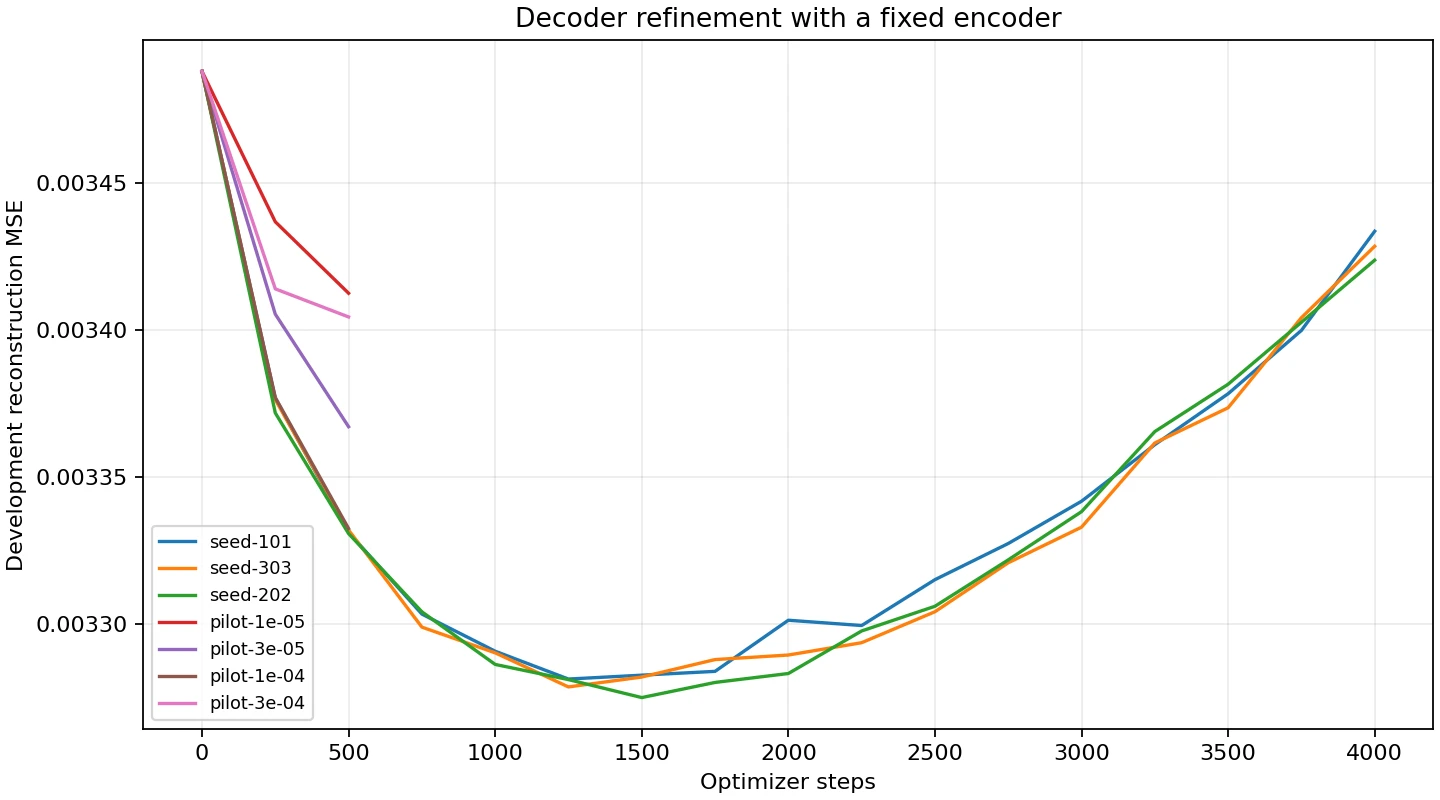
Horizontal axis: optimizer steps, each a weight update. Vertical axis: mean squared reconstruction error on development photographs; lower is better. Short lines are learning-rate trials, while the three long lines are repeated fits with different randomization settings. These development scores choose checkpoints before final testing; a later training step need not be a better model. Here the error falls and then rises again, so the selected decoder comes from an earlier checkpoint.
Decoder refinement: inputs used to monitor training
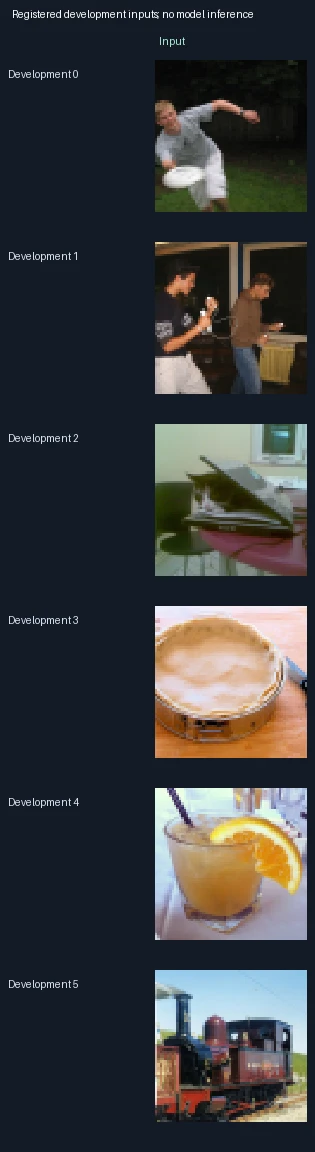
Six development photographs chosen before training, showing only the exact 64 × 64 input pixels. No reconstructions appear in this figure.
Decoder learning check: fitting eight training photographs
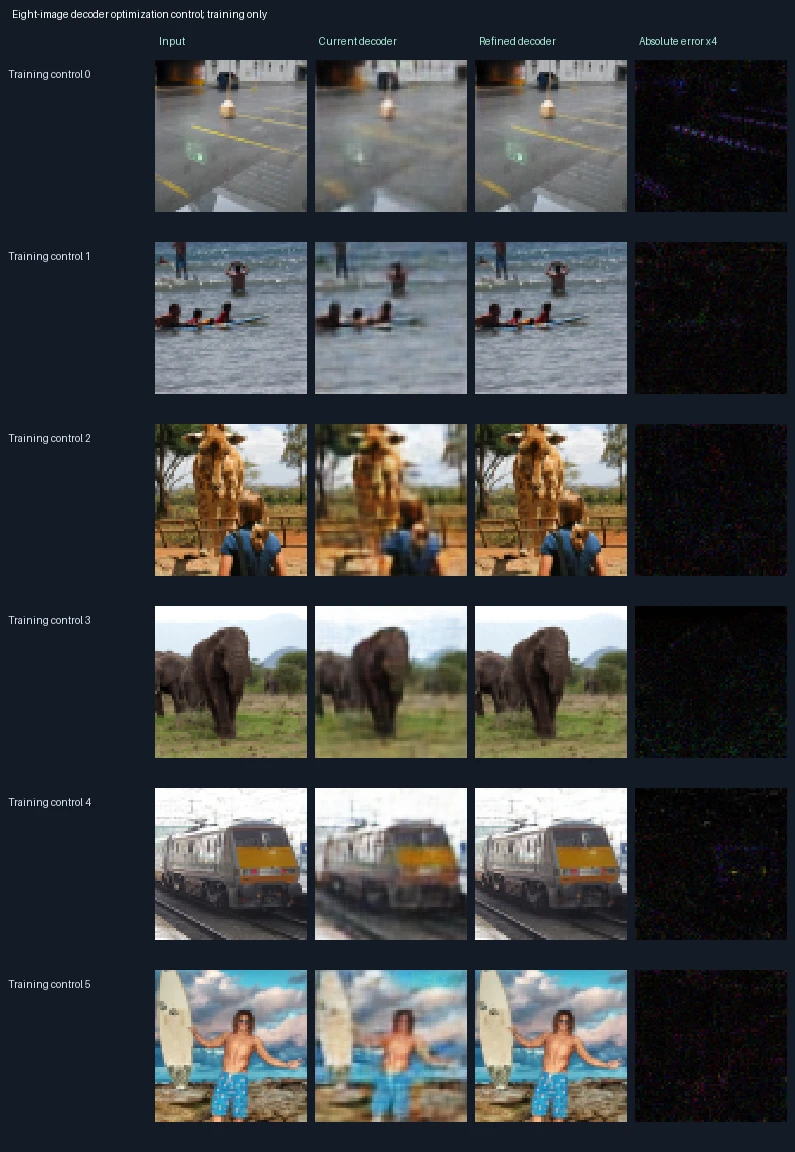
Six of the eight training photographs used in a deliberate fitting check. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. Only the decoder is trained. Better reproduction here verifies that weight updates can improve reconstruction, not that the model generalizes to new images. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, learning-rate trial (1e-05): 0 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This short trial uses learning rate 1e-05, a setting that controls the size of weight updates. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better. Zero updates records the starting model.
Decoder refinement, learning-rate trial (1e-05): 250 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This short trial uses learning rate 1e-05, a setting that controls the size of weight updates. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, learning-rate trial (1e-05): 500 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This short trial uses learning rate 1e-05, a setting that controls the size of weight updates. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, learning-rate trial (3e-05): 0 weight updates
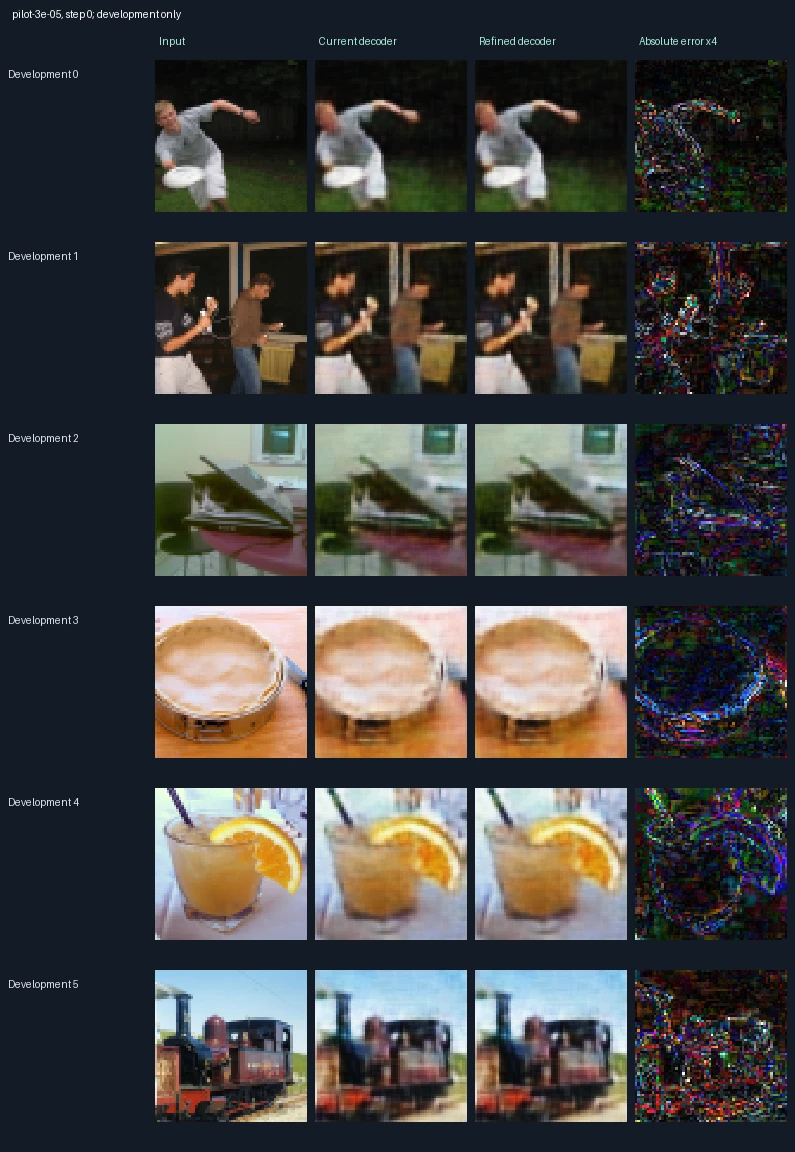
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This short trial uses learning rate 3e-05, a setting that controls the size of weight updates. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better. Zero updates records the starting model.
Decoder refinement, learning-rate trial (3e-05): 250 weight updates
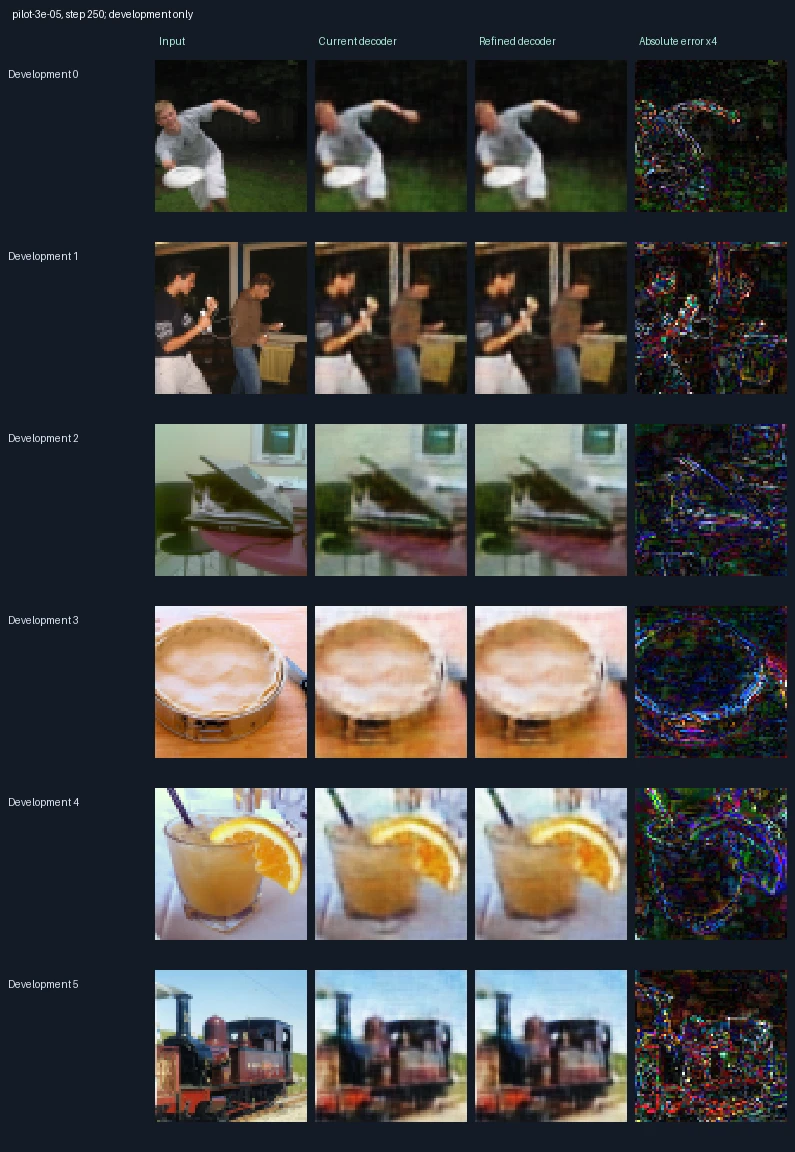
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This short trial uses learning rate 3e-05, a setting that controls the size of weight updates. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, learning-rate trial (3e-05): 500 weight updates
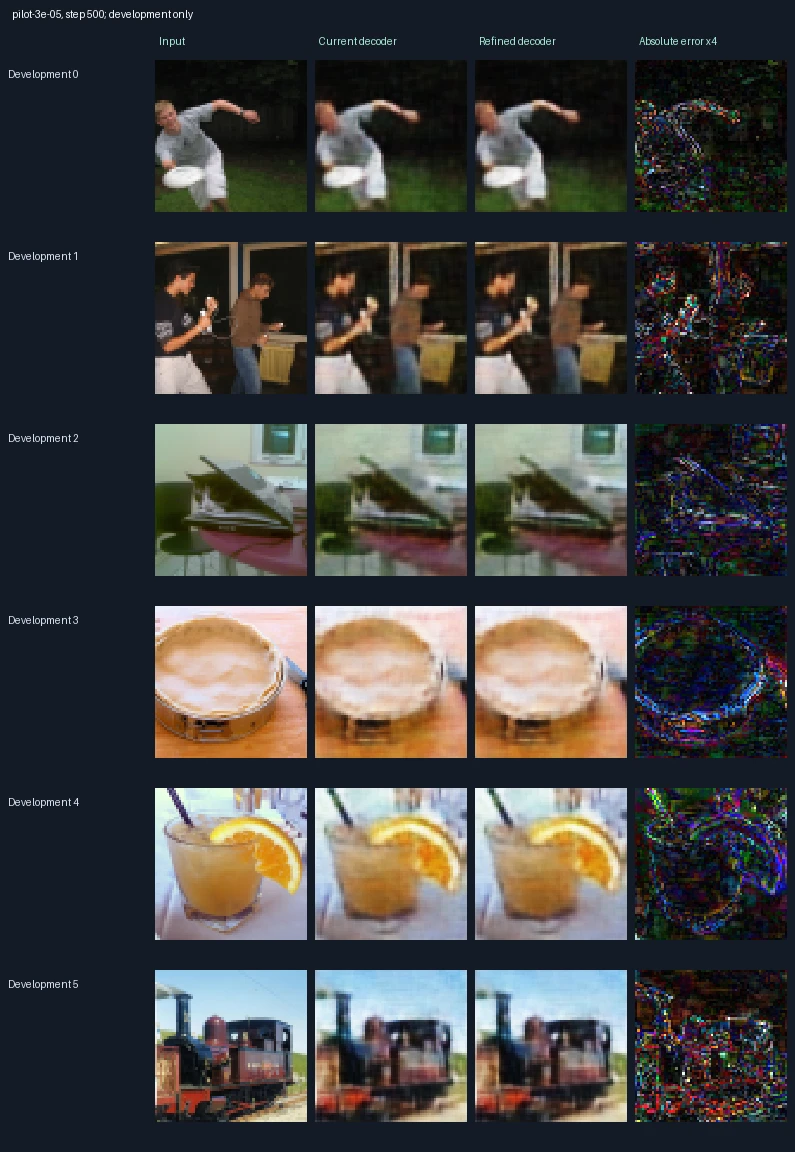
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This short trial uses learning rate 3e-05, a setting that controls the size of weight updates. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, learning-rate trial (1e-04): 0 weight updates
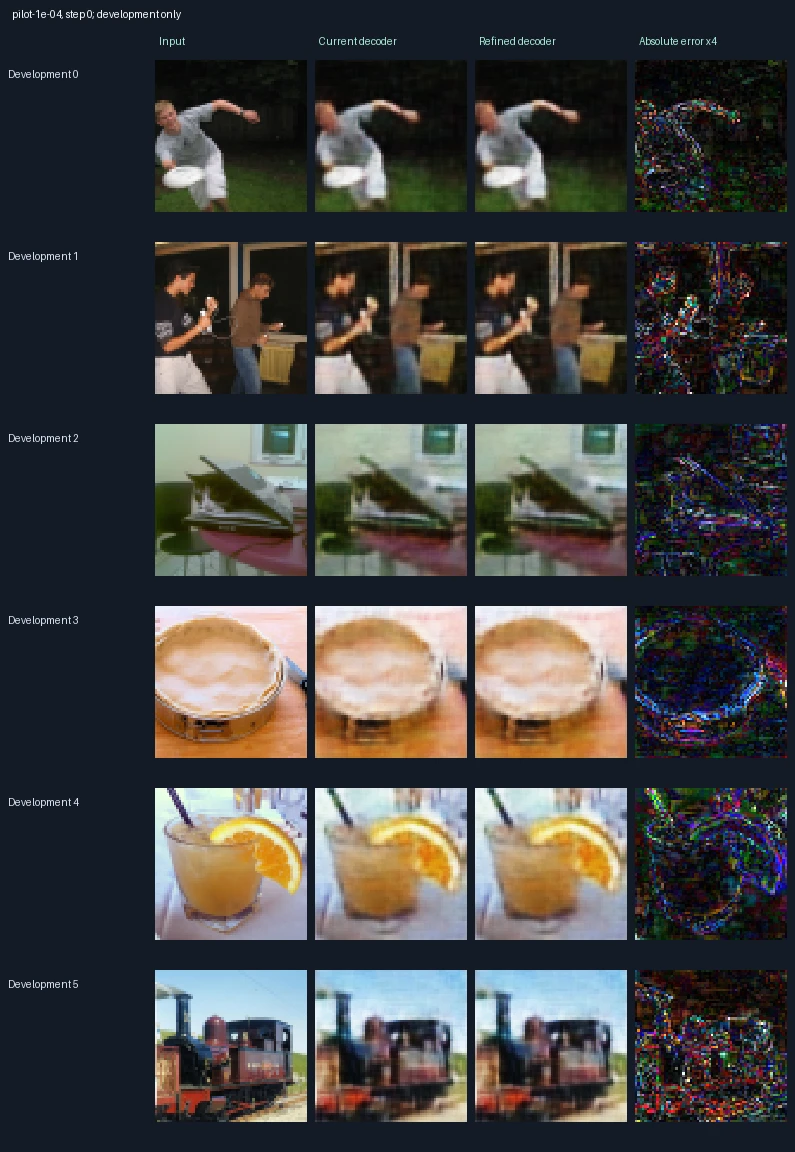
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This short trial uses learning rate 1e-04, a setting that controls the size of weight updates. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better. Zero updates records the starting model.
Decoder refinement, learning-rate trial (1e-04): 250 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This short trial uses learning rate 1e-04, a setting that controls the size of weight updates. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, learning-rate trial (1e-04): 500 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This short trial uses learning rate 1e-04, a setting that controls the size of weight updates. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, learning-rate trial (3e-04): 0 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This short trial uses learning rate 3e-04, a setting that controls the size of weight updates. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better. Zero updates records the starting model.
Decoder refinement, learning-rate trial (3e-04): 250 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This short trial uses learning rate 3e-04, a setting that controls the size of weight updates. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, learning-rate trial (3e-04): 500 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This short trial uses learning rate 3e-04, a setting that controls the size of weight updates. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 0 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better. Zero updates records the starting model.
Decoder refinement, training repetition 1: 250 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 500 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 750 weight updates
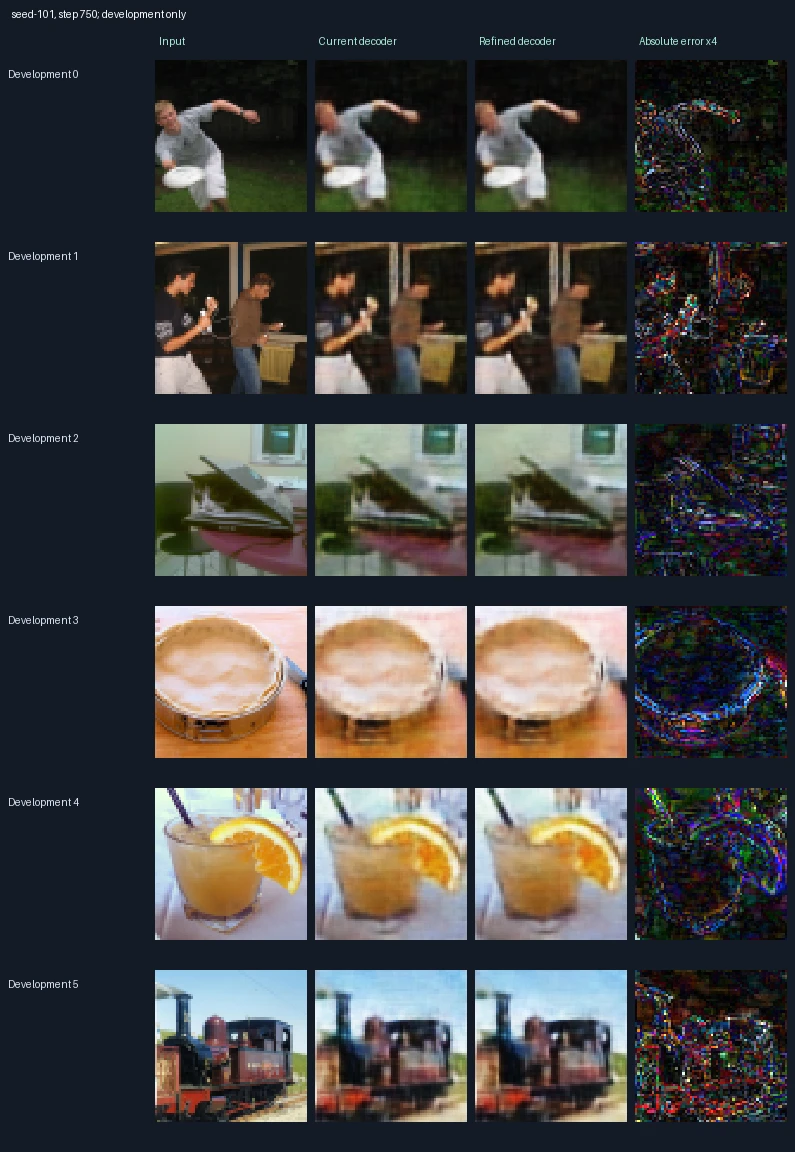
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 1,000 weight updates
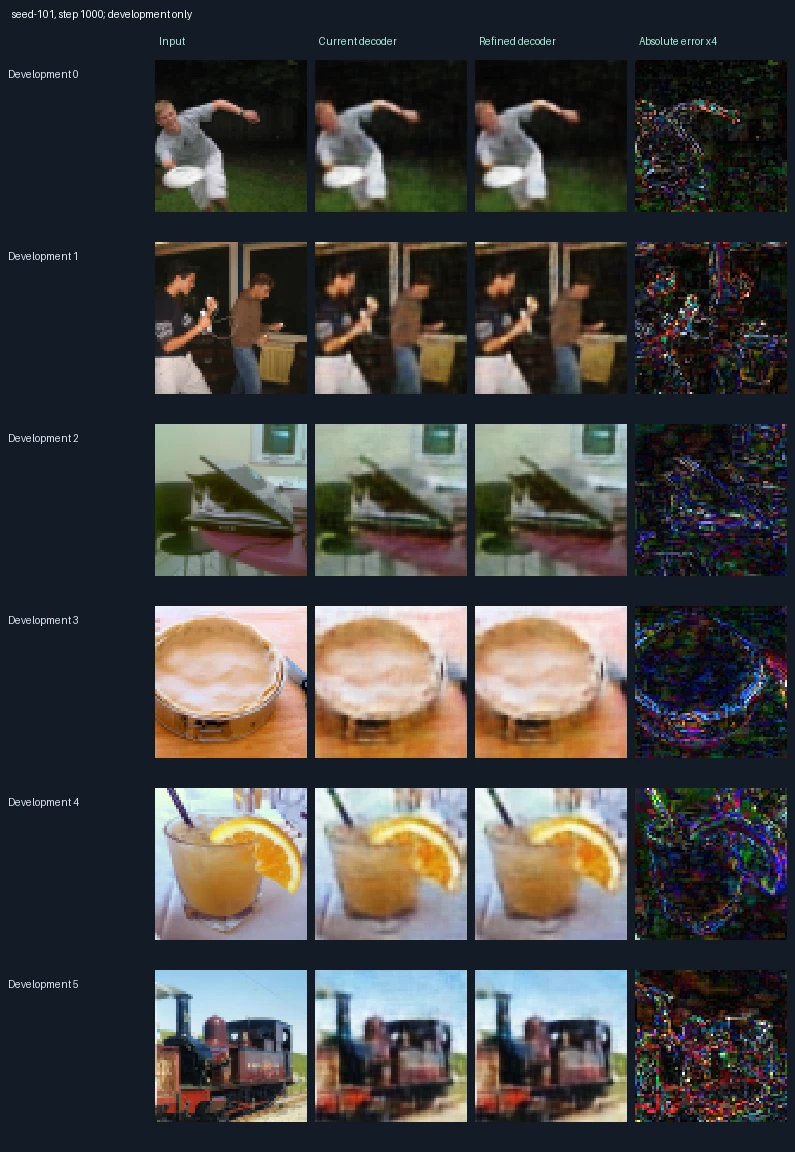
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 1,250 weight updates
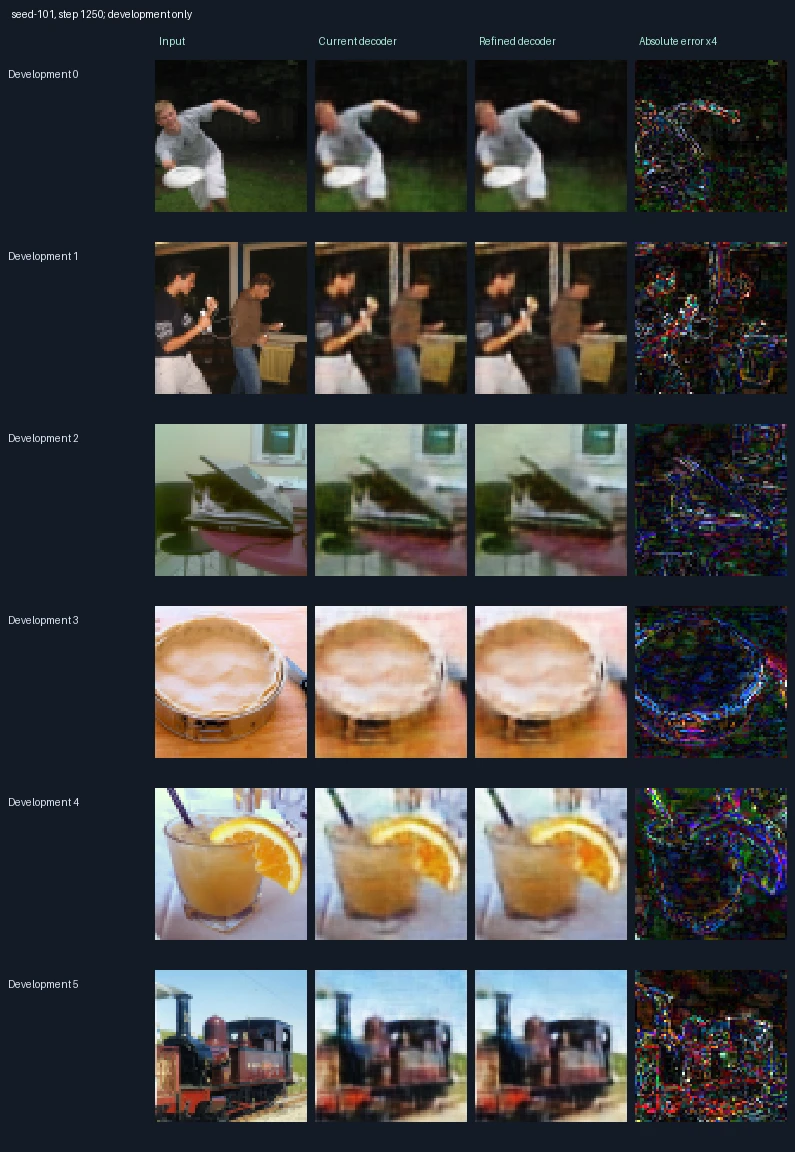
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 1,500 weight updates
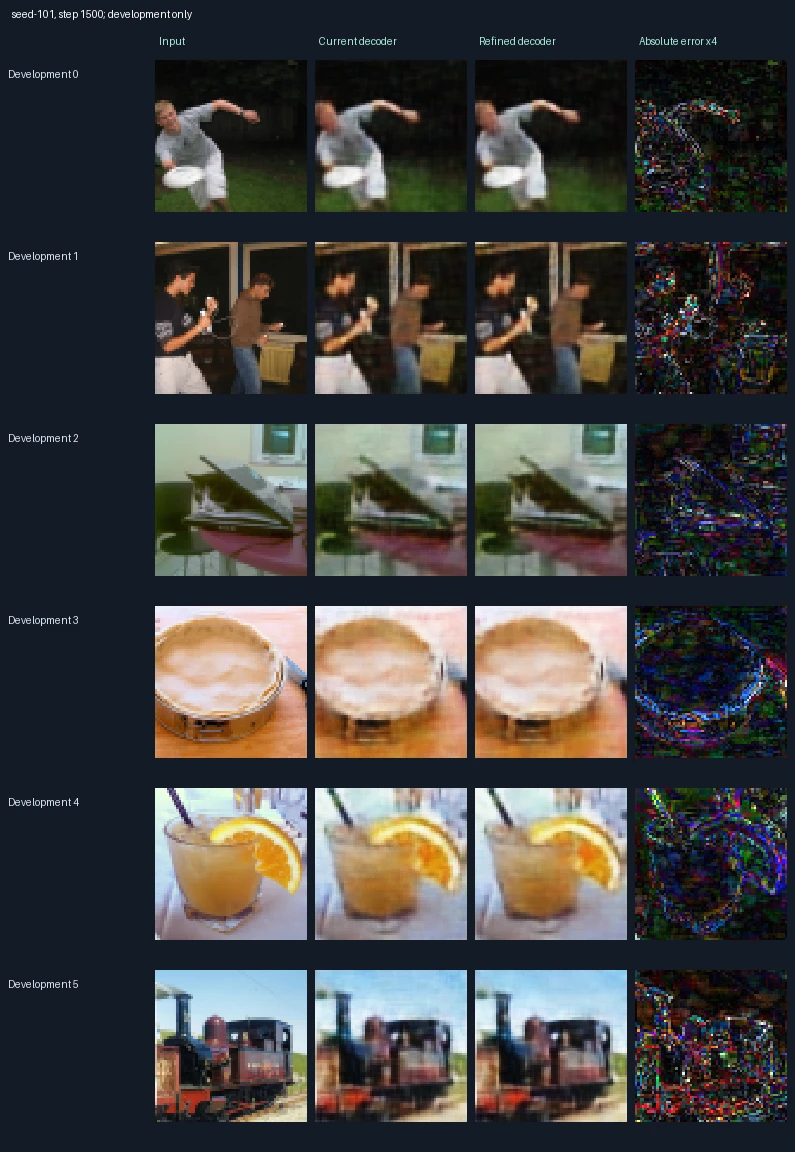
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 1,750 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 2,000 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 2,250 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 2,500 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 2,750 weight updates
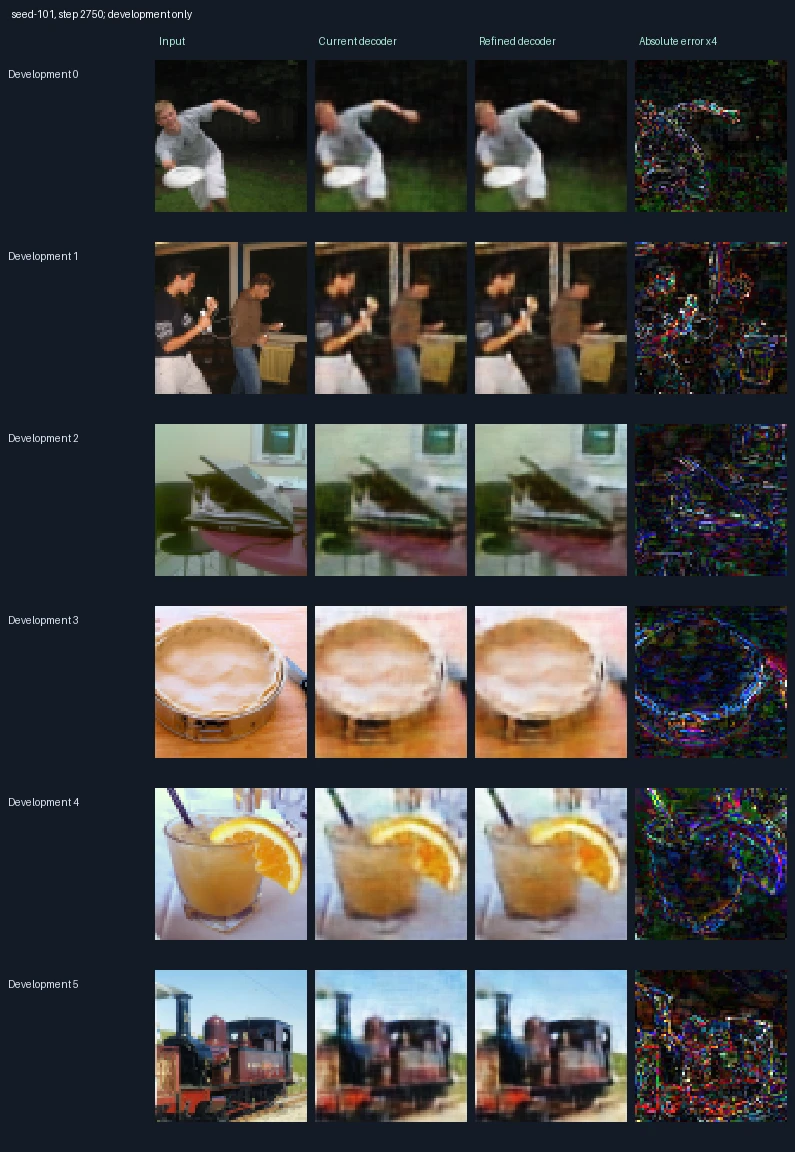
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 3,000 weight updates
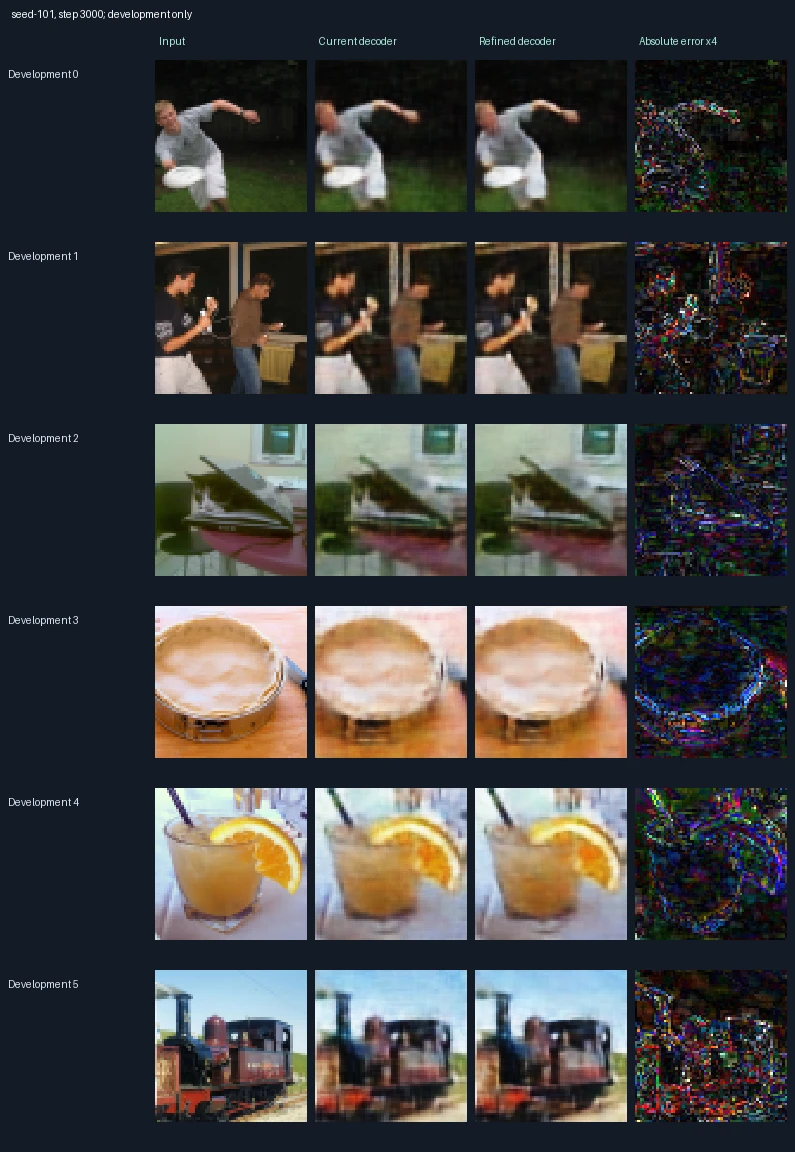
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 3,250 weight updates
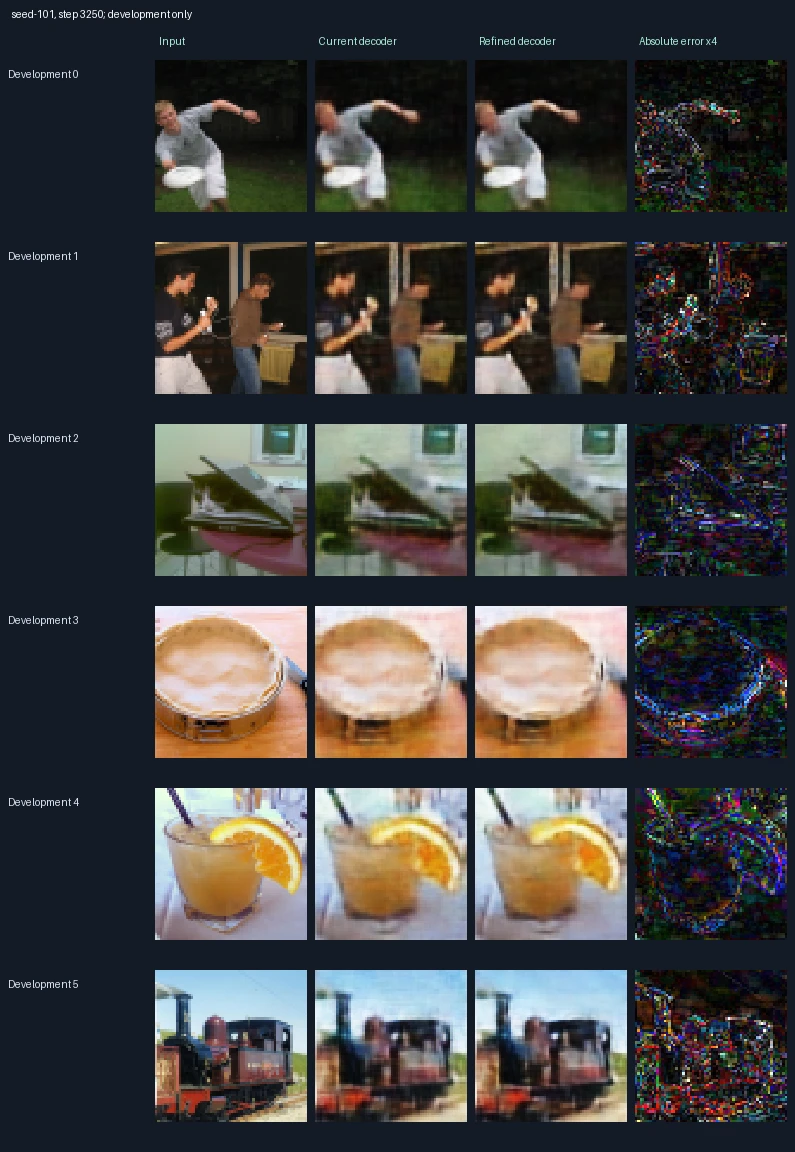
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 3,500 weight updates
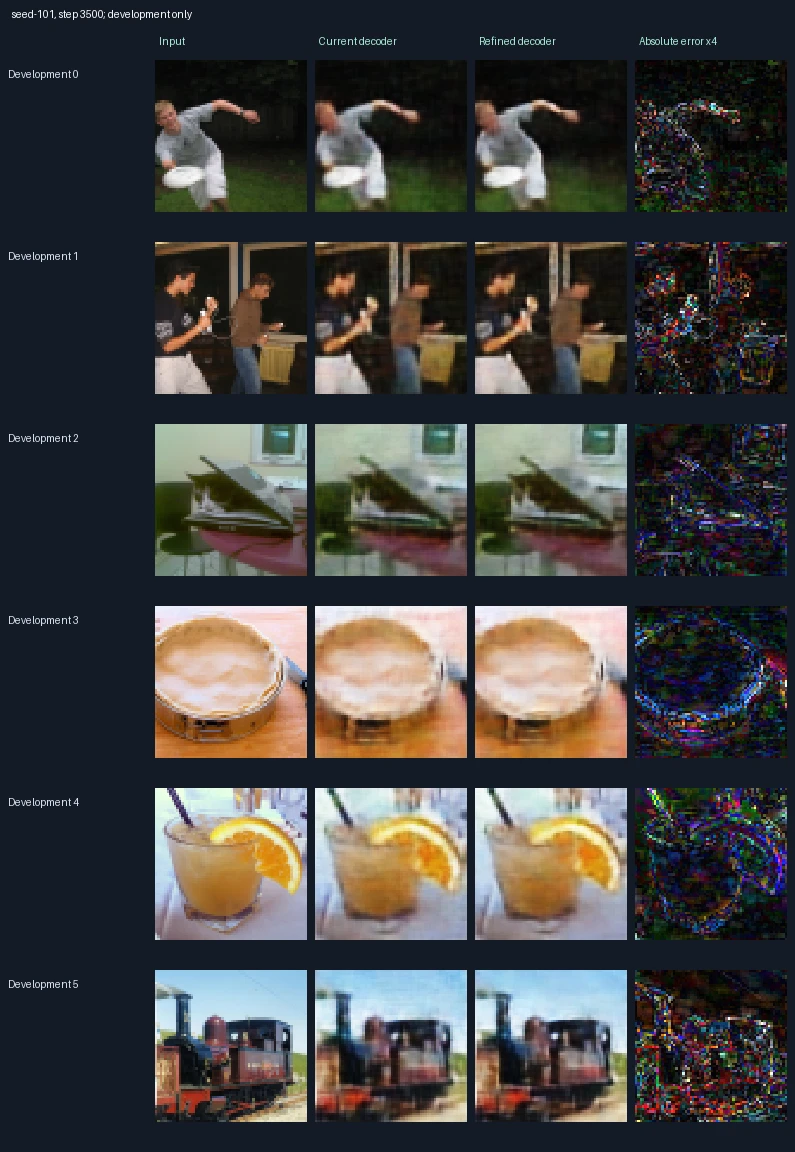
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 3,750 weight updates
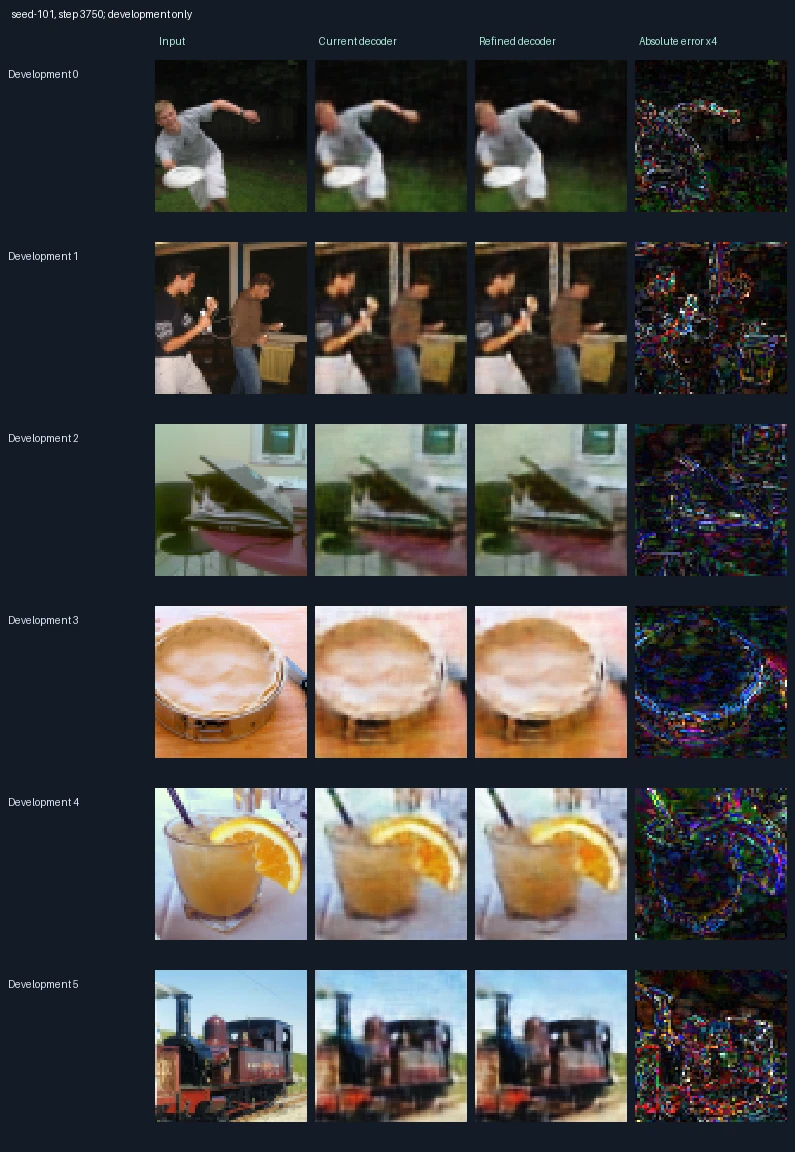
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 1: 4,000 weight updates
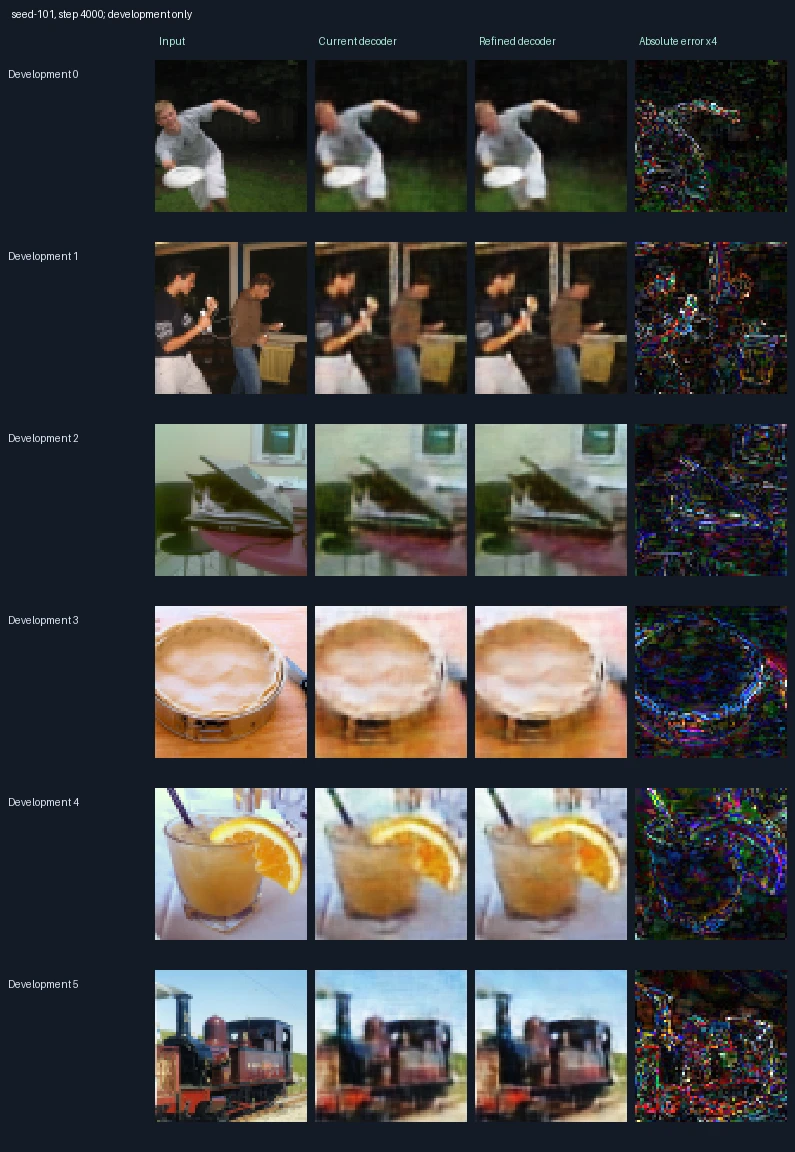
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 1; the image label “seed-101” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 0 weight updates
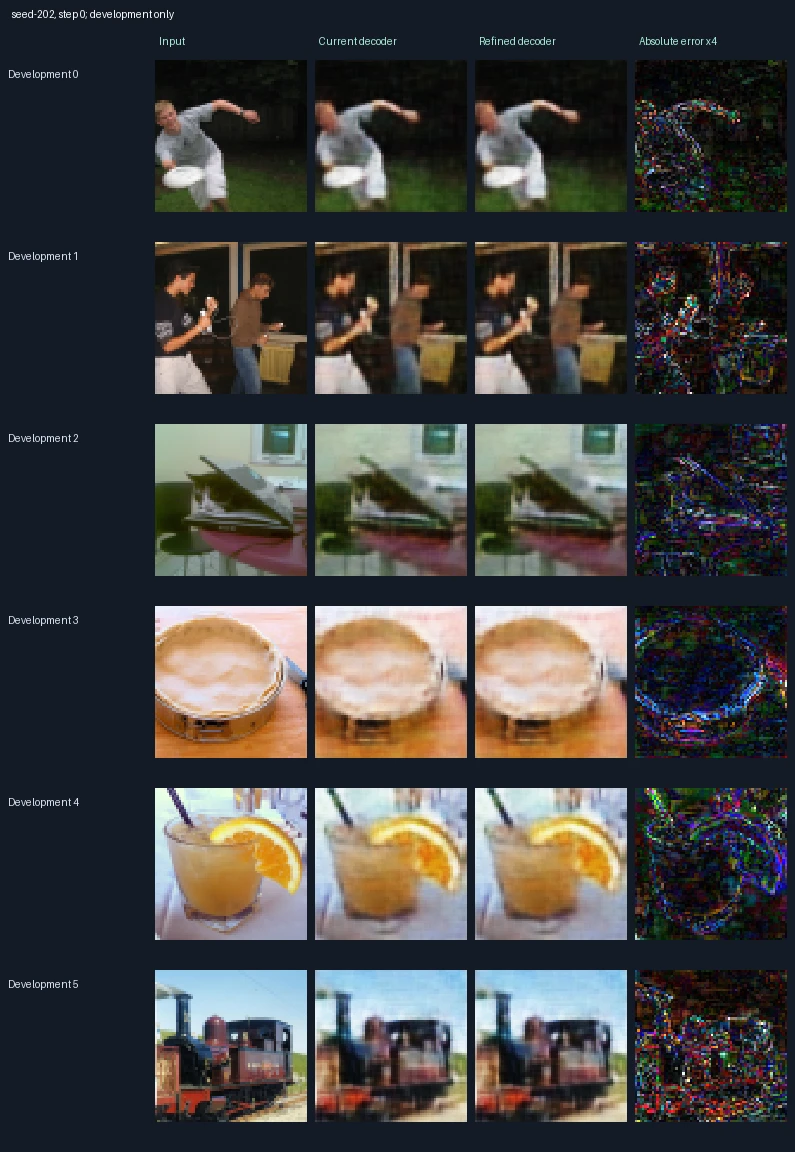
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better. Zero updates records the starting model.
Decoder refinement, training repetition 2: 250 weight updates
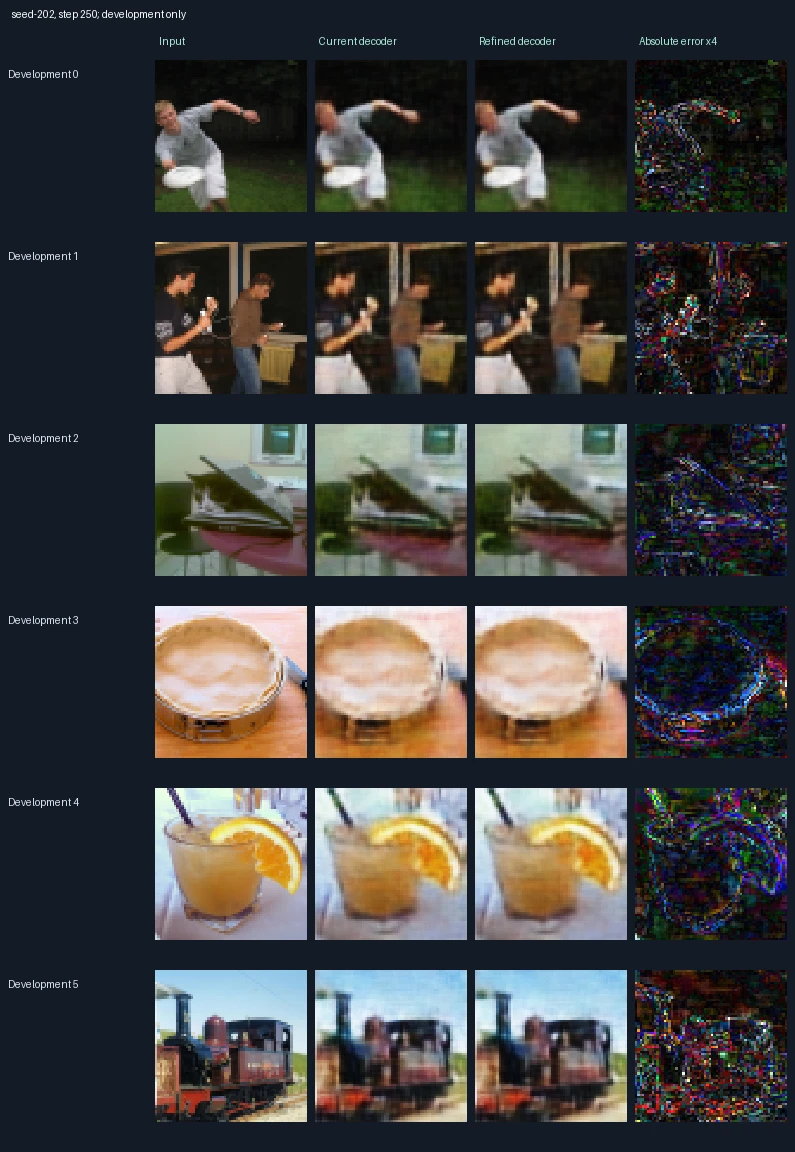
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 500 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 750 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 1,000 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 1,250 weight updates
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 1,500 weight updates
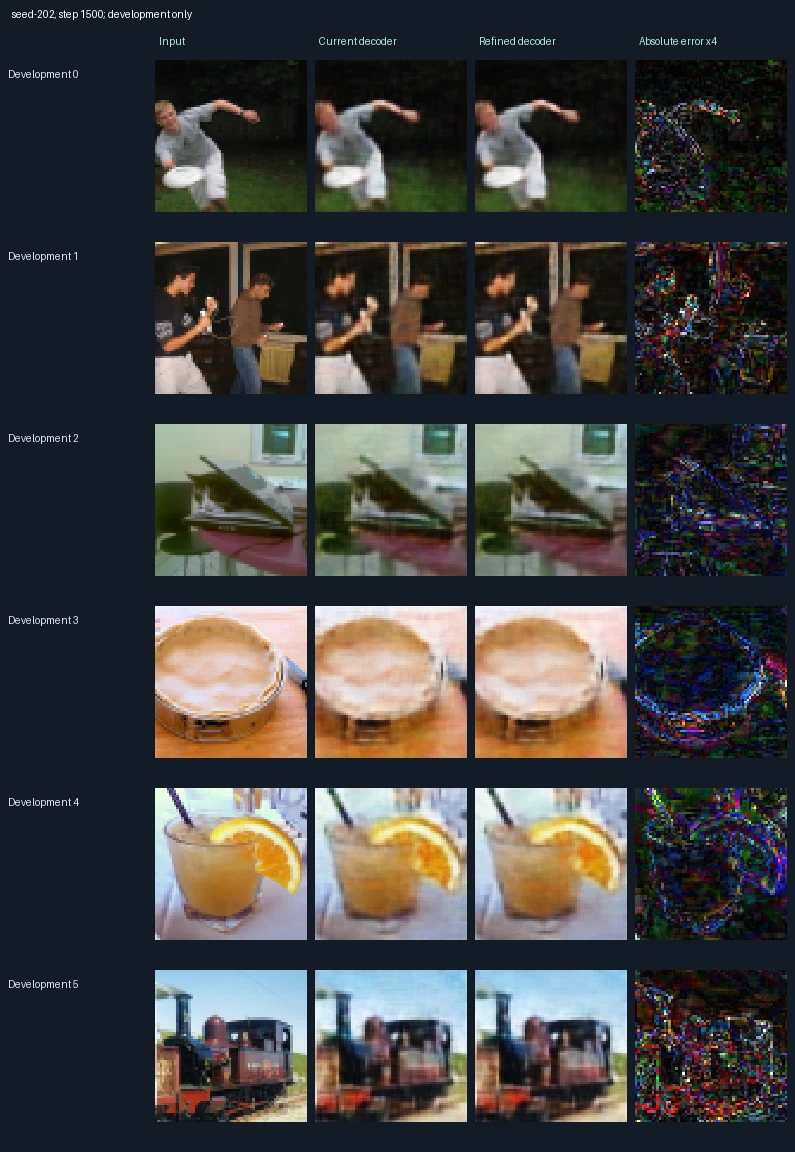
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 1,750 weight updates
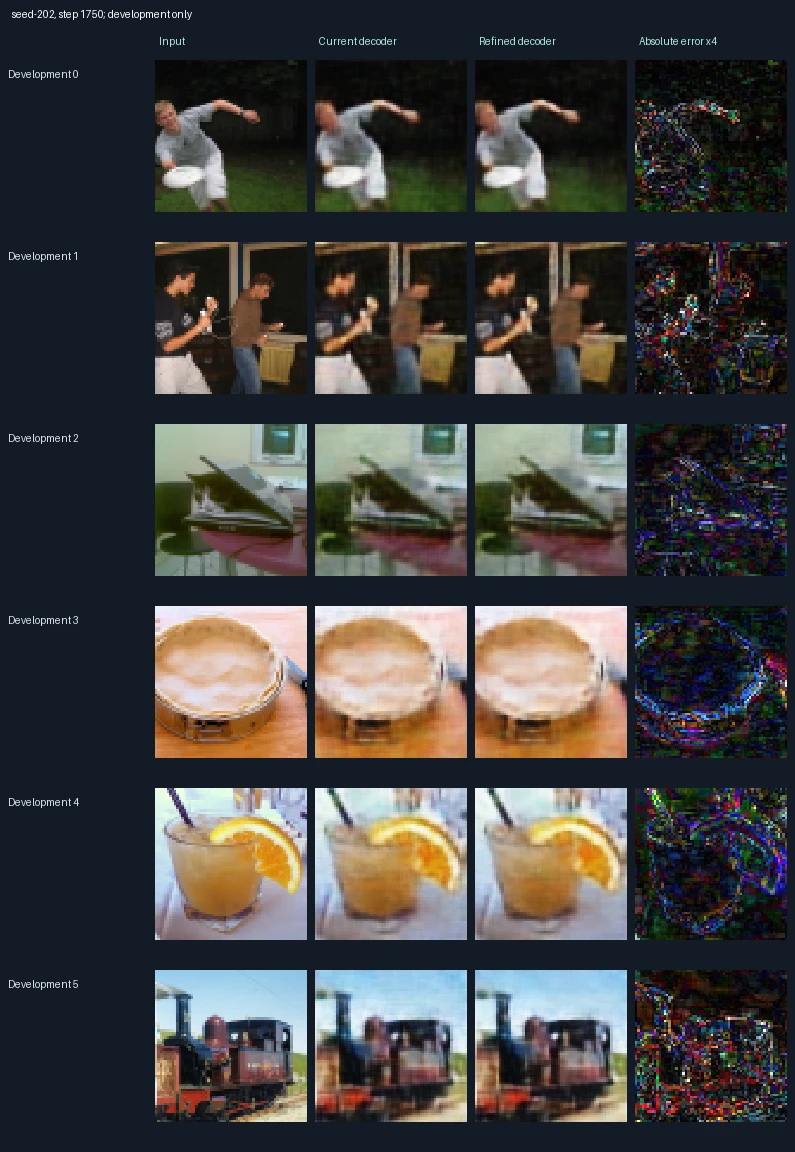
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 2,000 weight updates
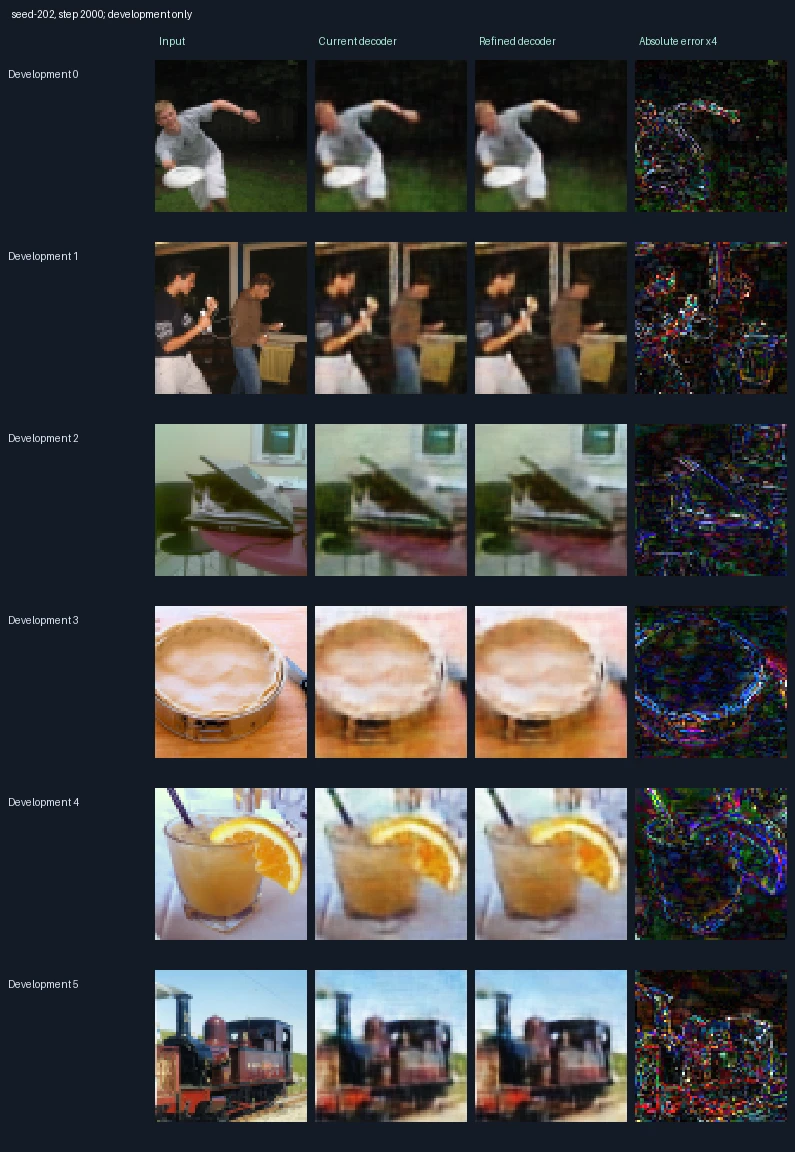
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 2,250 weight updates
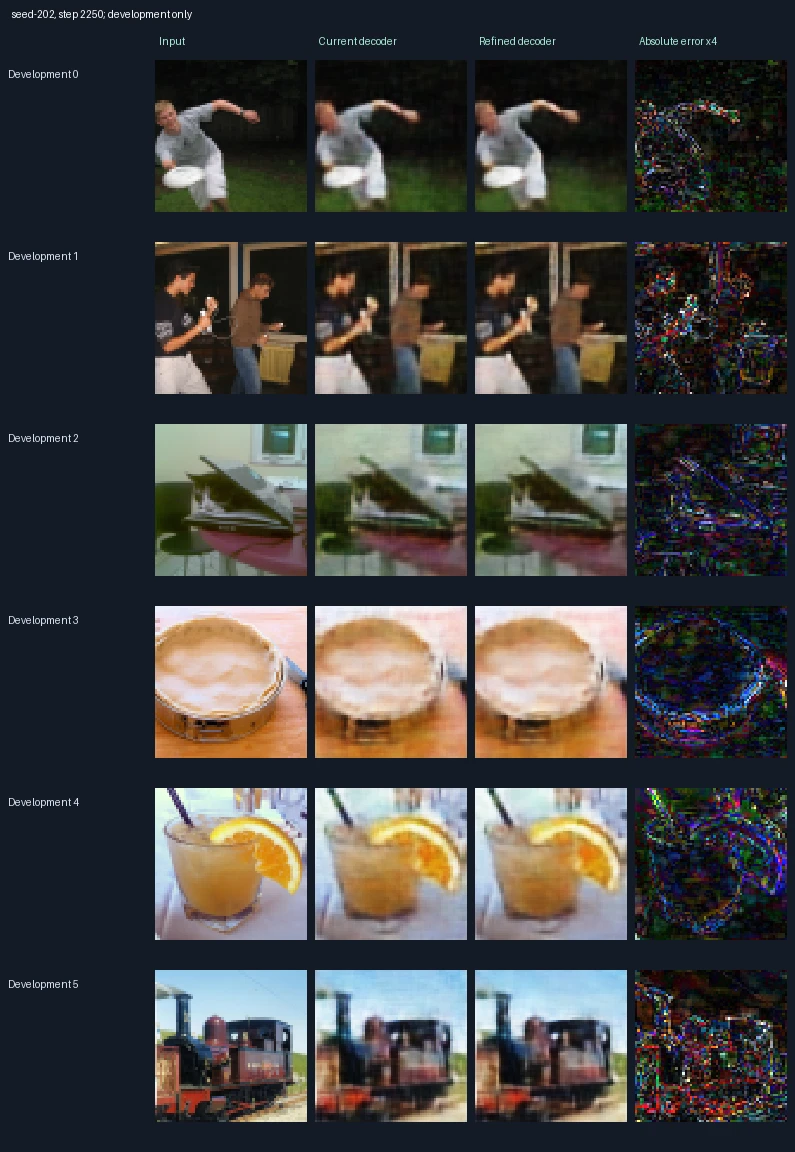
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 2,500 weight updates
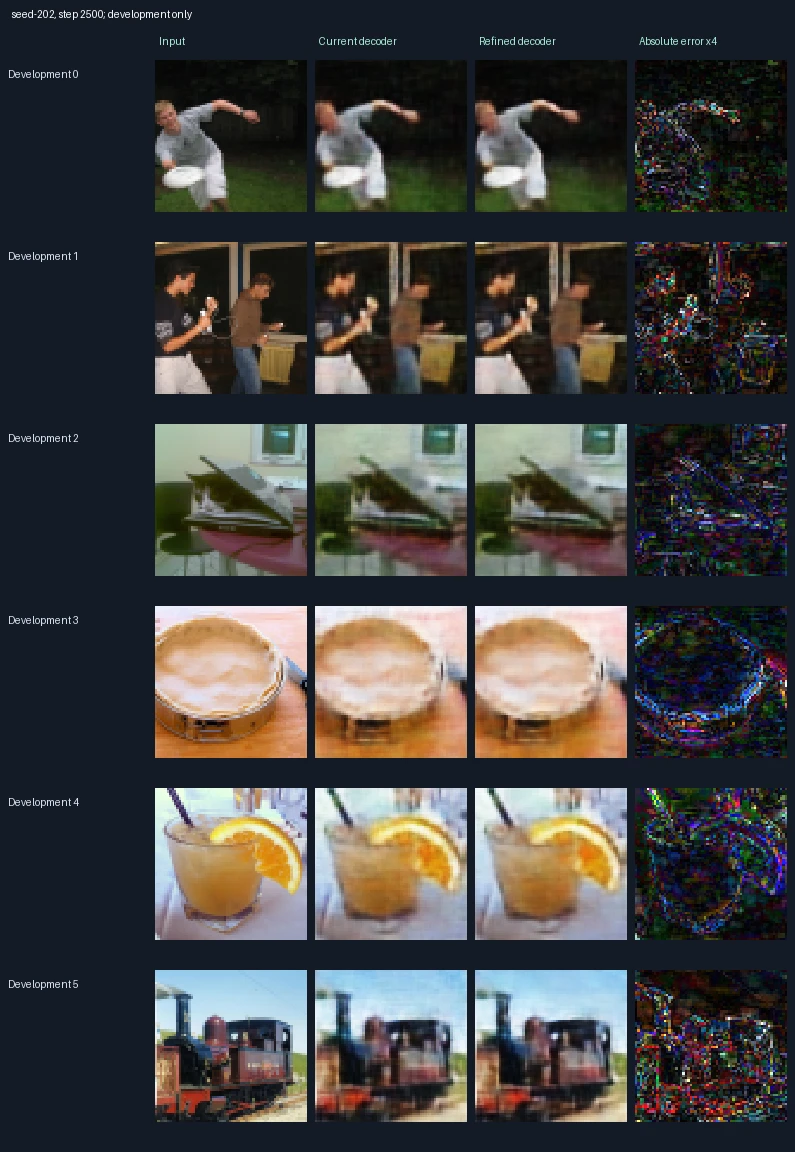
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 2,750 weight updates
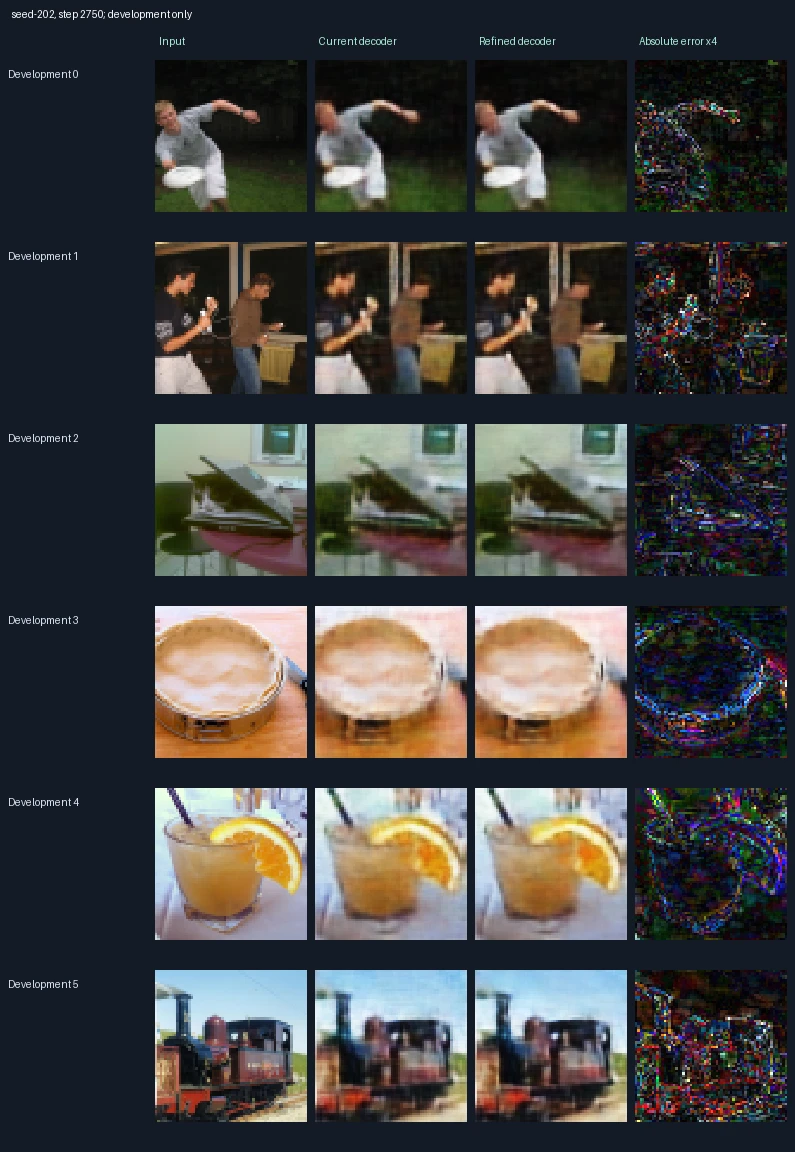
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 3,000 weight updates
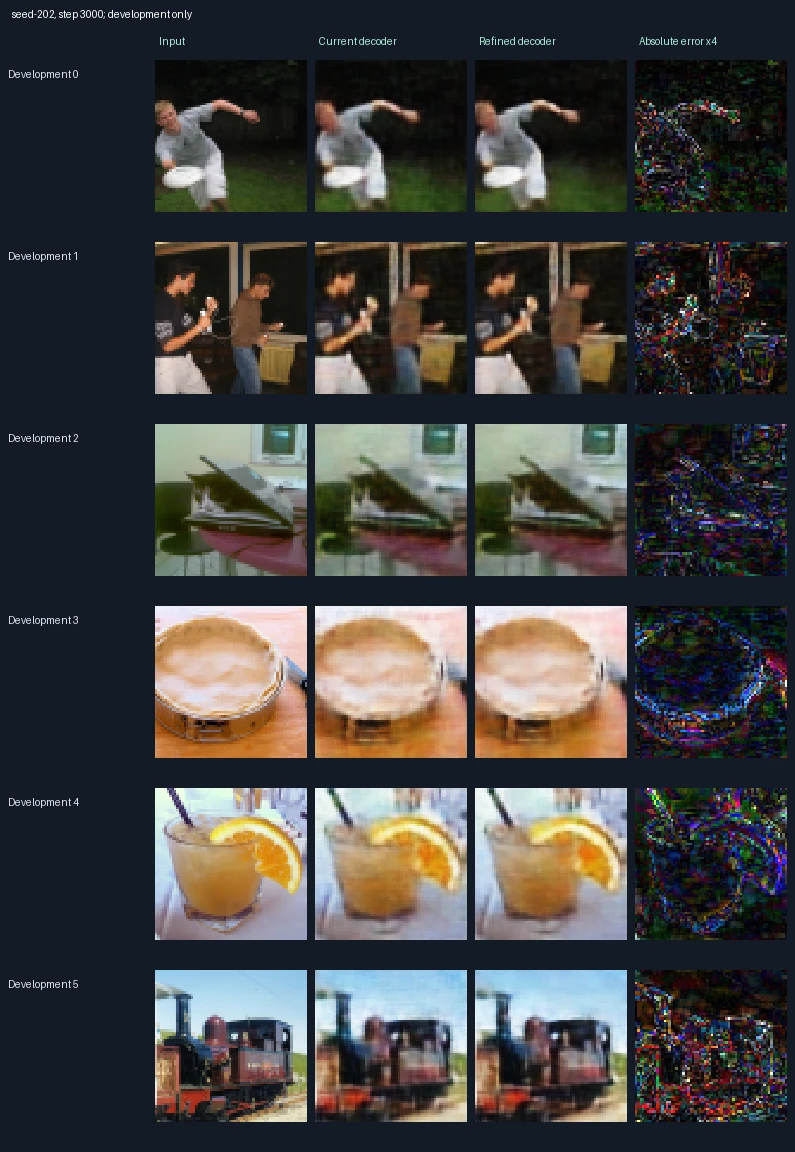
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 3,250 weight updates
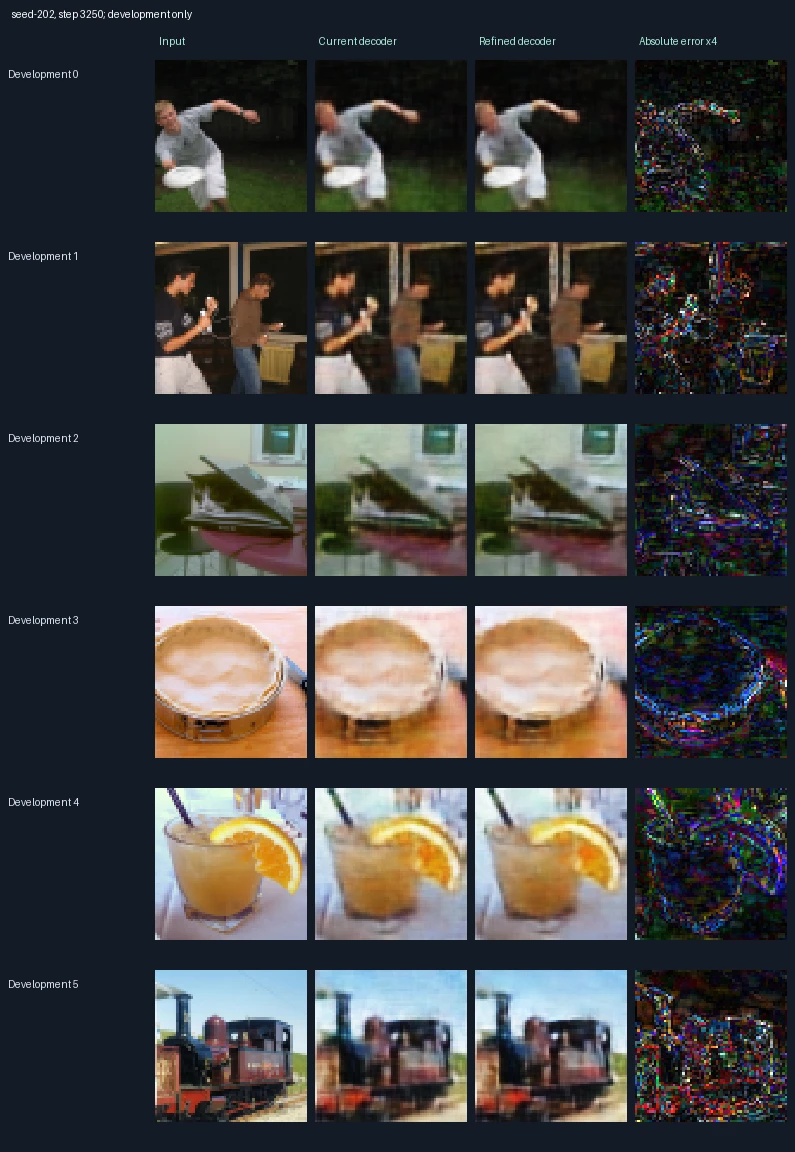
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 3,500 weight updates
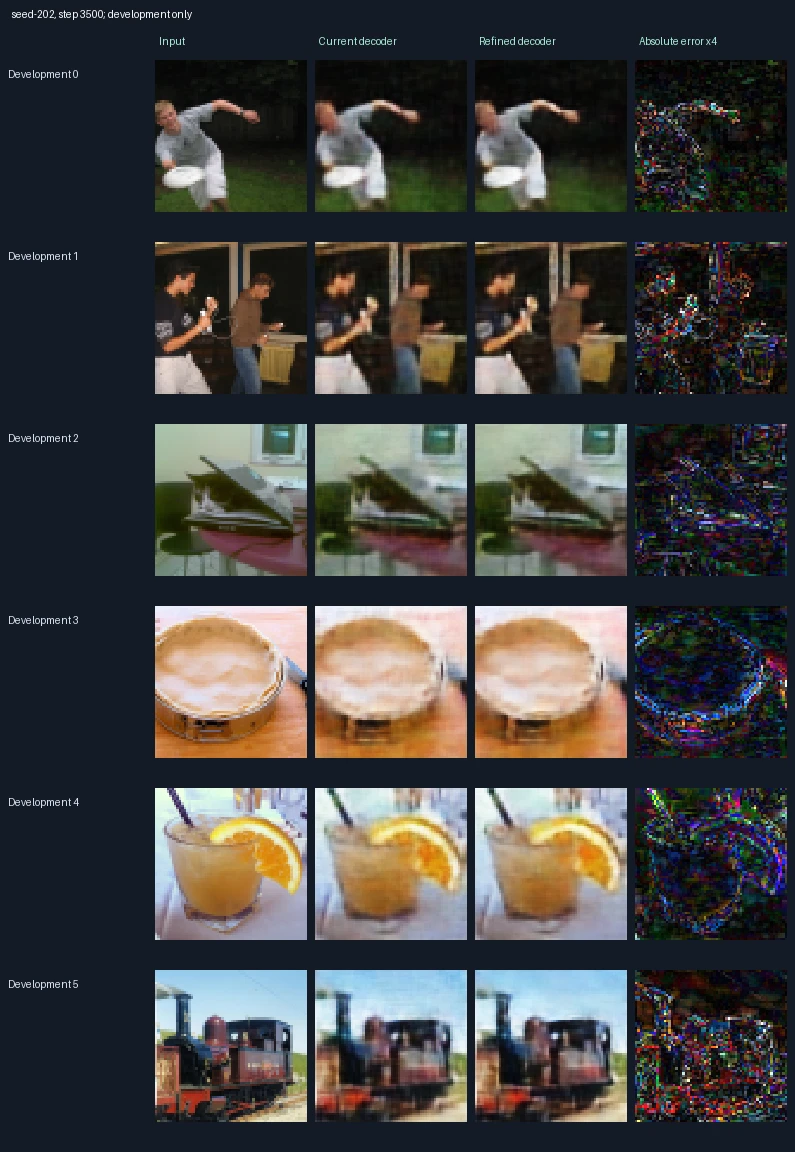
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 3,750 weight updates
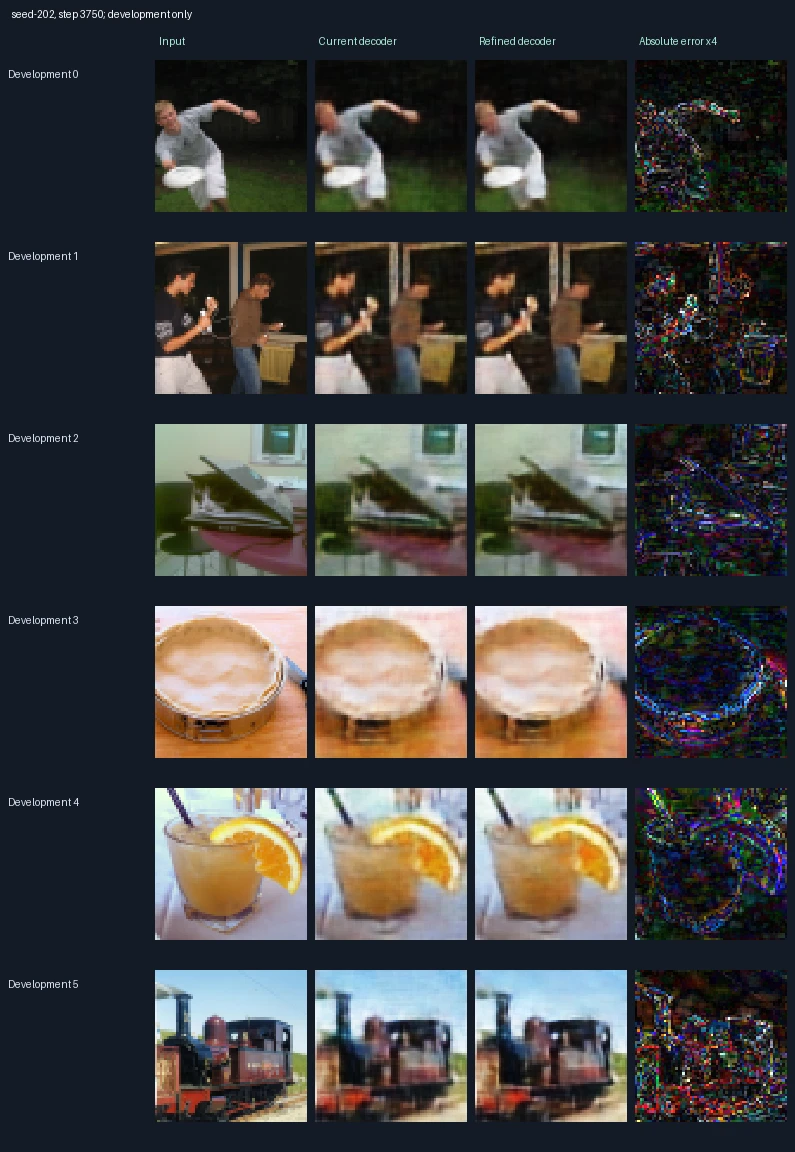
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 2: 4,000 weight updates
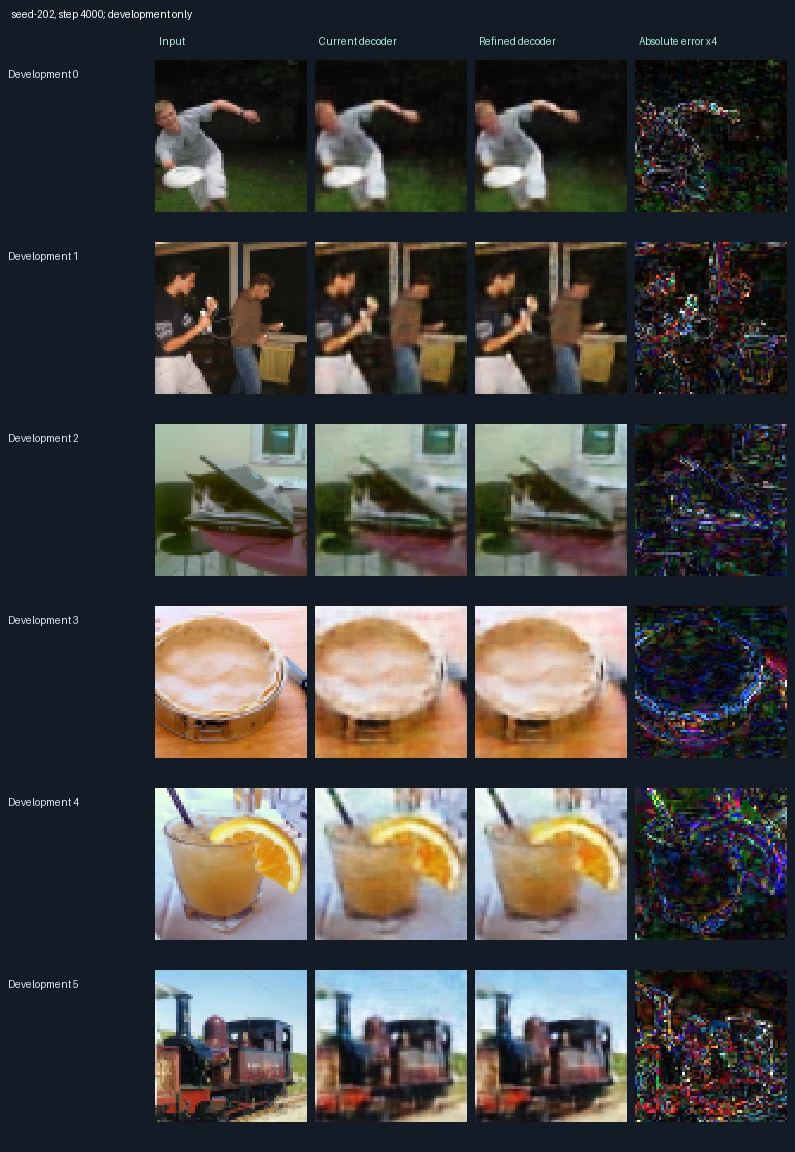
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 2; the image label “seed-202” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 0 weight updates
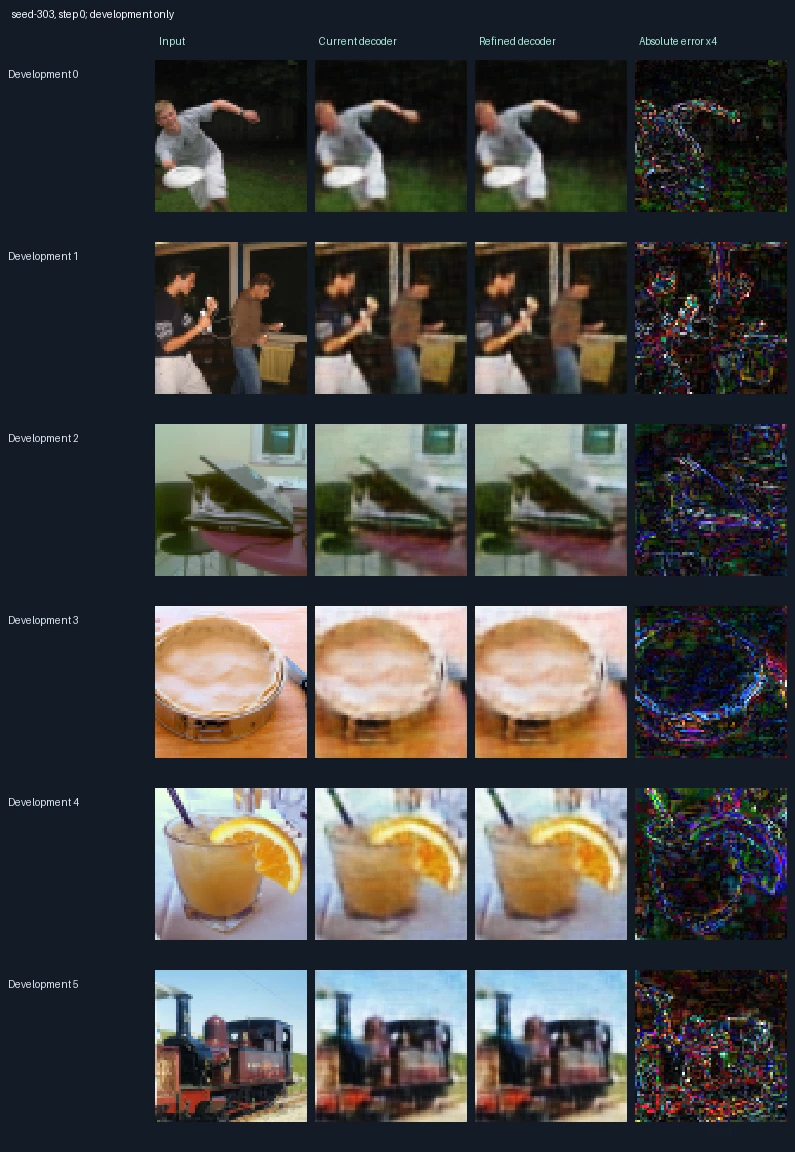
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better. Zero updates records the starting model.
Decoder refinement, training repetition 3: 250 weight updates
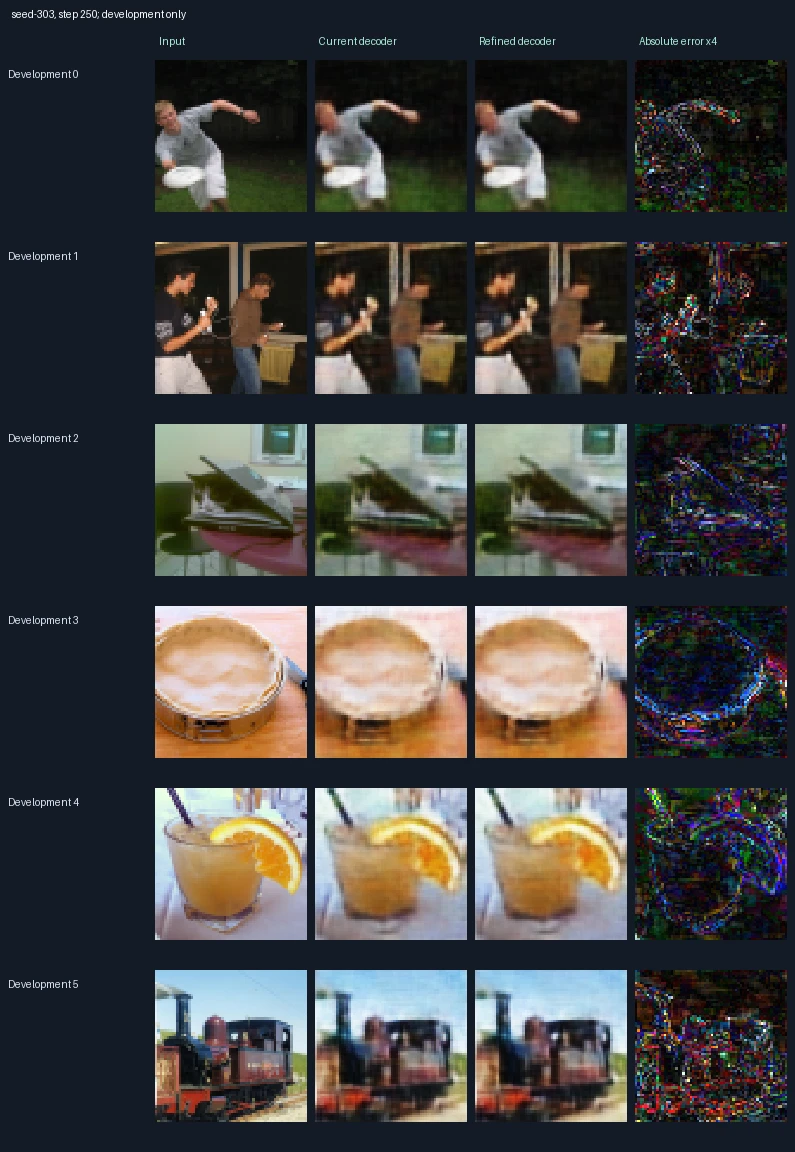
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 500 weight updates
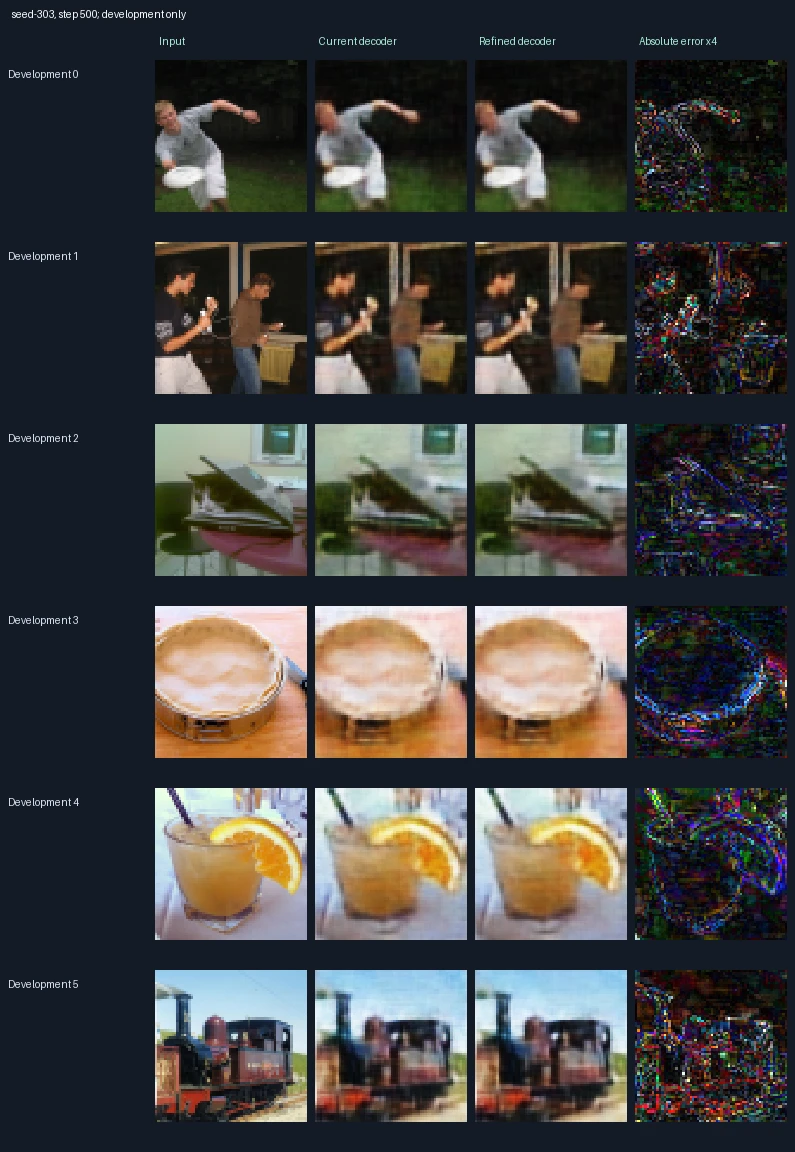
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 750 weight updates
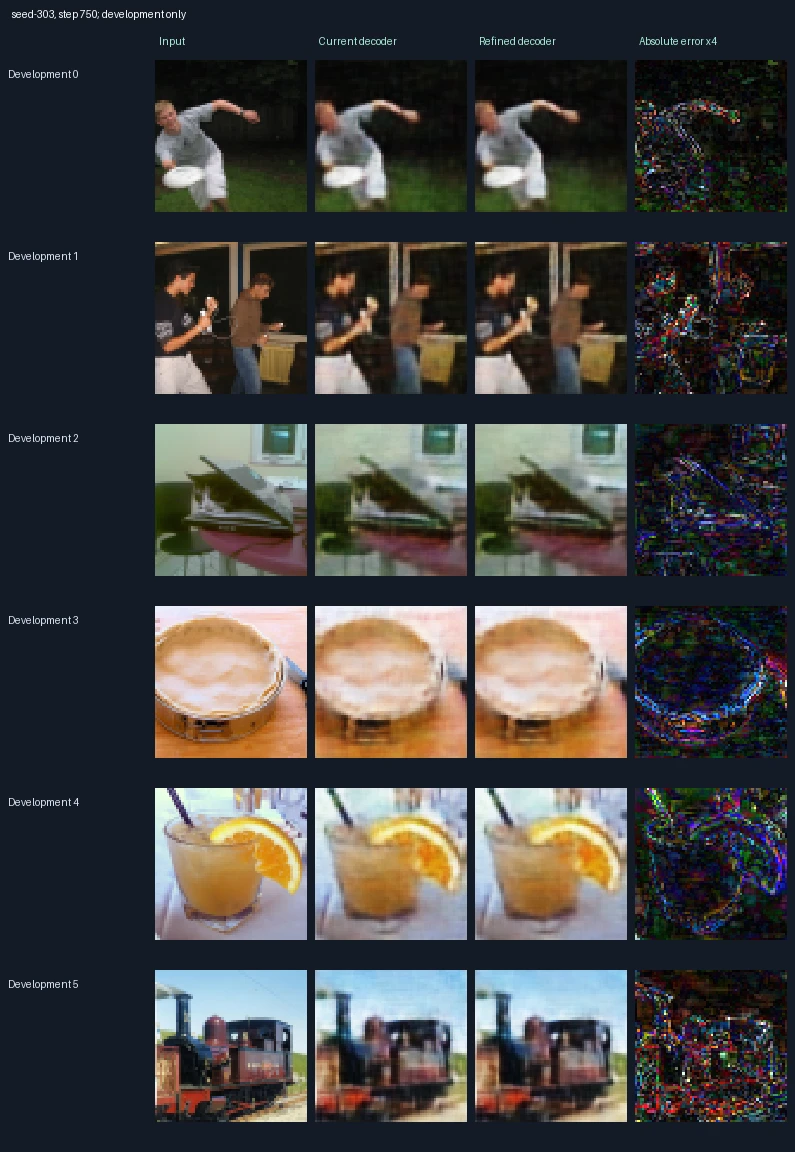
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 1,000 weight updates
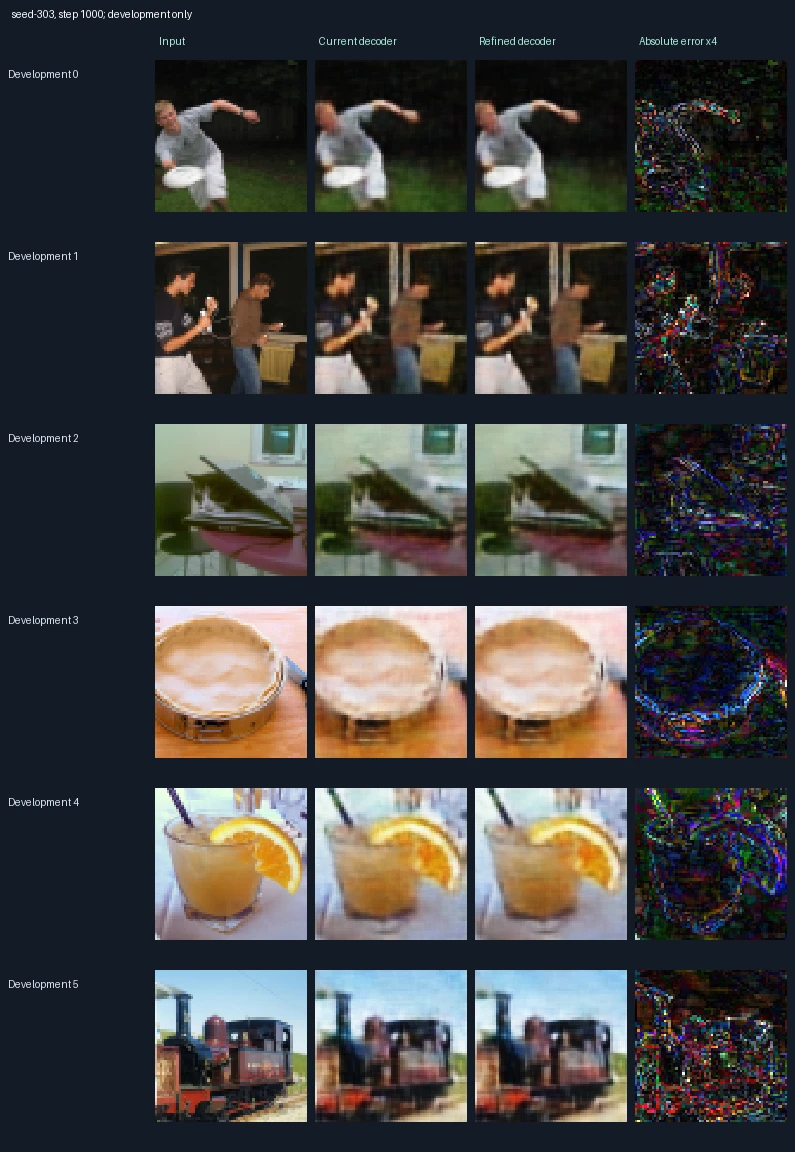
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 1,250 weight updates
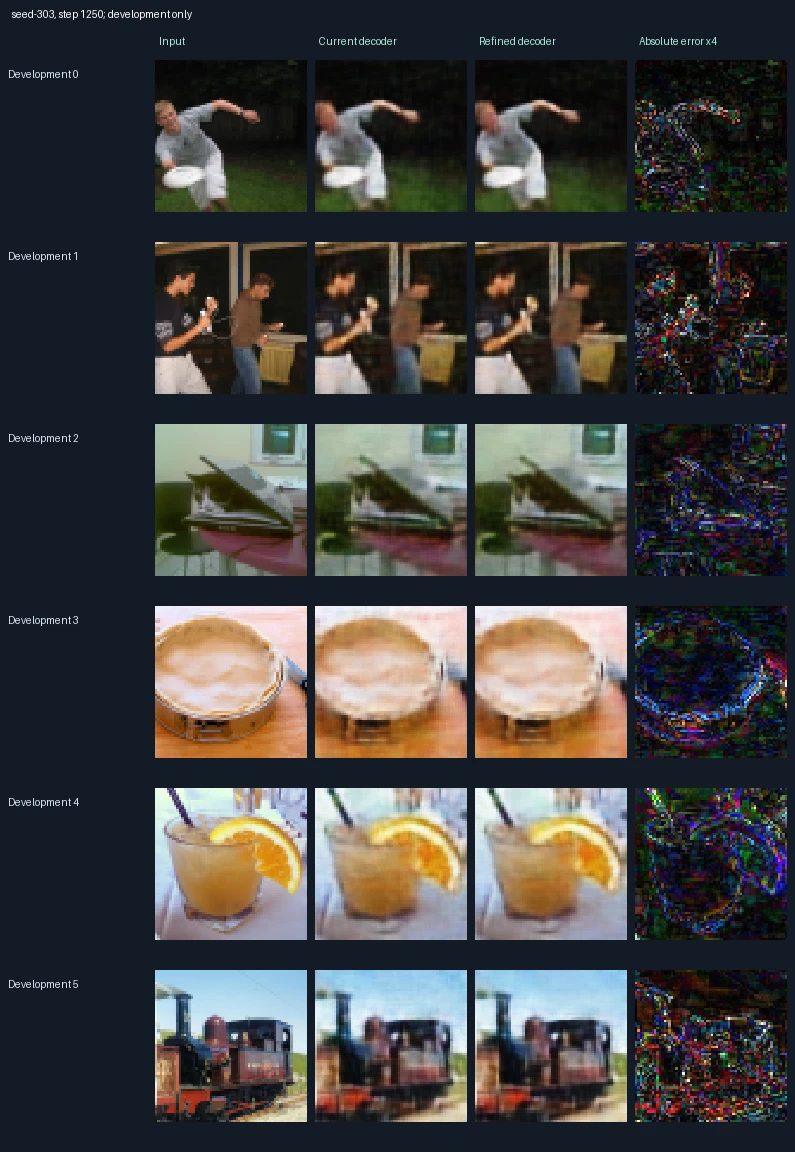
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 1,500 weight updates
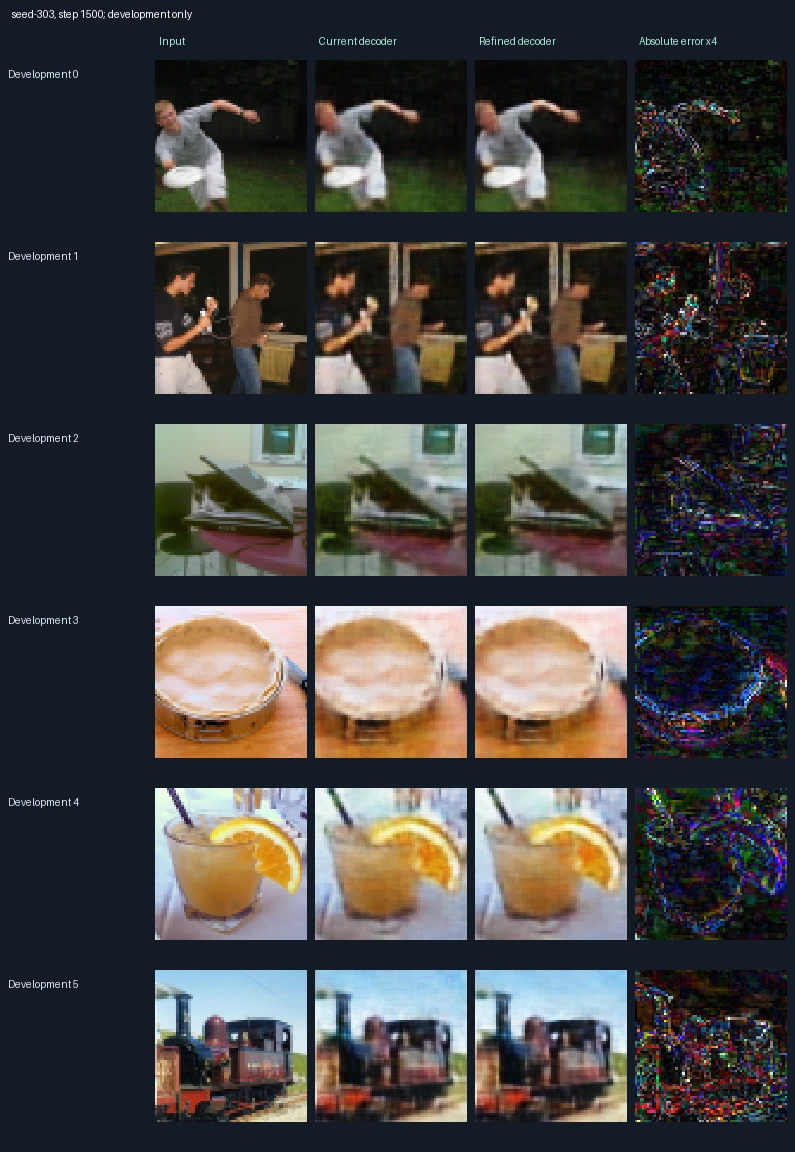
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 1,750 weight updates
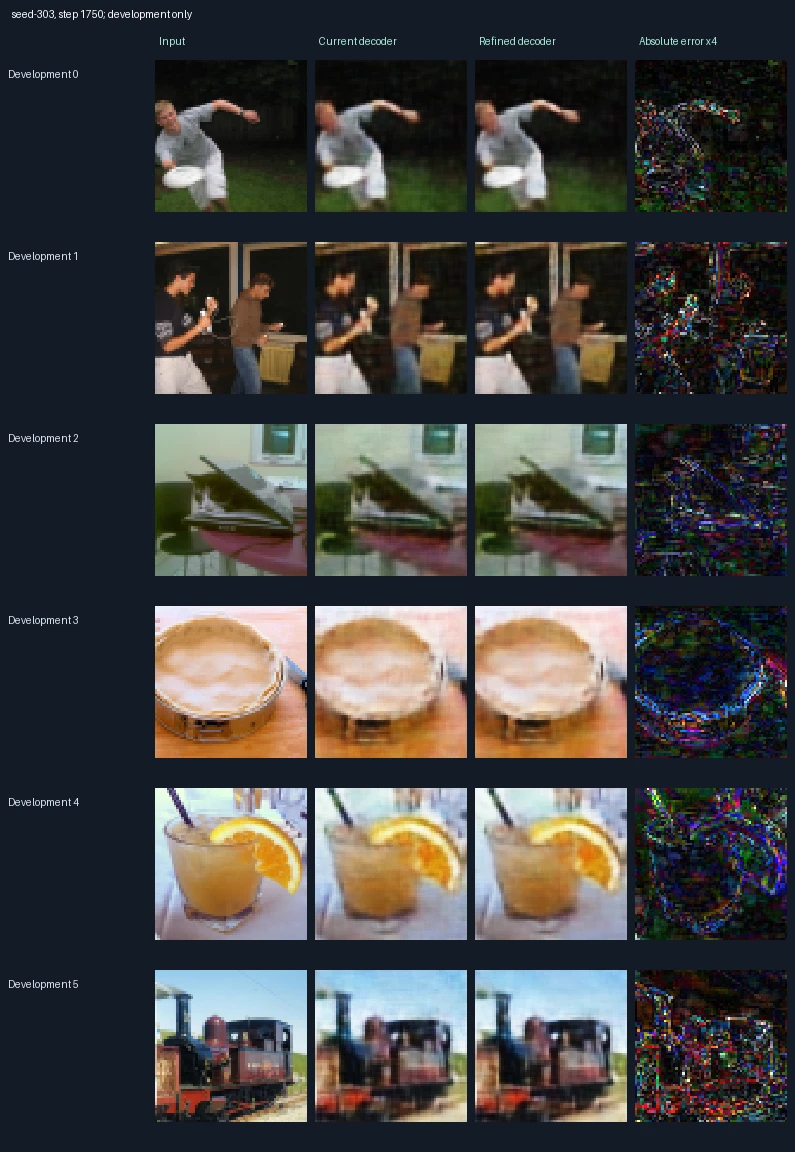
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 2,000 weight updates
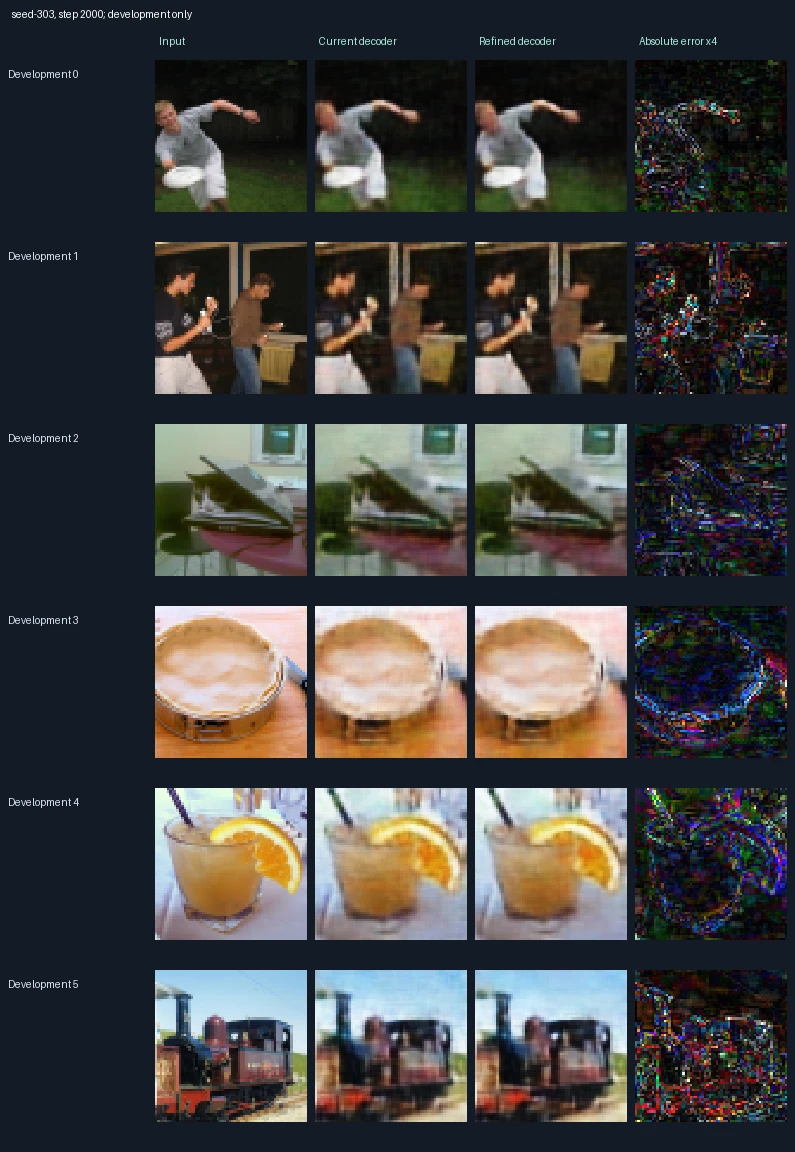
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 2,250 weight updates
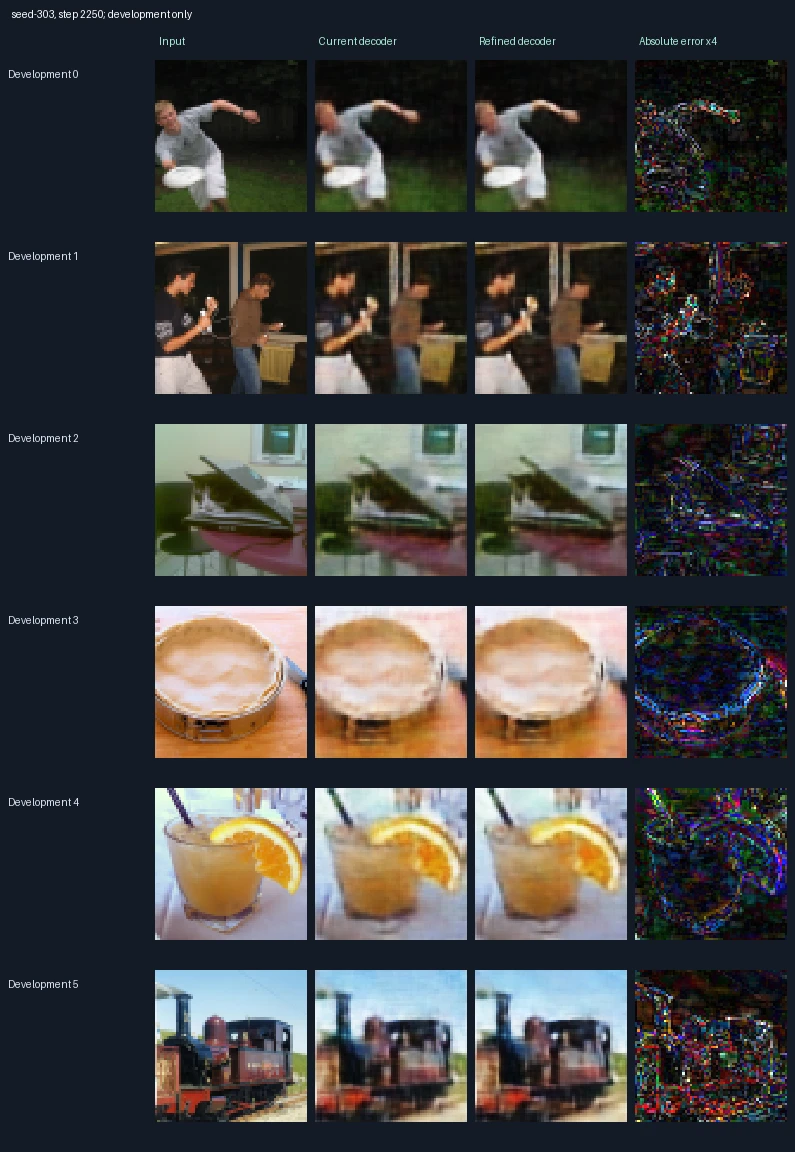
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 2,500 weight updates
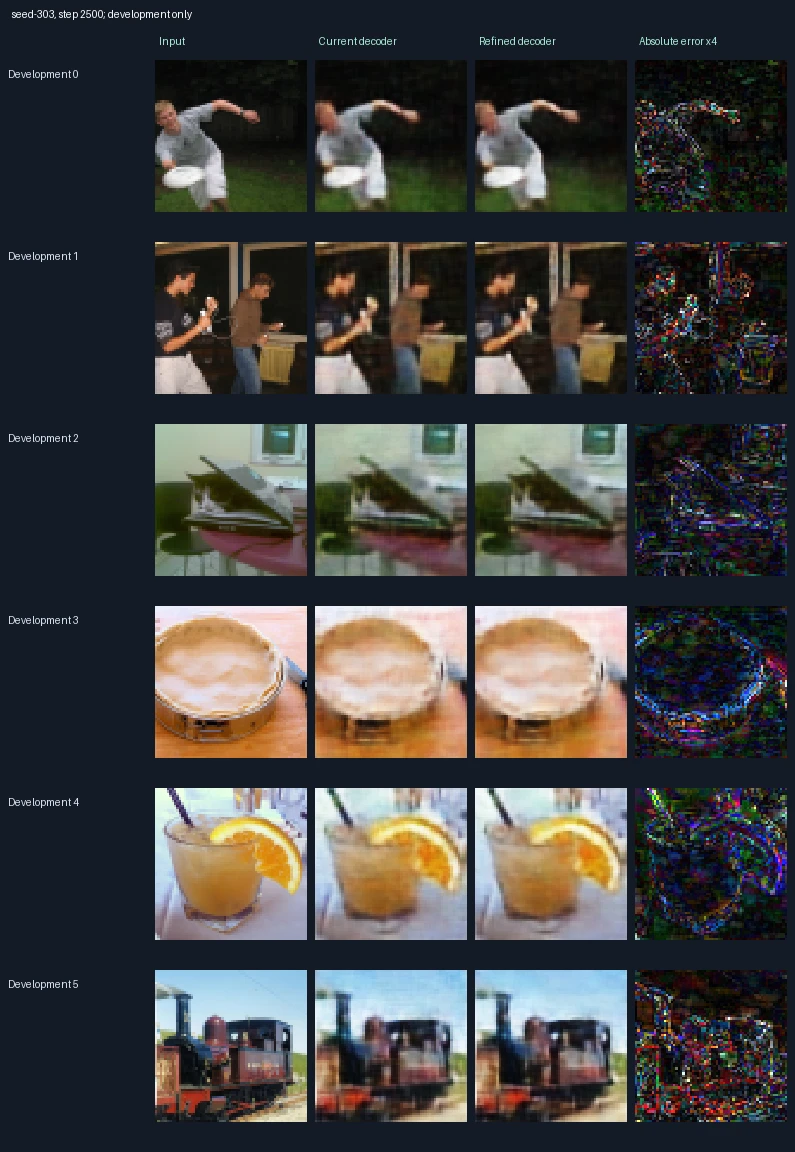
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 2,750 weight updates
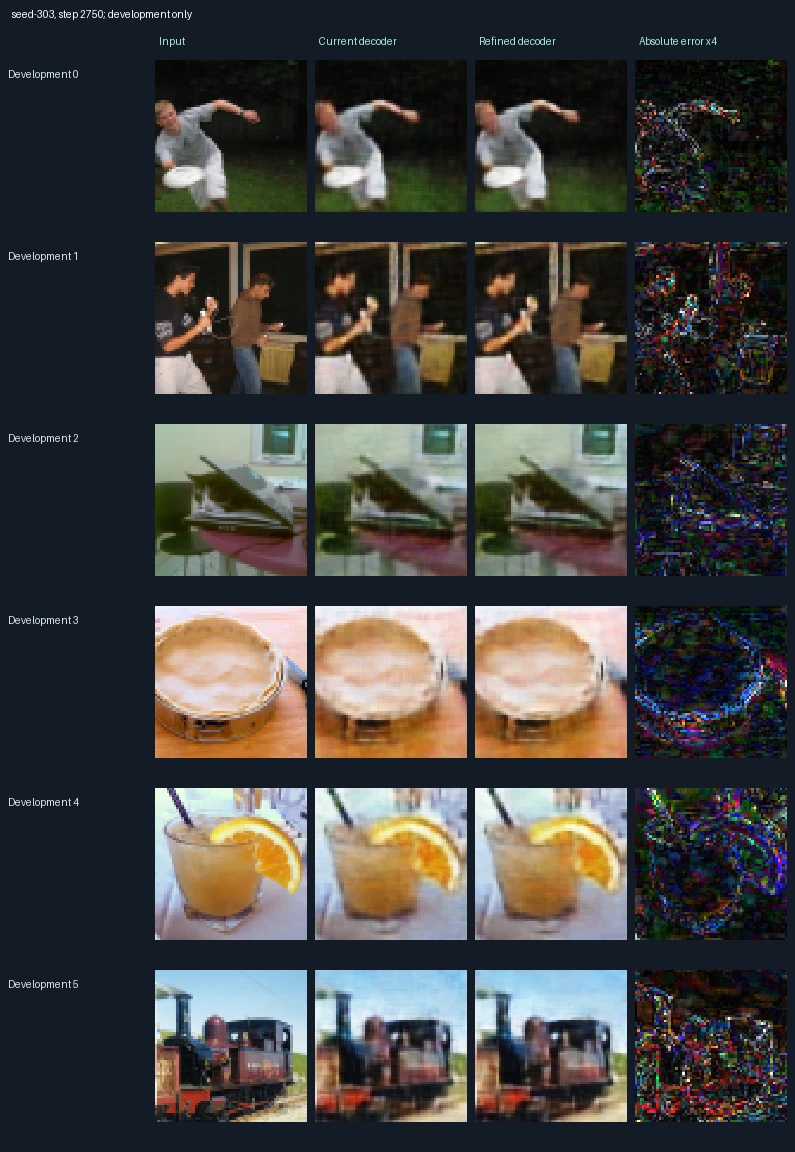
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 3,000 weight updates
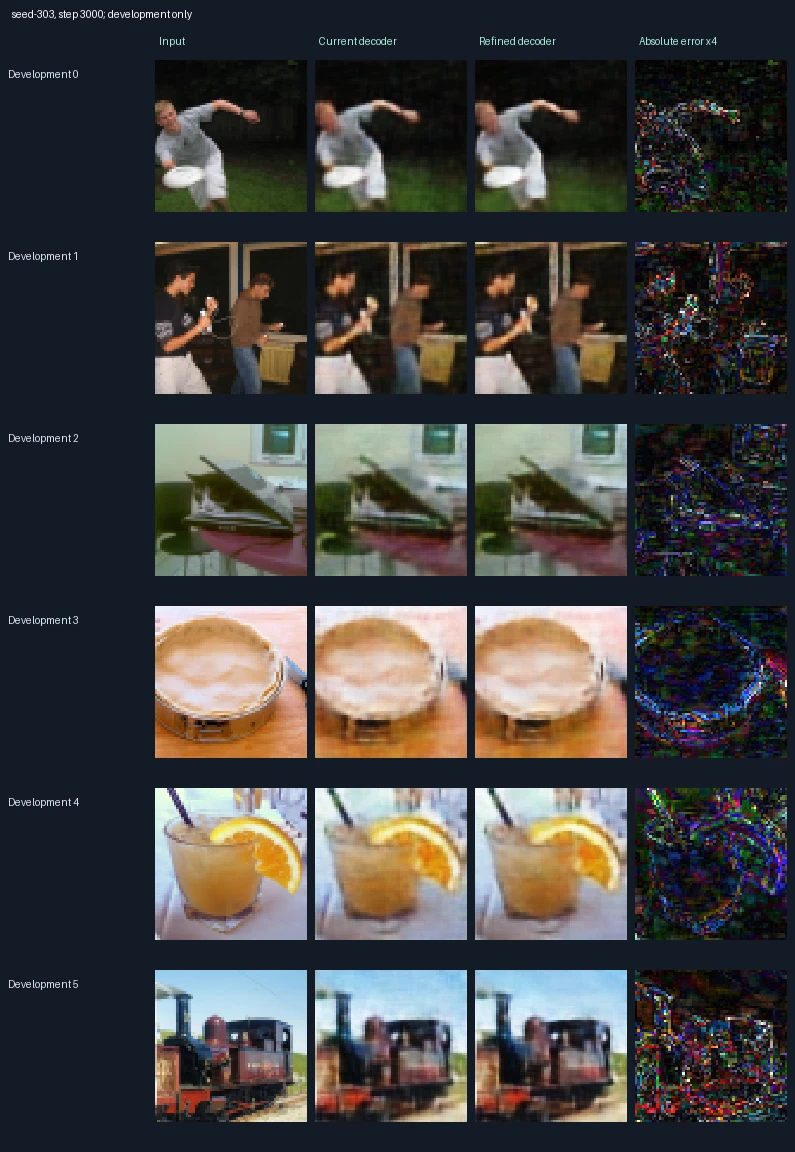
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 3,250 weight updates
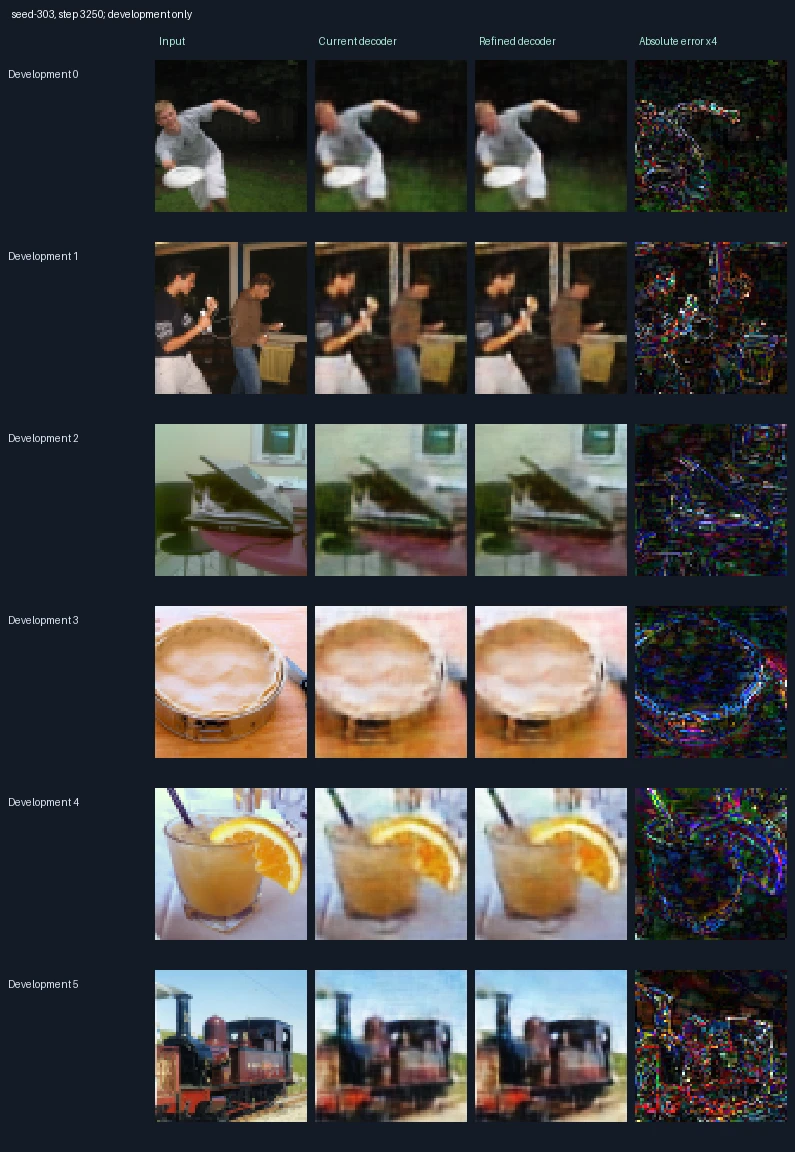
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 3,500 weight updates
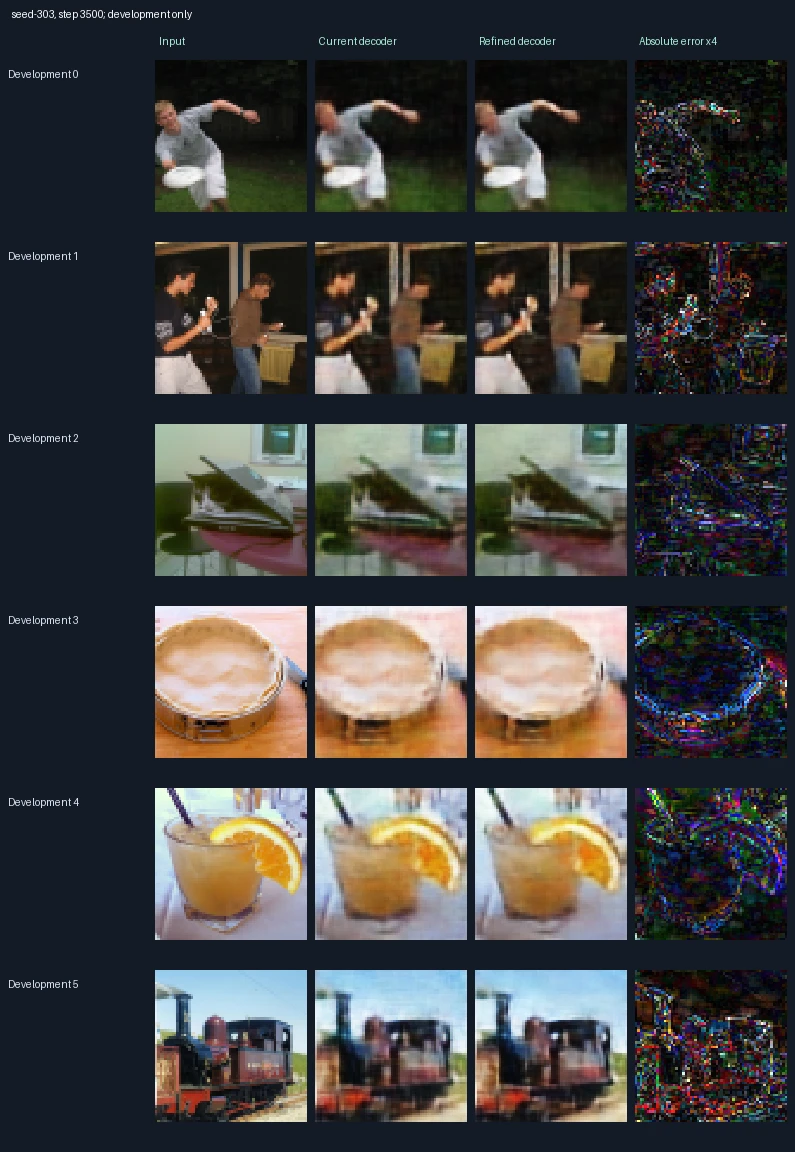
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 3,750 weight updates
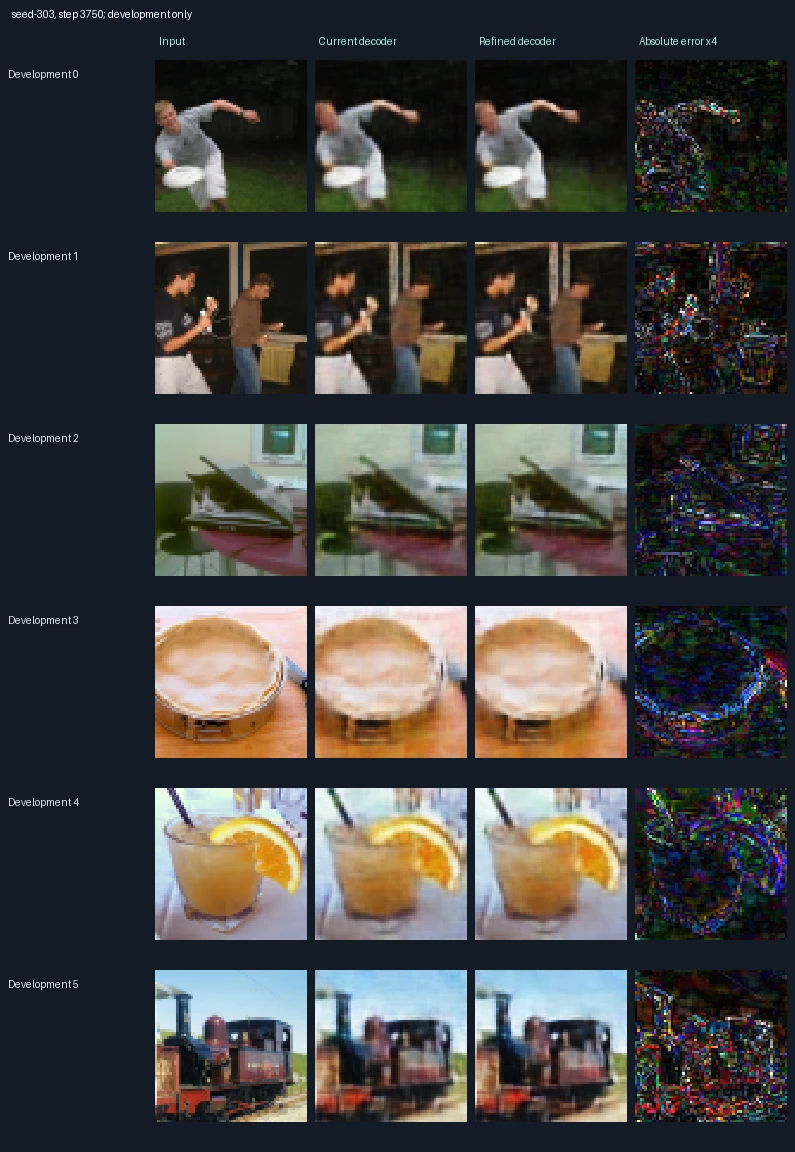
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.
Decoder refinement, training repetition 3: 4,000 weight updates
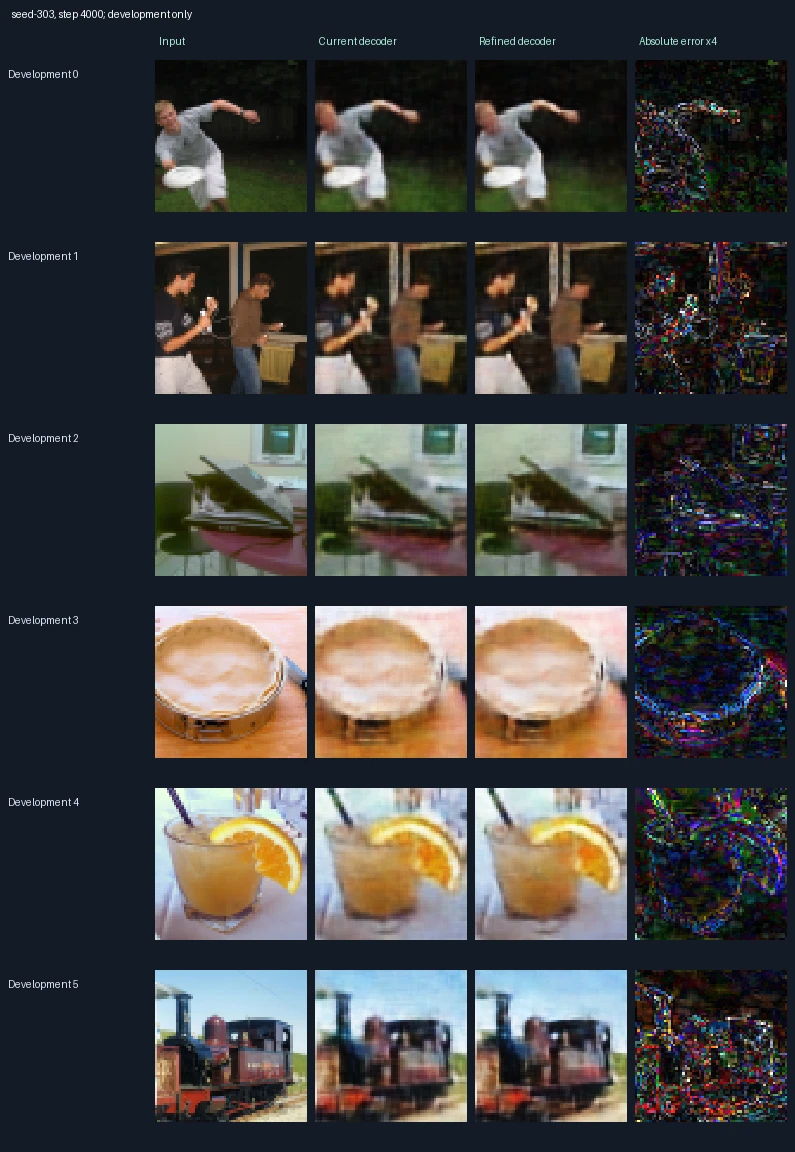
Six fixed development photographs, excluded from gradient updates and used to monitor model quality. Left to right: input pixels, reconstruction using the starting decoder, reconstruction using the refined decoder, and the refined decoder’s error. Both decoders receive identical VSA vectors. This is training repetition 3; the image label “seed-303” identifies its randomization setting. The model receives a 64 × 64 RGB image; photographs are center-cropped and resized before encoding. Enlargement here adds no detail. Error panels show four times the absolute RGB difference from the reference, separately for each color channel, clipped at full brightness. Darker pixels mean smaller errors; black is zero or below the display’s precision. The scale is fixed across examples, not adjusted to make each image look better.

Limits and next question

One fixed seed-29 refined encoder, one 64 by 64 PatchSum architecture and one registered decoder-training recipe. Decoder seeds do not repeat encoder training. Pixel fidelity, edge detail and actual stored-memory readback receive separate conclusions; improved reconstruction does not establish acquired understanding, reading or compositional usefulness. Prior historical exposure and all semantic duplicates cannot be ruled out. Encoder-space drift remains a separate adoption question. No existing life is migrated or replaced.

Next question. Can mixed photograph-and-writing training recover the photo gain while retaining writing fidelity and readback from the old vector space?

Inspect the evidence

Download the methods and measurements for this experiment. Large training and saved-state files are not included.