Type a section name and press Enter. Use “help” for the list.
Cliste experiment
Does feedback through the frozen decoder improve visual completion?
Registered 11 Oct 2026 · Snapshot 12 Oct 2026
The question
Hide a rectangle in a photograph, ask the trained component to fill it by constructing VSA vectors, then decode the result. Compare two ways of training that component: vector error alone, or vector error plus feedback from the decoded pixels.
Why this experiment?
Lower vector error did not guarantee better images. A matched training comparison asks whether feedback through the fixed decoder improves the actual missing-region task.
How it works
Fit the matched vector-only and decoder-aware predictors, then use them to fill concealed rectangles. An external interruption stopped the second evaluation after 59 of 64 requests. Completed stages and partial outputs were retained; the later recovery finishes the same comparison.
Follow this part of the investigation: Does image feedback improve filling a hidden rectangle? →Implementation and comparison details
Train two fresh copies of the same full-dimensional specialist for 2,000 updates. Keep the 512 training photographs, initialization, random draws, codec and budgets matched. One objective adds equally weighted hidden and visible pixel errors, with a fixed coefficient of 10. Evaluate both candidates on 32 fresh development and 32 fresh test photographs.
What happened
Unexpected external termination before paired observation. Both fixed fits and diagnostics and all64 vector-only requests completed;59of64 decoder-aware requests were saved. All partial evidence is preserved. No complete objective-quality verdict is available. A separately registered recovery will reuse completed stages and repeat only the incomplete sampling phase without changing the scientific methods.
Results and visual artifacts
Open a figure for its input, comparison, and result. Click an image to enlarge it.
The masked photograph is the input; the complete original is shown only as an evaluation reference. The trained predictor constructs VSA vectors to fill the missing rectangle. Meaningful context keeps encoded image regions at their correct positions; shuffled context assigns those encoded regions to wrong positions before prediction. The preserved 'No learned regional context' label removes photo input only from the predictor: the decoder still uses the masked photograph, so the overall system retains context. Every condition shows all four fixed samples, alongside unchanged decoding, cleanup and nearest-memory comparisons. Missing-region details expose local quality; full scenes show the surroundings. No best sample is selected. This public record includes 3 of 293 saved figures: summary comparisons and fixed examples, including every figure referenced by the guide. Reported aggregates include every case; individual records and complete outputs remain in the research archive.
Vector-only objective · photograph 1 · mask 1 · full scene
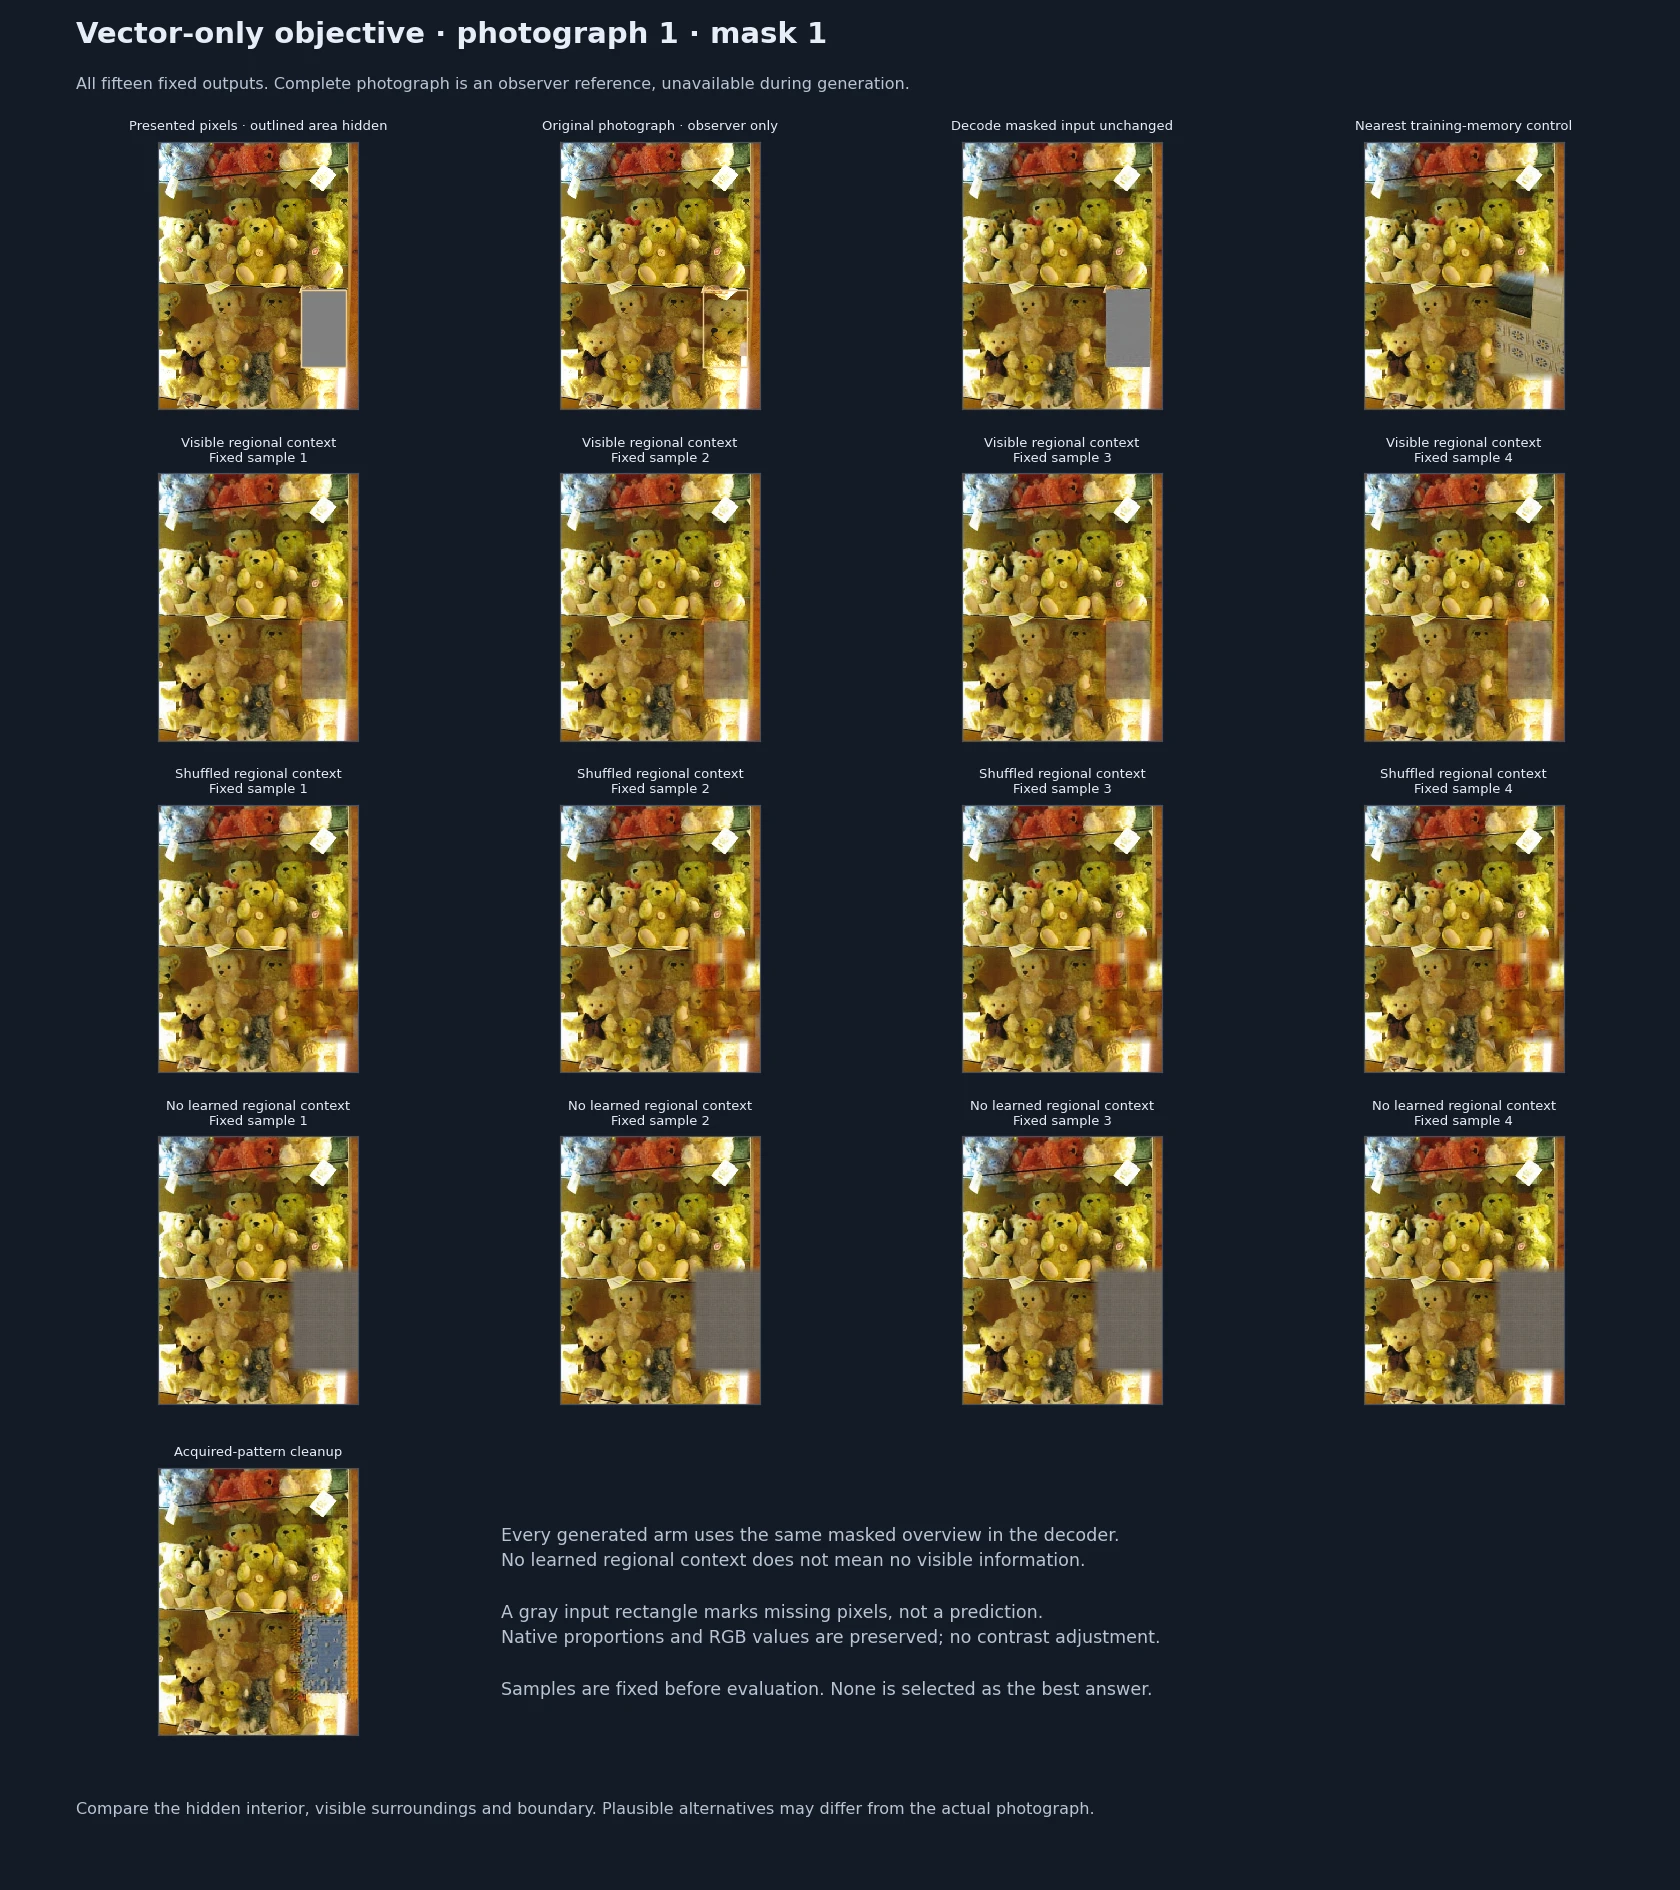
Display derivative: WebP quality 90; maximum edge 2400 px. Original scientific pixels remain in the source run; do not measure this preview.
Vector-only objective · photograph 1 · mask 1 · native-pixel missing region
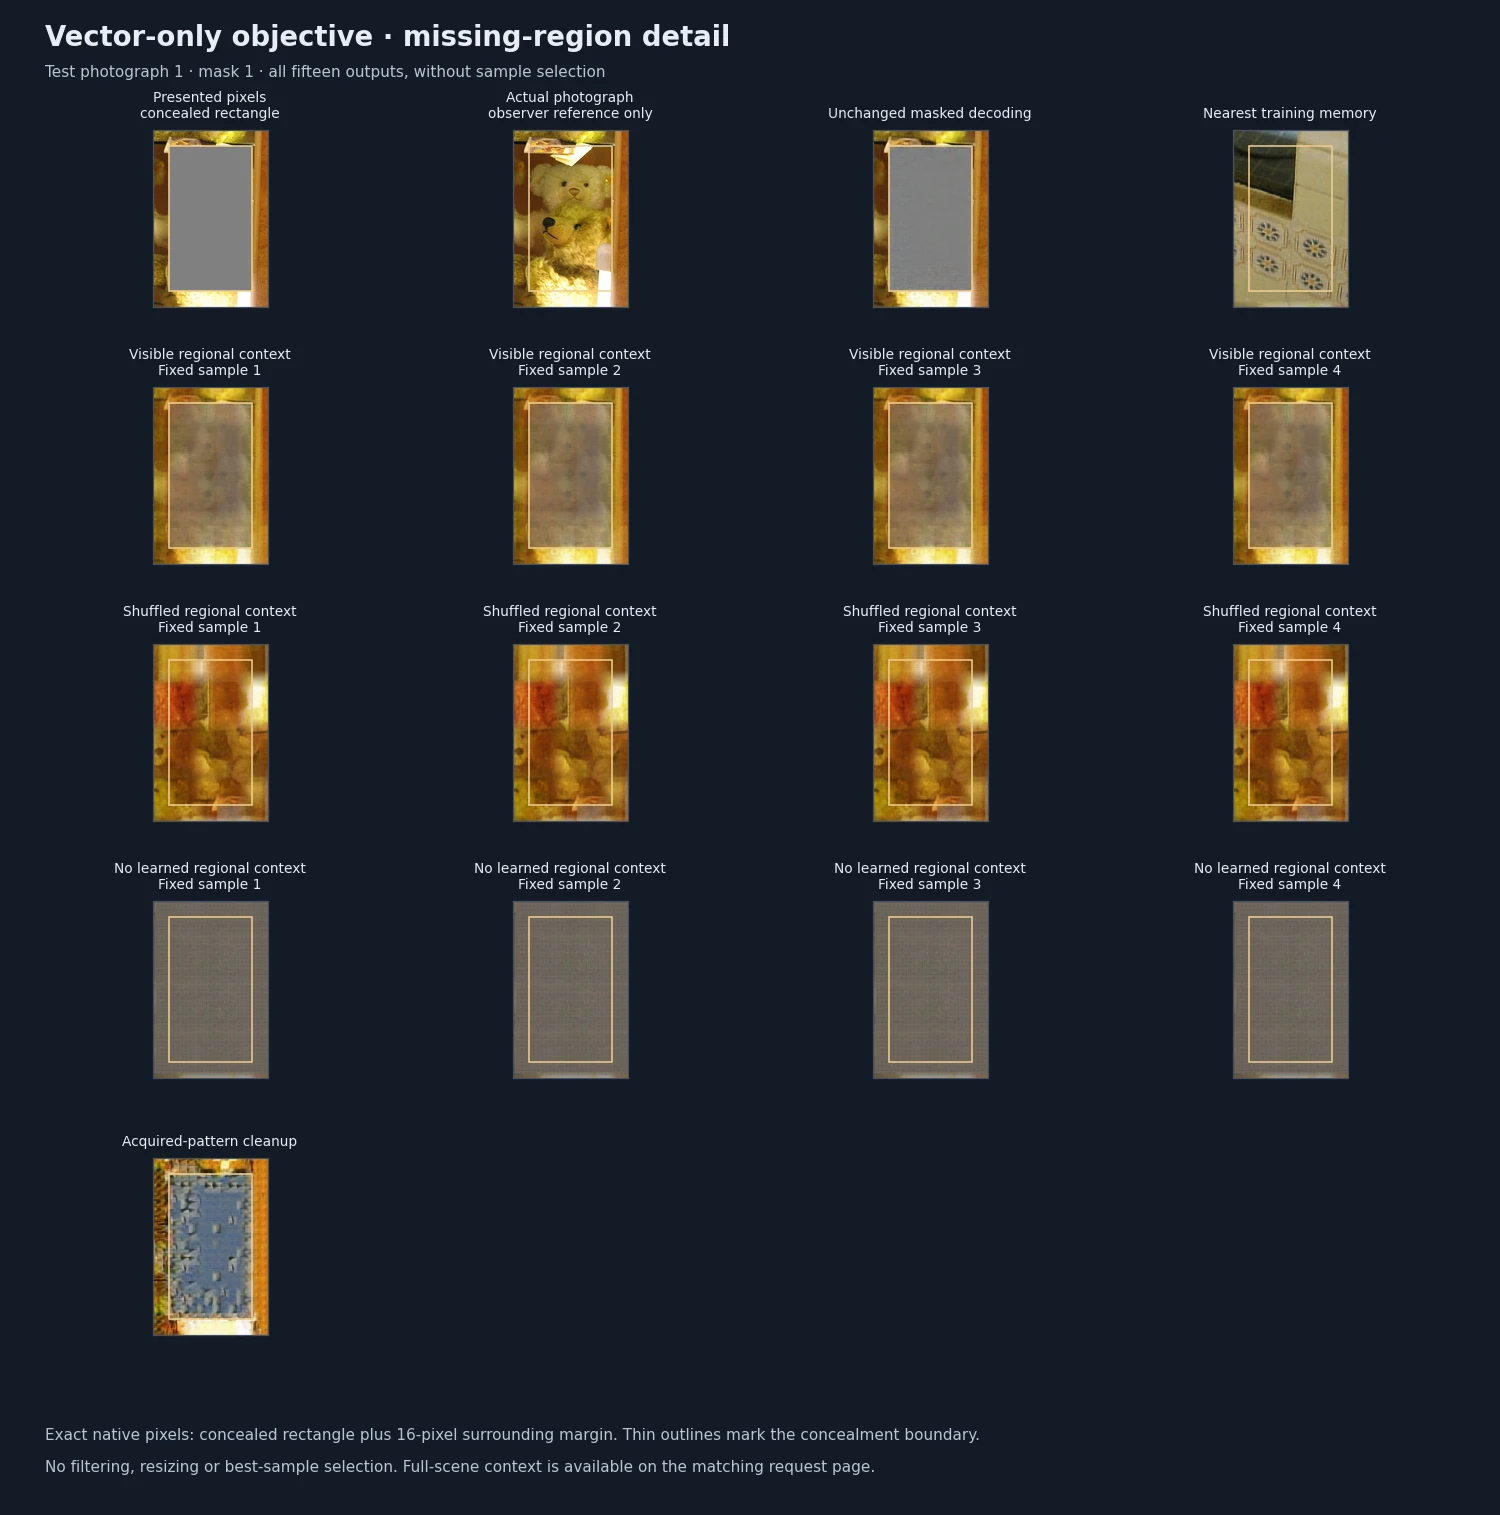
Display derivative: WebP quality 90; maximum edge 2400 px. Original scientific pixels remain in the source run; do not measure this preview.
Decoder-aware objective · photograph 1 · mask 1 · native-pixel missing region
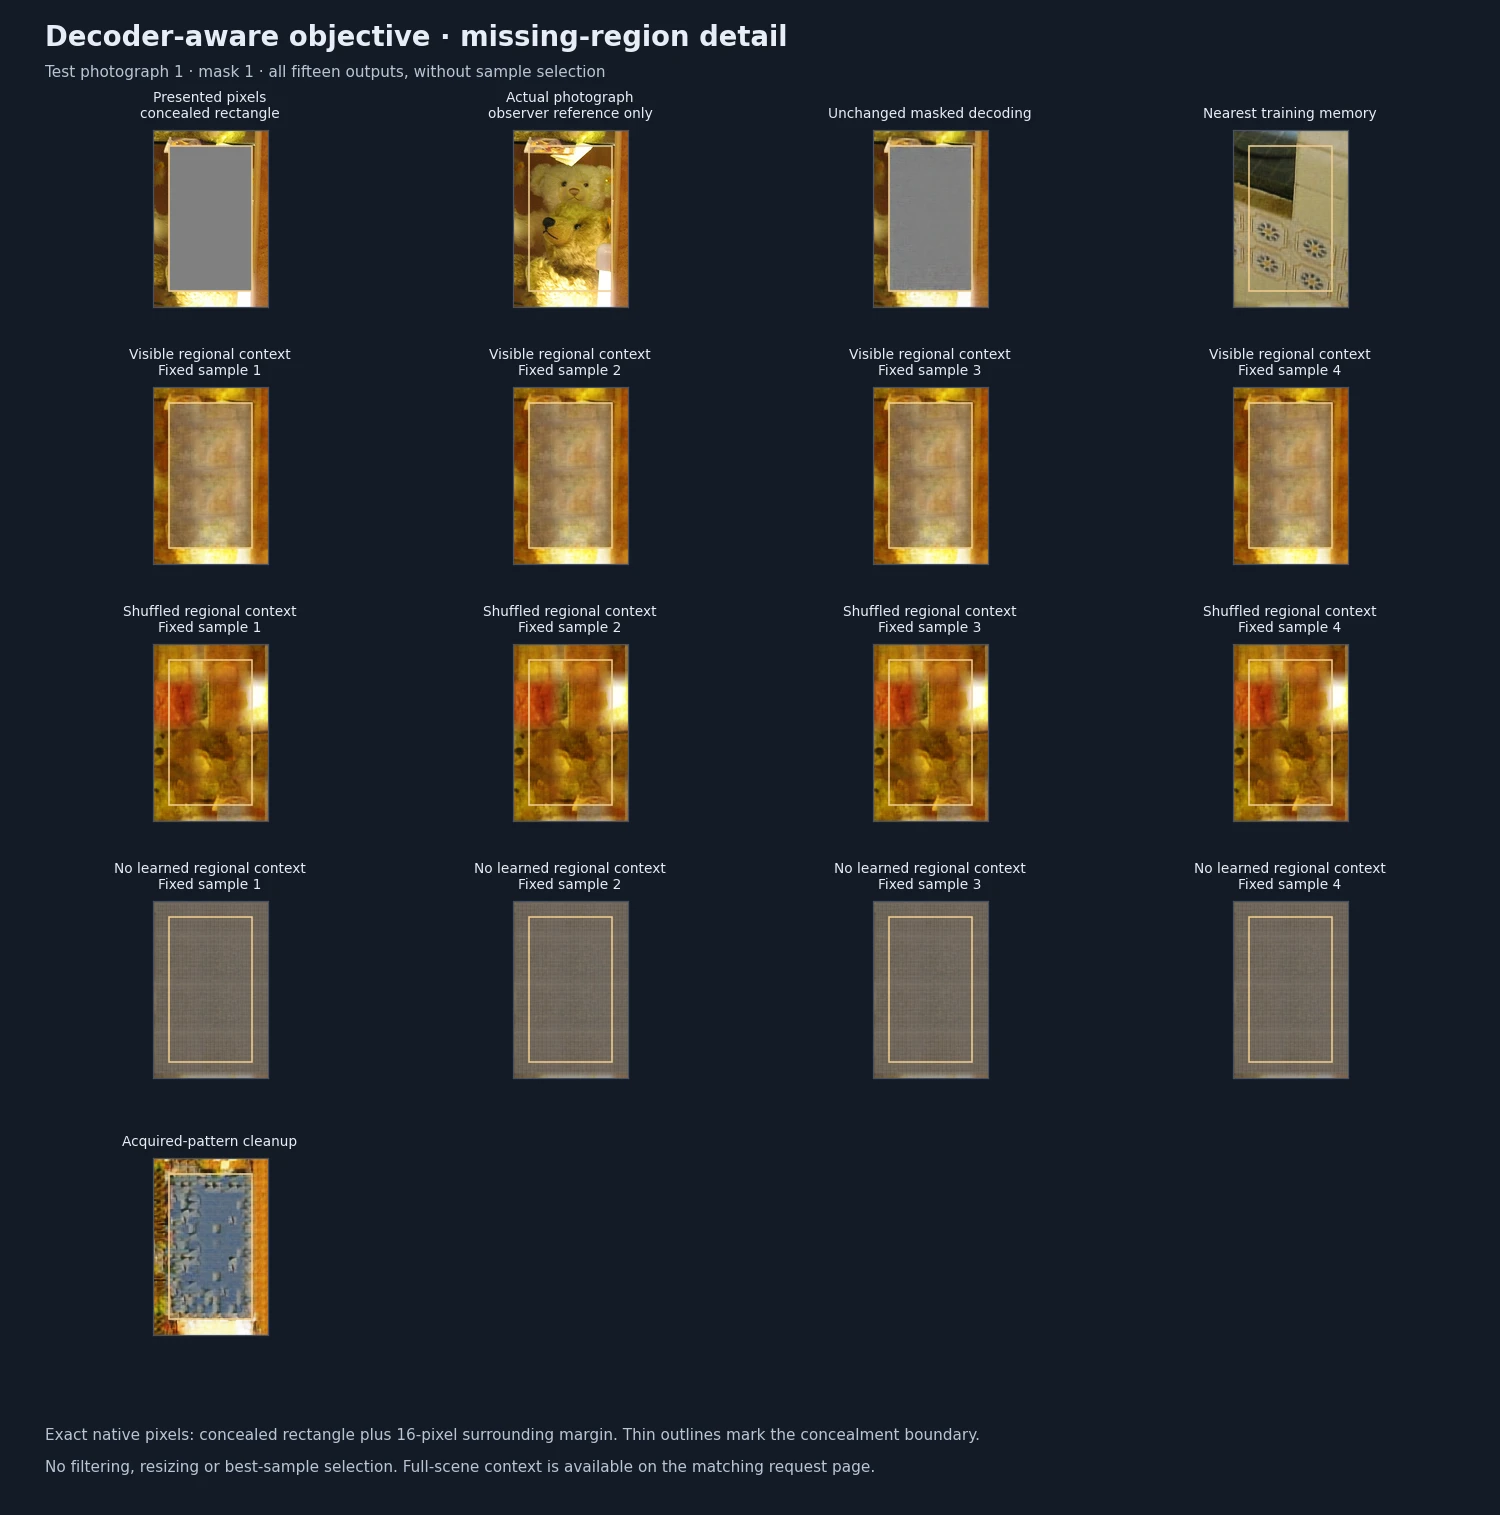
Display derivative: WebP quality 90; maximum edge 2400 px. Original scientific pixels remain in the source run; do not measure this preview.
Limits and next question
This is one fixed loss intervention, not a search for the best architecture or coefficient. The codec saw the training collection. Fresh development and test sources are outside recorded prior exposures. Privileged noisy-target denoising is separate from target-denied completion. Numerical improvement alone cannot establish coherent completion; the 363-encounter life remains fixed. On preserved figures, 'No learned regional context' means 'No image context supplied to predictor': the same trained network receives zeros for both regional image vectors and its coarse image overview. Its learned weights, geometry, visibility mask and noise remain. After prediction, wholly visible regions are restored, and the final renderer still receives the shared masked overview. The photograph therefore remains context for the overall system. The causal question is: Does supplying the photograph to the predictor help beyond the photographic information already supplied to the decoder? This is neither an untrained model nor a final image produced without any context.
Next question. Compare both objectives on complete fixed panels, including visible damage, uncertainty and every sample. Interpret this intervention before selecting another change.
Inspect the evidence
Download the methods and measurements for this experiment. Large training and saved-state files are not included.